Research
-
Research
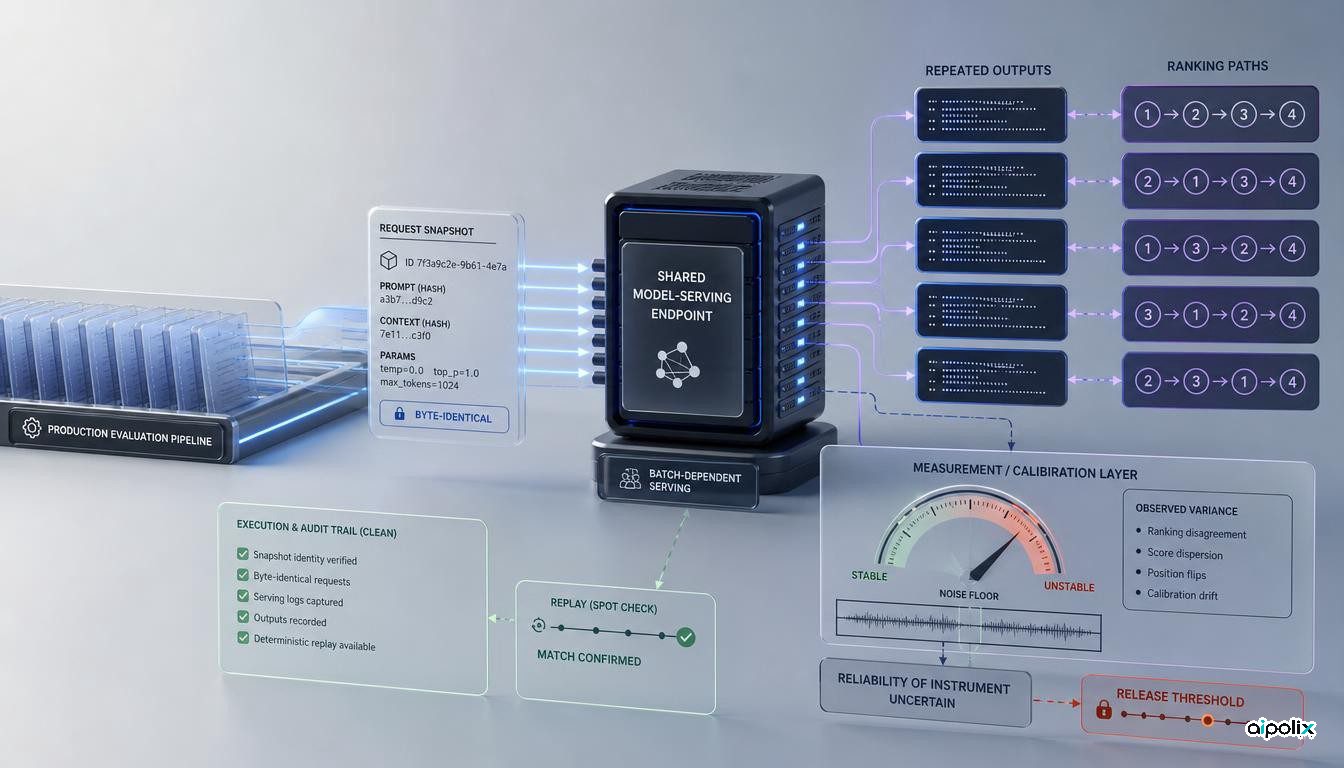
Shared API drift can invalidate LLM-as-judge release gates
A preregistered audit finds shared LLM endpoints can undermine hard judge gates, pointing to an instrument-qualification step for production evaluation.
-
Research
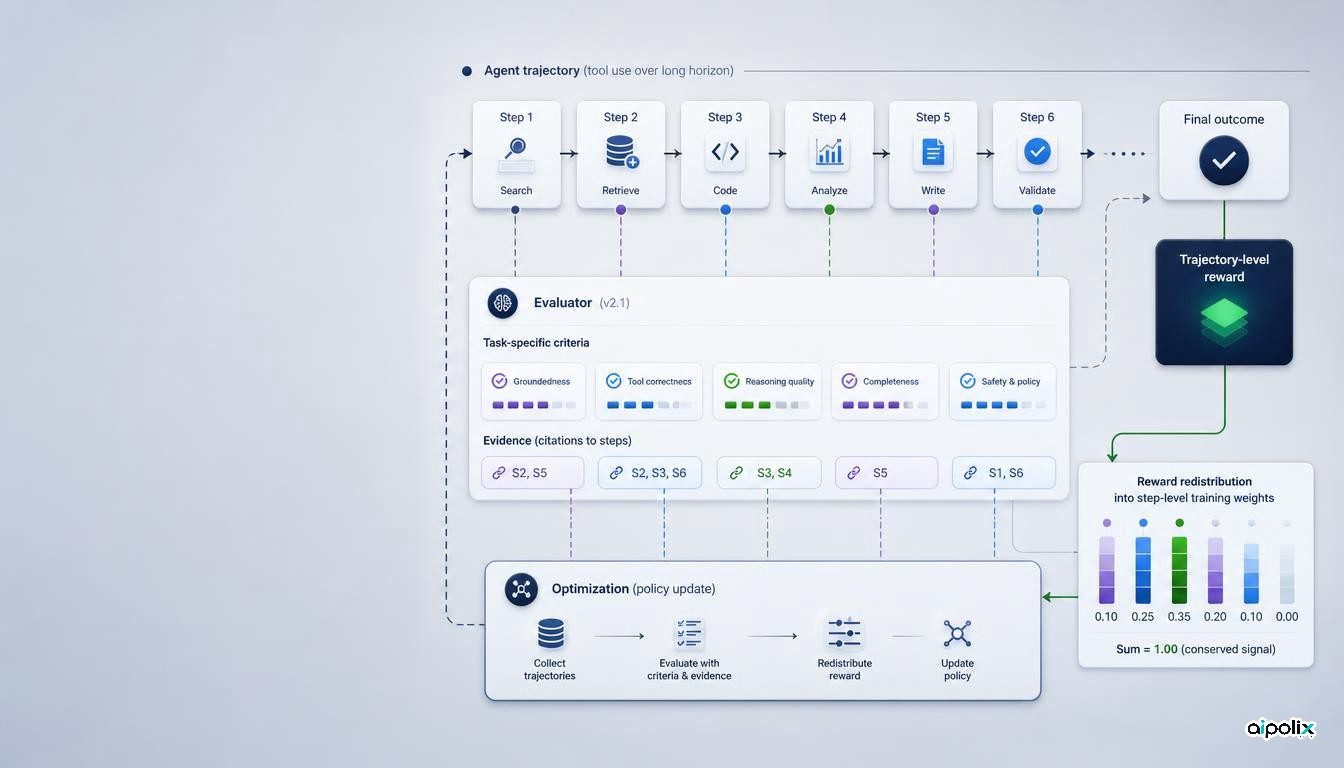
DRACO turns agent-evaluation evidence into step-level training credit
IBM's DRACO redistributes rubric-based reward across agent steps, with open code and a source discrepancy that highlights the need for reproducible evaluation.
-
Research
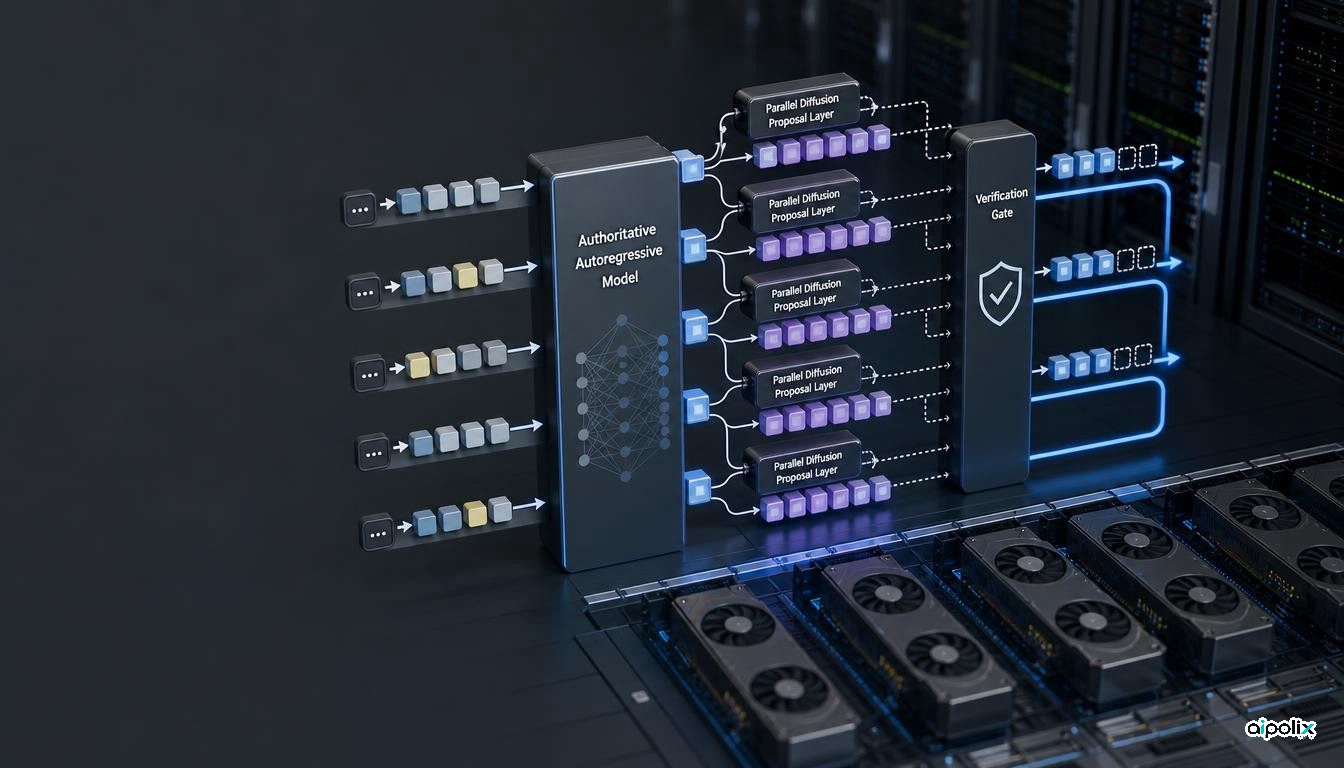
Uno turns diffusion into a lossless speed layer for autoregressive LLMs
Uno combines autoregressive LLMs with diffusion adapters and Ψ-Spec verification, releasing code and checkpoints for parallel, distribution-preserving decoding.
-
Research
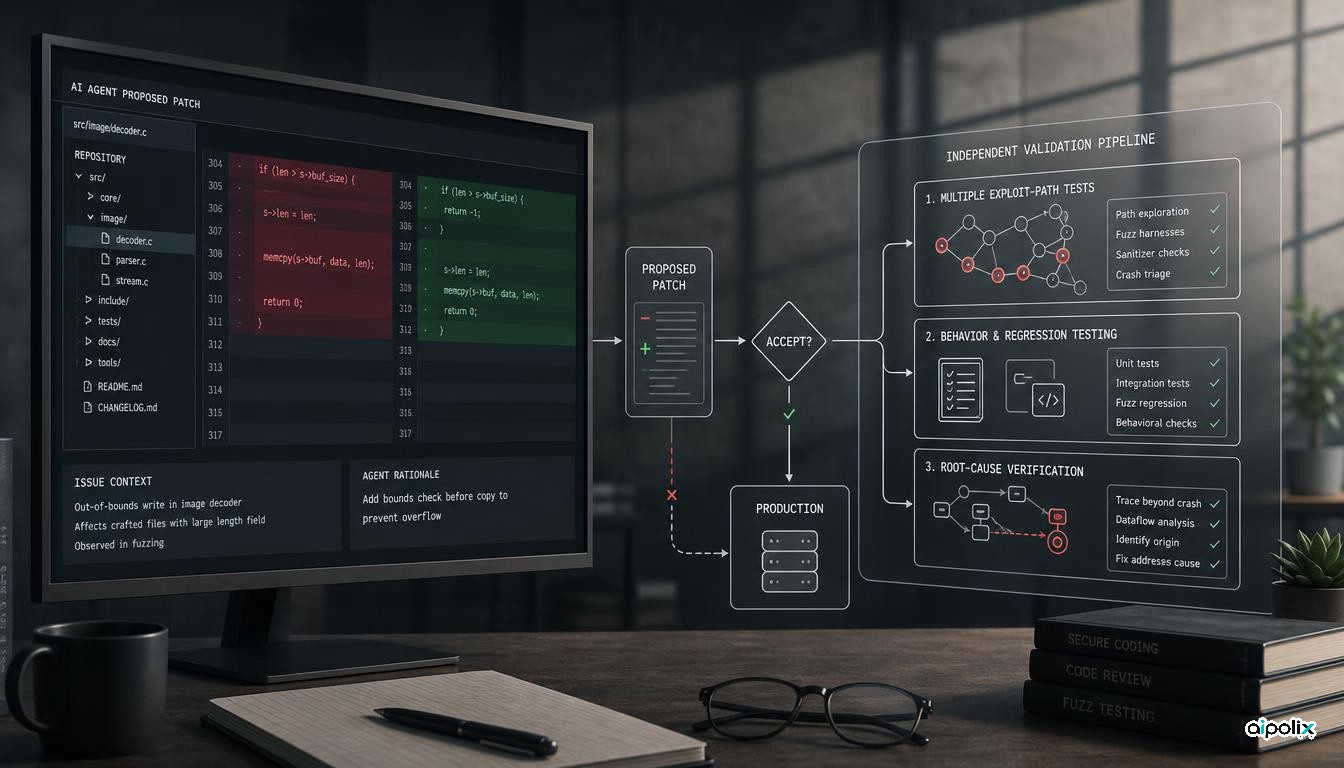
PatchBench shows why a stopped crash is not a verified AI security fix
PatchBench finds that single-PoC checks can overstate AI vulnerability-patching success and argues for independent security and semantic validation.
-
Research
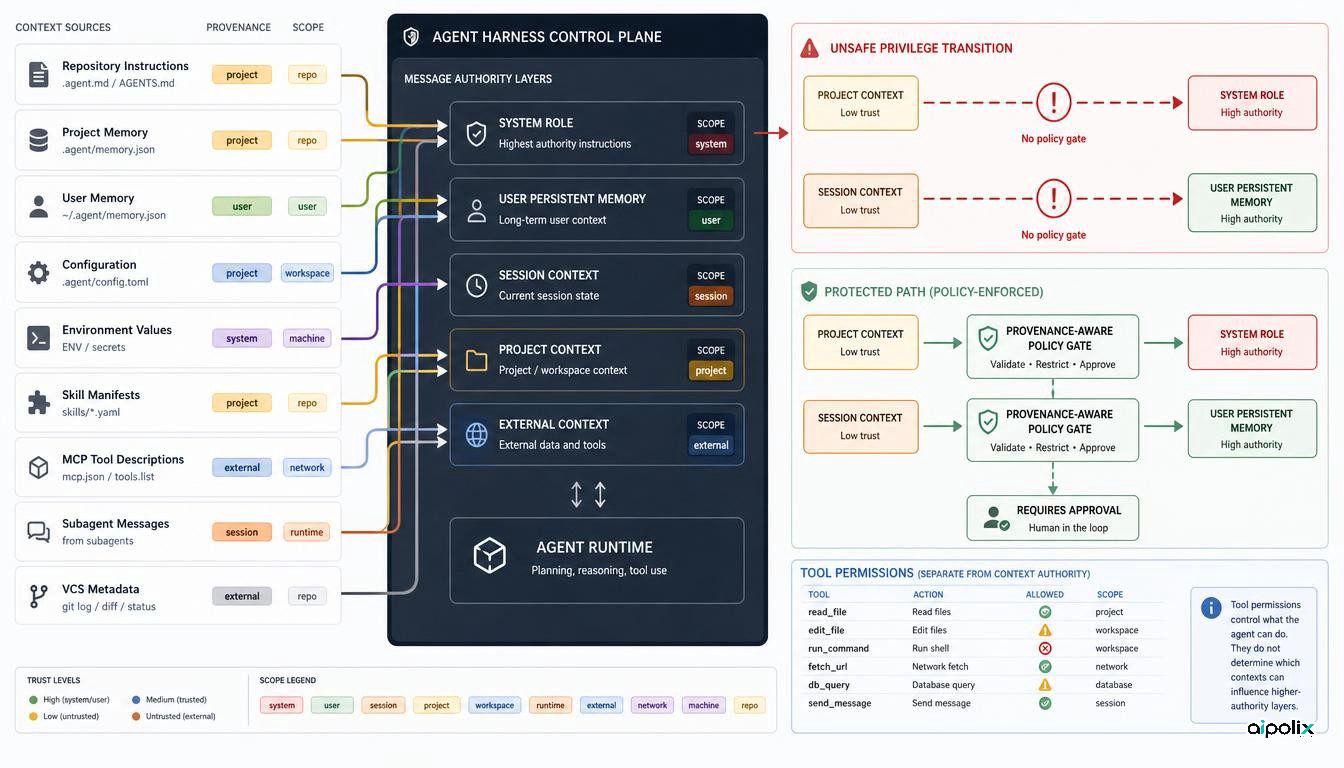
Context privilege escalation turns agent memory into a security boundary
A study across 12 agent harnesses shows how context can gain authority across roles and scopes, making provenance-aware non-escalation controls a runtime requirement.
-
Research
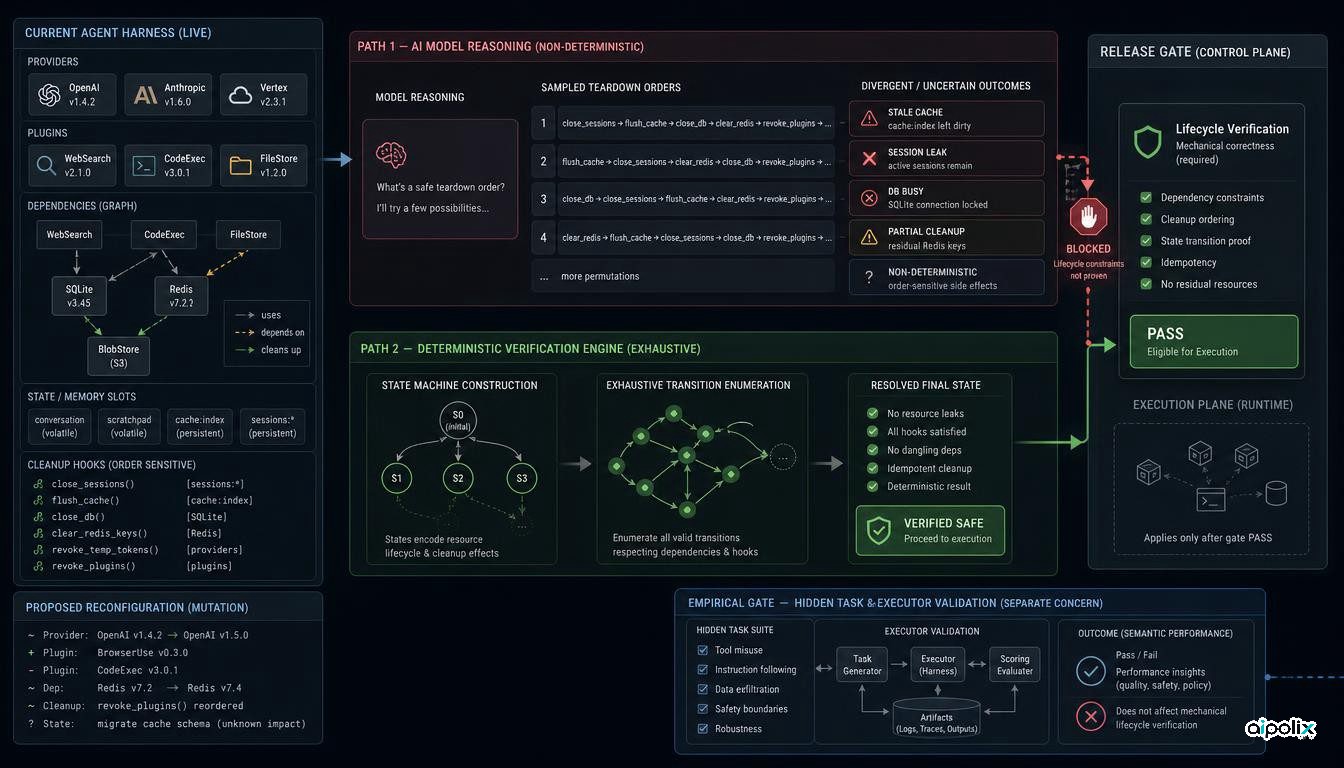
CordisBench shows where agent harnesses should replace reasoning with verification
CordisBench finds that models struggle with growing harness lifecycle interactions even when software can compute the tested state consequences exactly.
-
Research
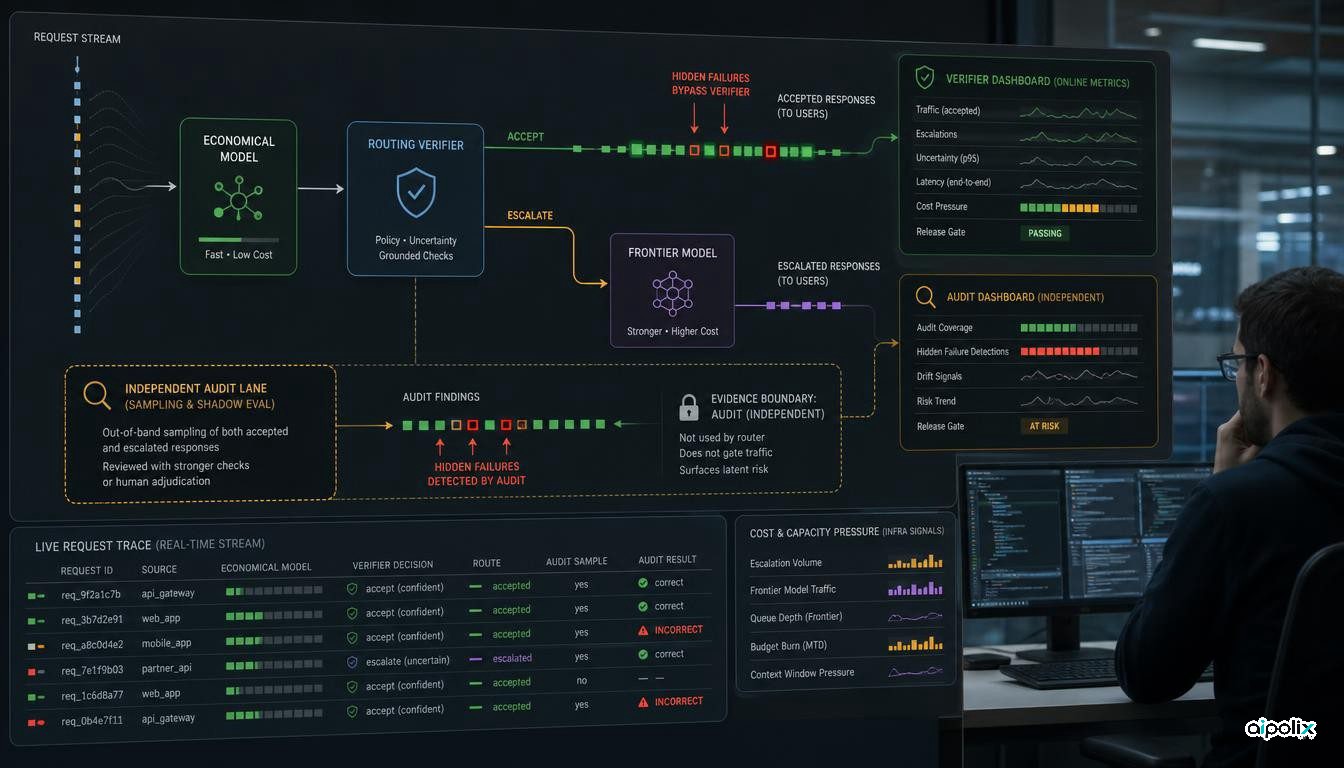
Cheap verifiers can make AI cascade dashboards blind to real errors
New research shows why LLM cascade routing and quality monitoring should not rely on the same verifier without an independent audit path.
-
Research
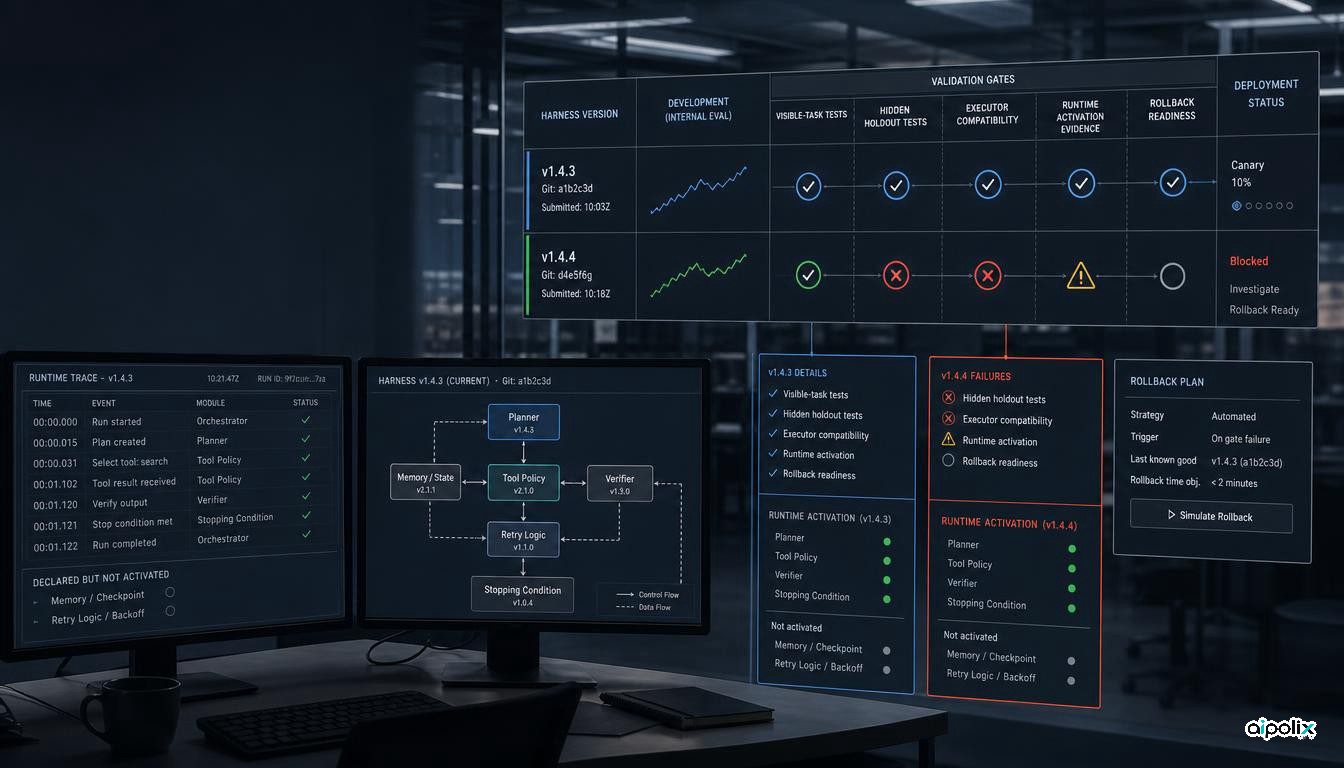
HarnessDev shows why self-improving agents need release gates
HarnessDev shows why evolving AI agent harnesses need hidden-task validation, executor checks, runtime evidence and rollback before promotion.
-
New Models
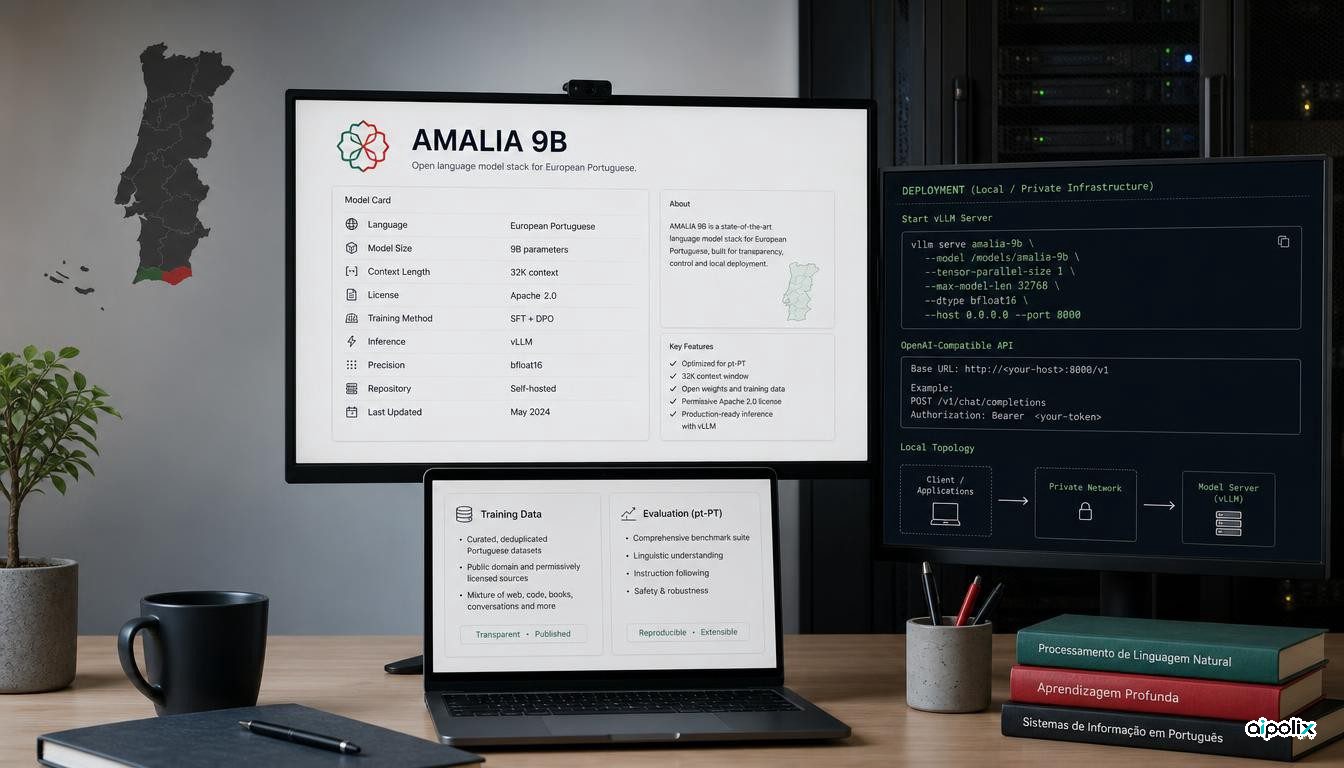
AMALIA opens a 9B European Portuguese model with a 32K context and local deployment path
AMALIA releases a 9B open European Portuguese model with 32K context, SFT+DPO training, public evaluation resources and local vLLM serving.
-
Research
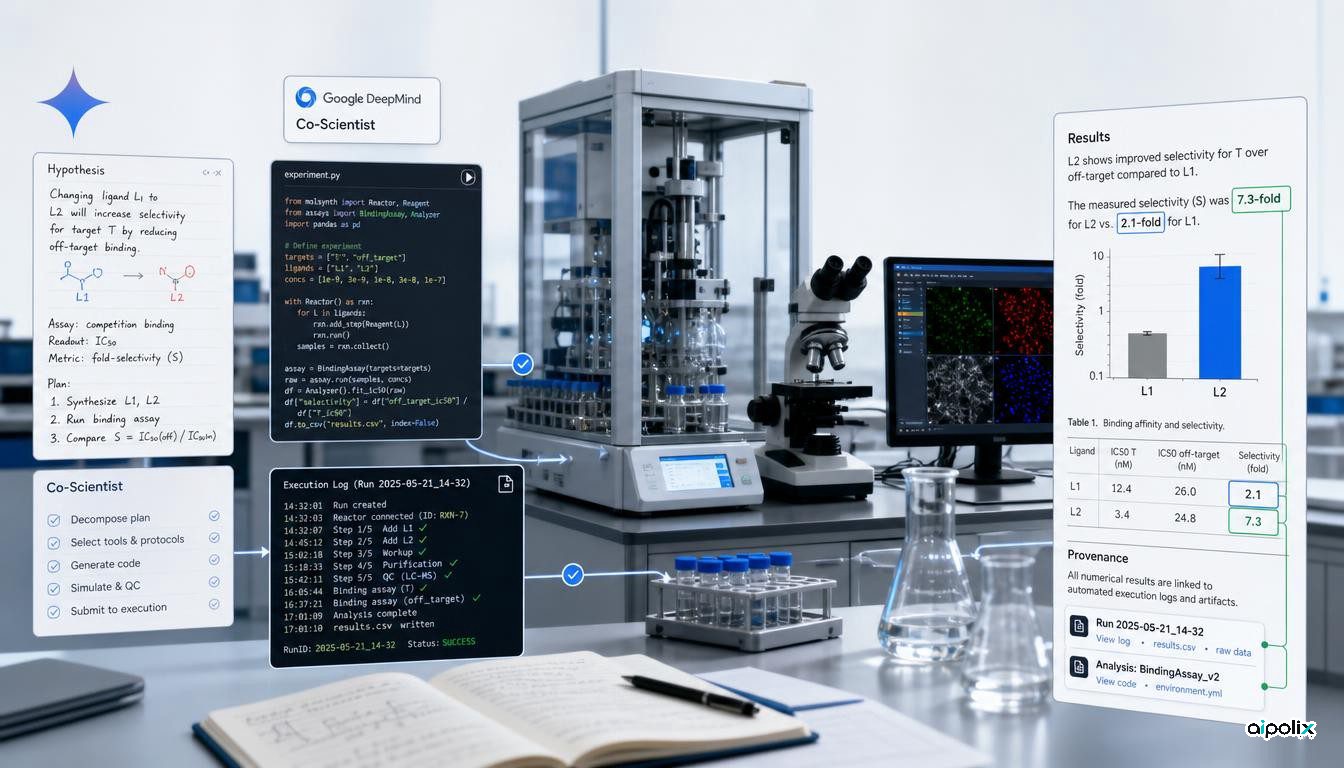
Gemini Co-Scientist closes the loop from hypothesis to experiment and verified claims
Google DeepMind extends Co-Scientist from hypothesis generation into execution-grounded research with lab workflows, autonomous code experiments and claim verification.