
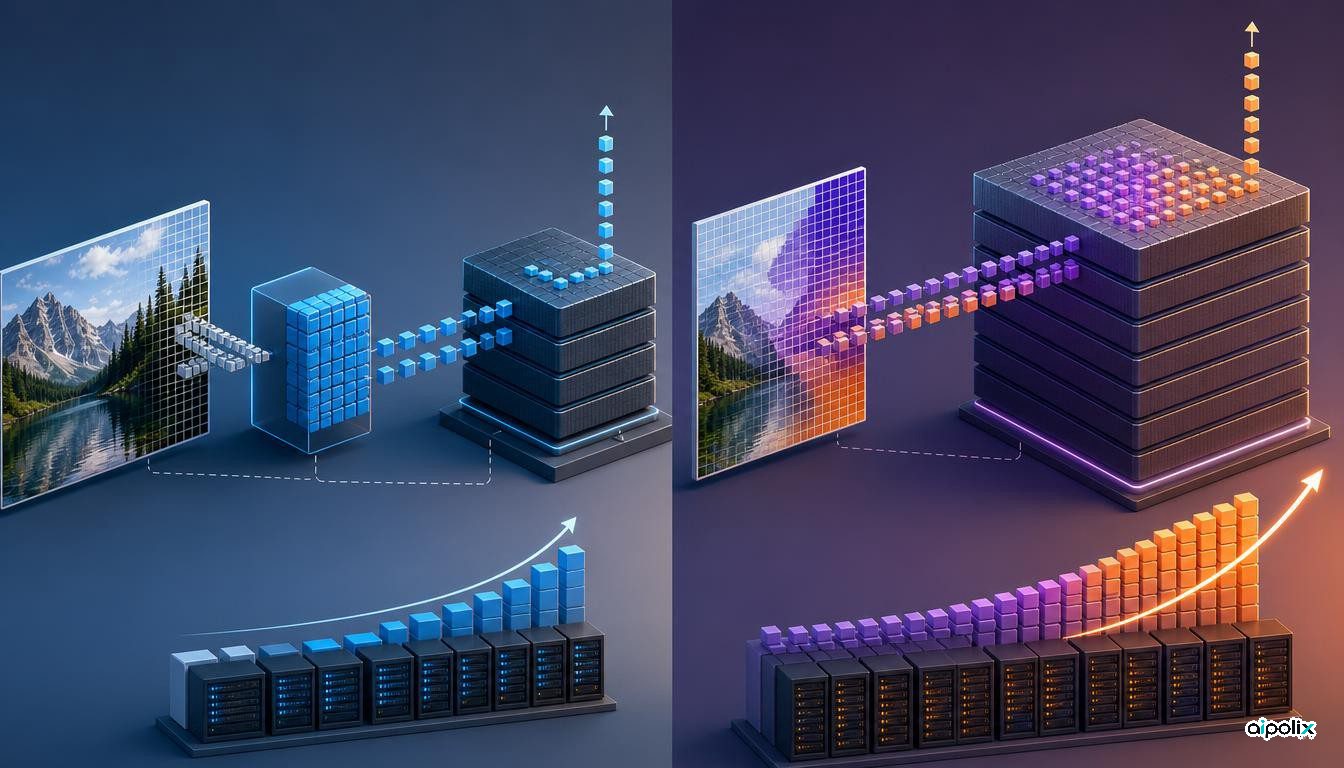
Tencent Hunyuan researchers have published a preprint examining a practical architecture question for multimodal AI: at what scale might a model learn vision directly from pixels without relying on a separate pretrained visual encoder? The study compares encoder-based multimodal language models with encoder-free systems and reports that the encoder-free approach is less compute-efficient on multimodal objectives at the scales actually tested, but improves faster as training compute increases. Fitted scaling laws project a possible catch-up around 10^22 FLOPs.
That projected crossover is the most important result and also the most important limitation. The researchers did not observe it directly. Their estimate extends a fitted trend beyond the measured range, so it should be treated as a hypothesis about scaling rather than a demonstrated threshold. The paper is also a preprint, and its conclusions depend on the model families, data, optimization choices and evaluations used in the experiments.
What changes in the architecture question
Many multimodal language models use a pretrained visual encoder to transform images into representations that a language model can consume. That arrangement provides a strong visual prior and can make training efficient because the language model does not need to learn the entire visual representation pipeline from raw pixels.
Encoder-free systems remove that specialized front end. The decoder must learn useful visual representations alongside language and multimodal reasoning. In the Tencent Hunyuan-led experiments, text-objective scaling is reported to be similar between the two approaches, while encoder-free models trail on the multimodal objective at smaller tested scales. The fitted curves, however, improve faster for the encoder-free design.
This reframes the engineering decision. The question is not simply whether encoder-free multimodal learning works. It is whether the simplicity of a unified architecture can eventually compensate for its higher training cost at practical scales.
The decoder appears to specialize for vision
The paper also studies how the encoder-free decoder changes internally. The authors report that bidirectional interaction among visual tokens becomes more useful as compute grows, that visual processing shifts toward earlier layers, and that expert routing for visual tokens becomes more concentrated.
Those observations are consistent with the decoder developing computation that is increasingly specialized for vision. For mixture-of-experts and multimodal system designers, that matters because removing a visual encoder does not mean visual specialization disappears. It may instead move inside the shared model, changing where capacity, routing and compute need to be allocated.
The result therefore argues against a simplistic reading of architectural unification. A single decoder can still develop modality-specific behavior. The potential benefit is a simpler external architecture and more jointly learned representations, not the elimination of specialized computation.
Why 10^22 FLOPs is not a proven threshold
The projected crossover near 10^22 FLOPs sits outside the measured range. Encoder-free models remain less compute-efficient on the multimodal objective and produce lower downstream scores at the scales tested. Scaling-law extrapolations can move when training recipes, data mixtures, model families or evaluation tasks change.
For teams making deployment or training decisions today, the measured evidence still favors pretrained visual encoders when compute efficiency is the priority. The projection is more useful for planning experiments than for justifying an immediate architecture migration.
Aipolix's interpretation is that this work turns encoder-free multimodal design into a compute-allocation question. If future experiments observe the predicted crossover, unified multimodal decoders could become more attractive at frontier training scales. If the crossover shifts substantially under other recipes, specialized visual encoders may retain their advantage much longer.
What to watch next
The strongest confirmation would be a larger controlled training run that actually crosses the predicted point while preserving comparable data, optimization and downstream evaluation. Replication across different model families would also show whether the reported scaling behavior is general or specific to this setup.
Until that evidence arrives, the paper provides a useful architectural signal rather than a settled design rule. It suggests that visual encoders may be partly a consequence of current compute economics, while also showing that encoder-free systems have not yet erased their measured efficiency disadvantage.
Sources
https://arxiv.org/abs/2609.35457
https://huggingface.co/papers/2609.35457