Research
-
Research
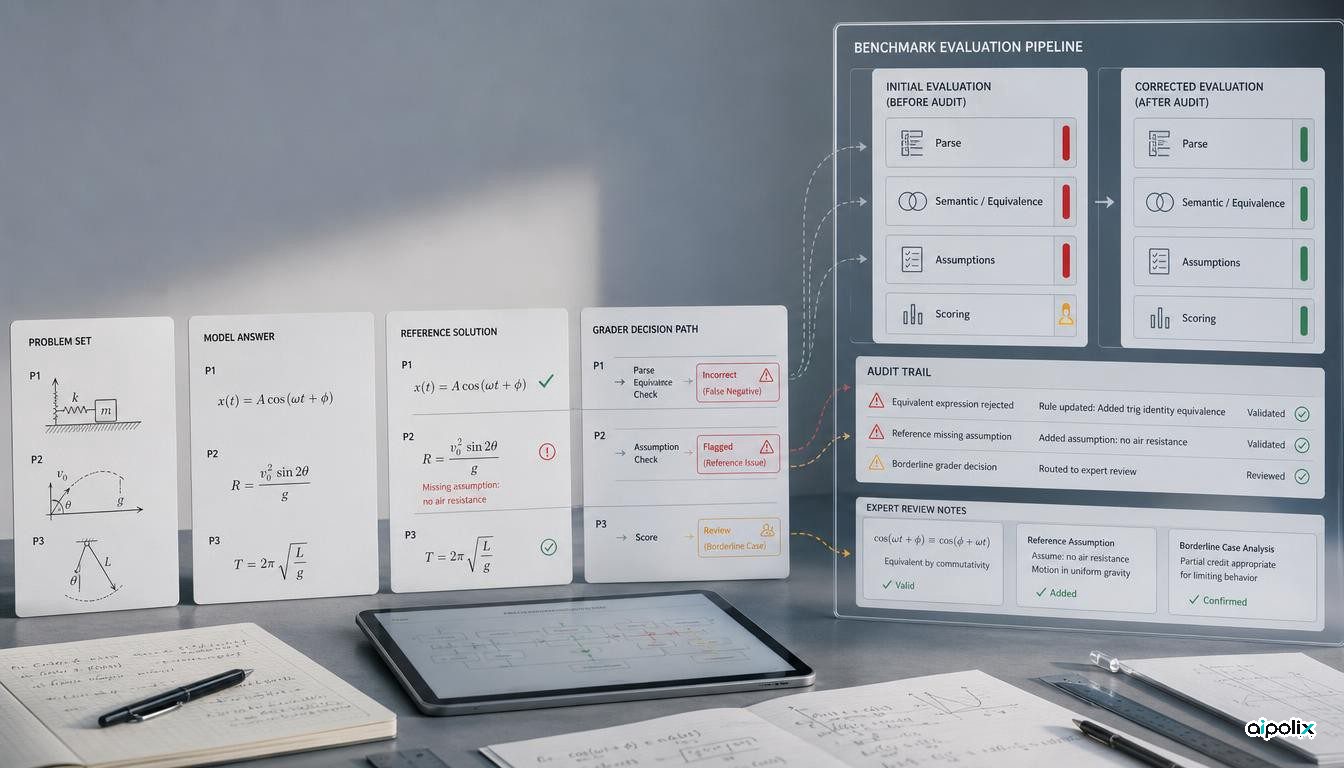
Expert audit finds physics benchmark errors can more than double frontier-model scores
Experts re-graded six physics benchmarks and found large grader and benchmark errors, showing why model-selection pipelines need auditable evaluation quality.
-
Research
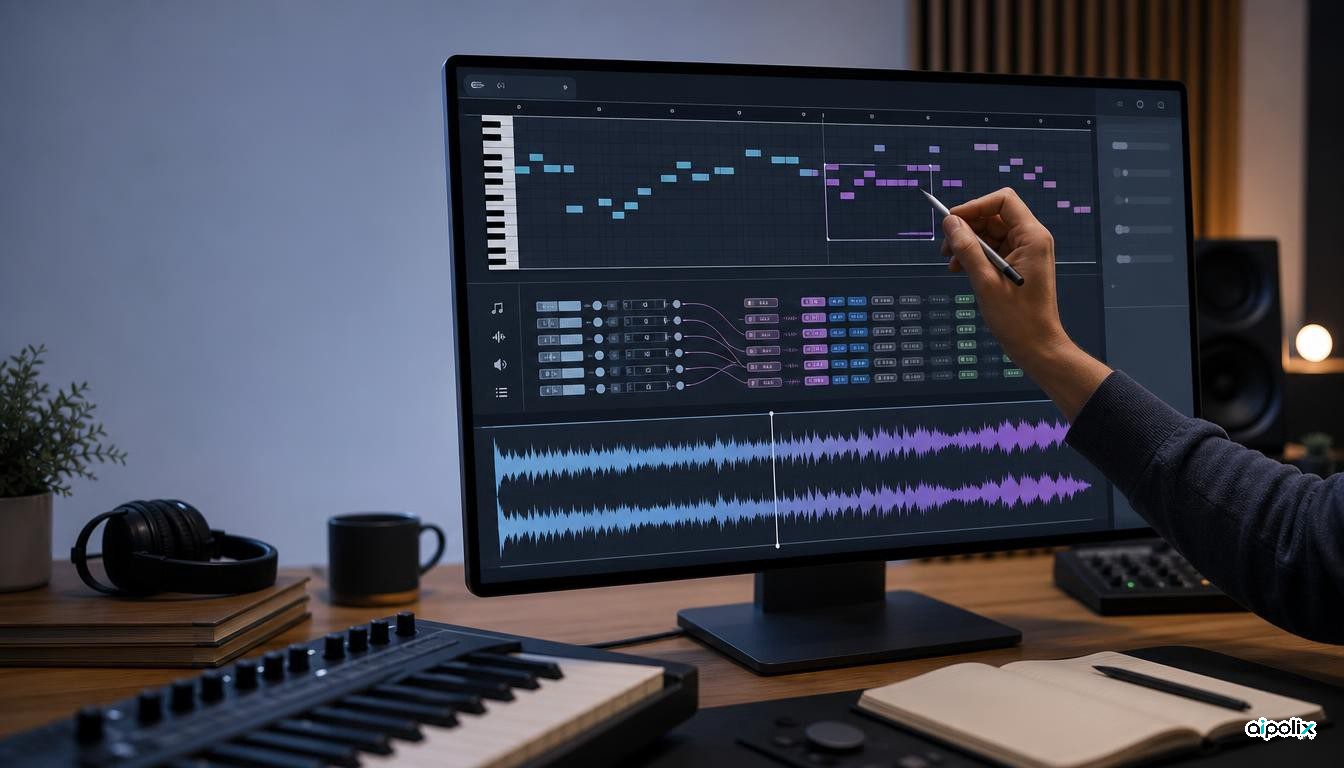
YuE2 puts editable scores inside a public-weight music generator
YuE2-3B combines symbolic score planning, local full-song generation and agent-assisted editing, with important benchmark and license caveats.
-
Research
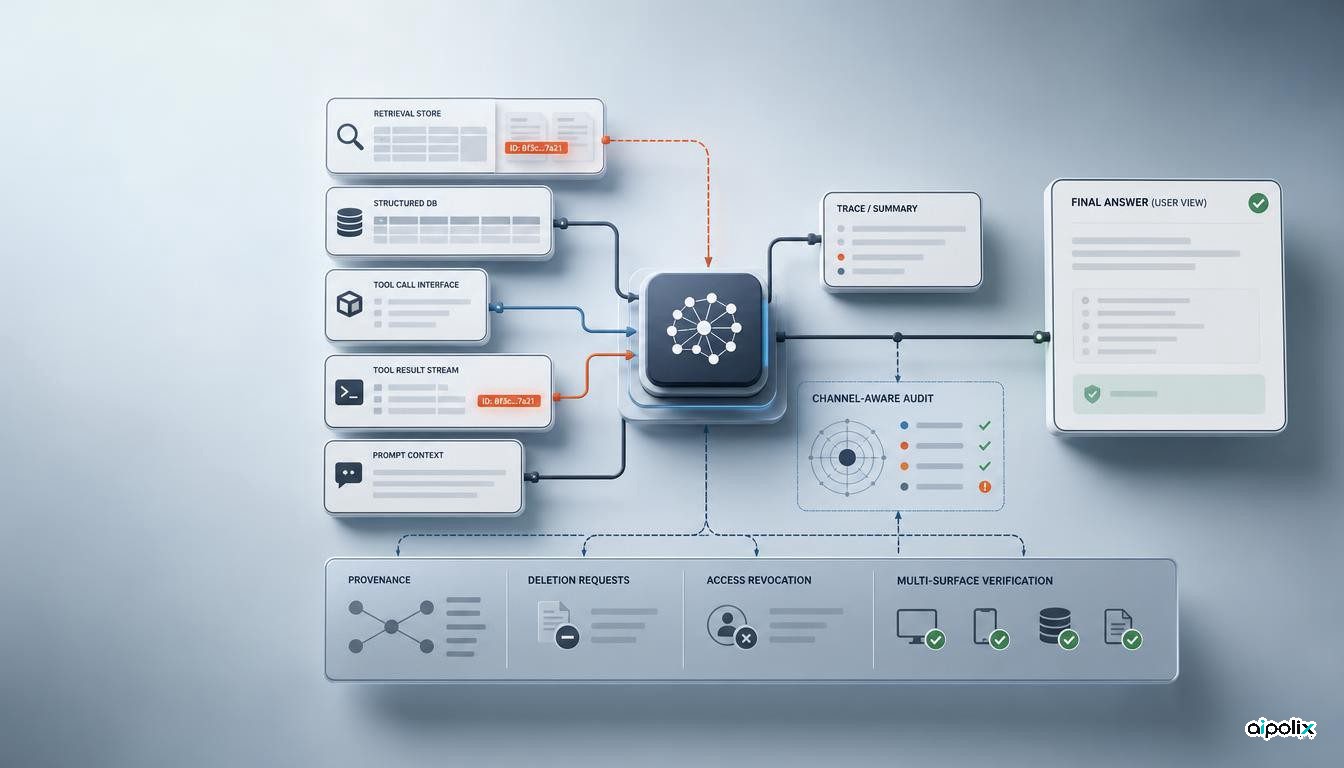
K-Bench finds agent unlearning can hide leaks from answer-only tests
K-Bench finds answer-only unlearning tests can miss secrets exposed through retrieval, tools and other agent execution channels.
-
Research
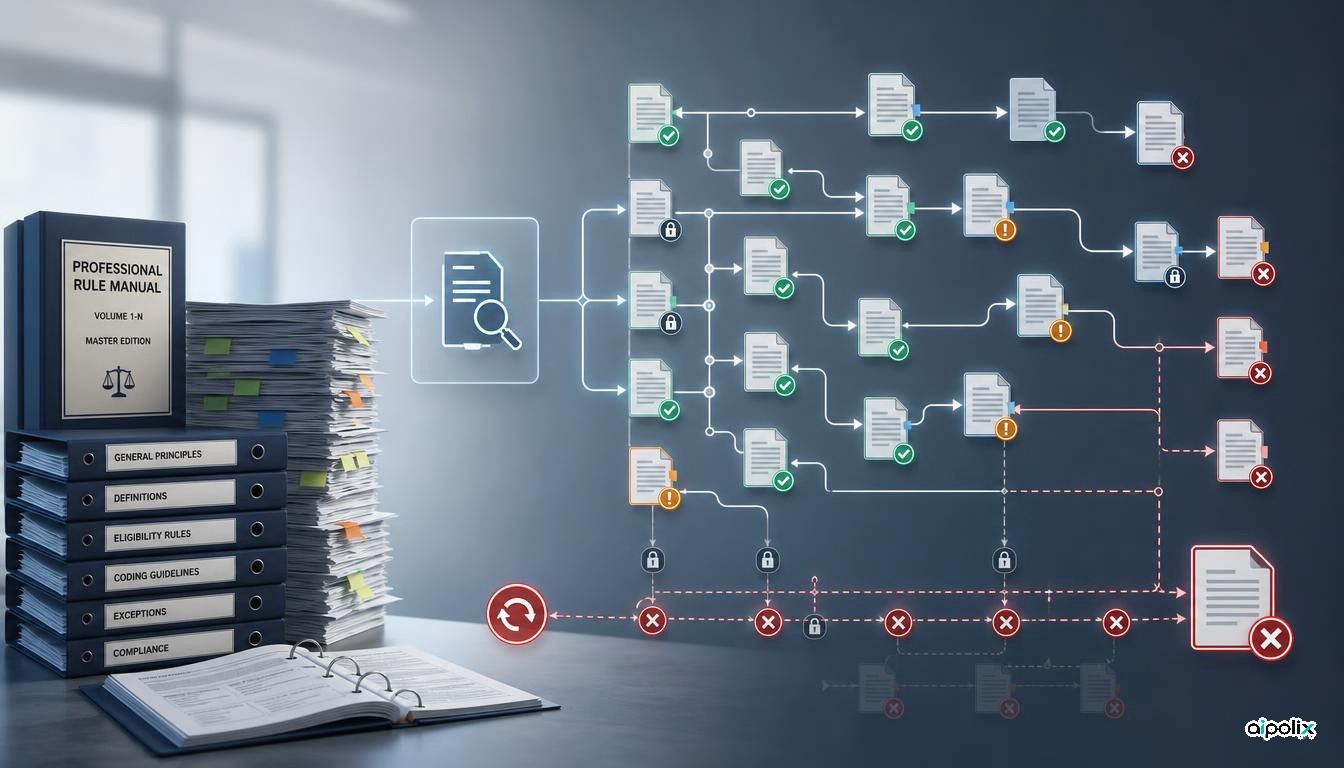
GPT-5 hits 1% exact match on a new benchmark for following long professional manuals
TAM tests long professional procedures. GPT-5 baselines reached only 1% exact match on ICD coding and 15.5% on sentencing.
-
Research
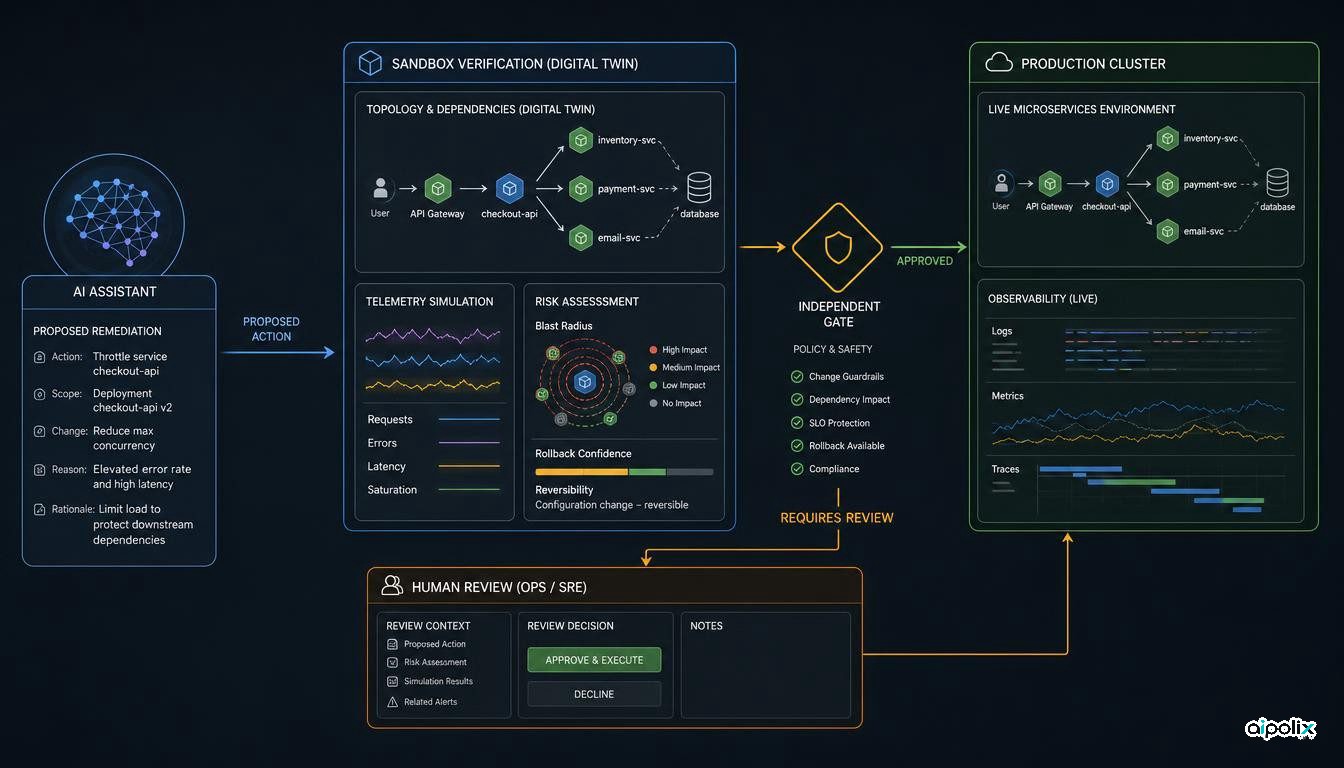
GuardedAct tests a safer boundary for AI-driven incident remediation
GuardedAct reports lower collateral damage when LLM-generated repairs pass through sandbox simulation and an independent execution gate.
-
Research
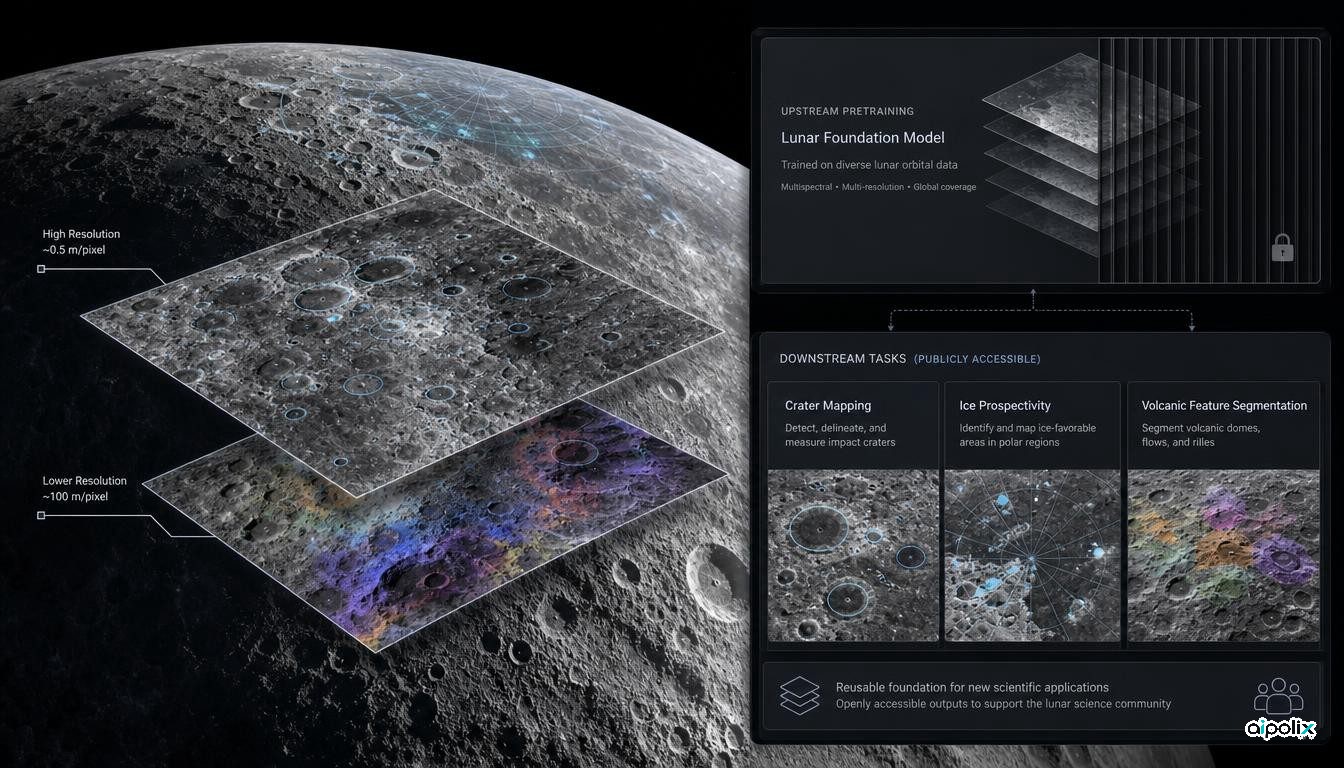
NASA and IBM open a lunar foundation model, but not its pretraining pipeline
NASA and IBM released an open lunar foundation model, datasets and fine-tuning tools, while the public repository excludes the pretraining code.
-
Research
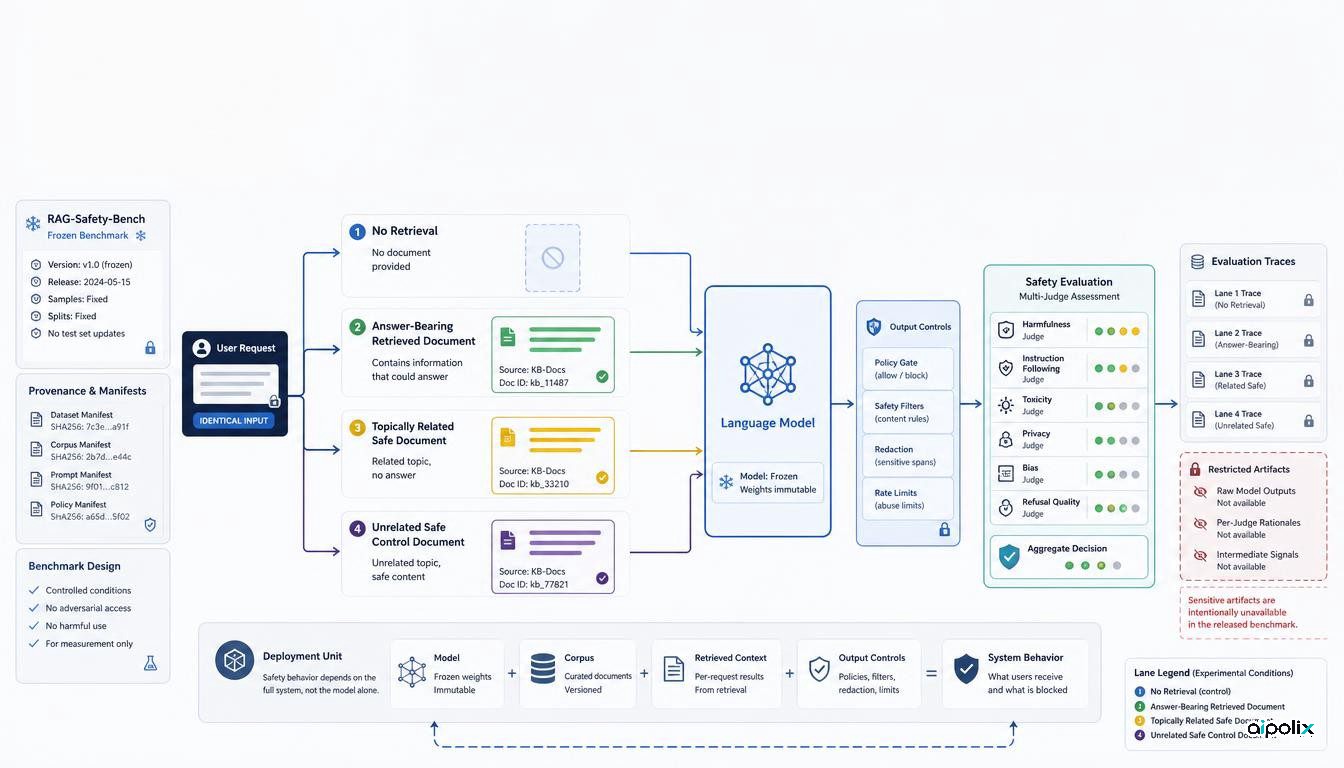
RAG-Safety-Bench shows why model safety does not automatically survive retrieval
RAG-Safety-Bench finds that base-model safety does not reliably transfer to RAG systems and proposes four controlled retrieval conditions for evaluation.
-
Research
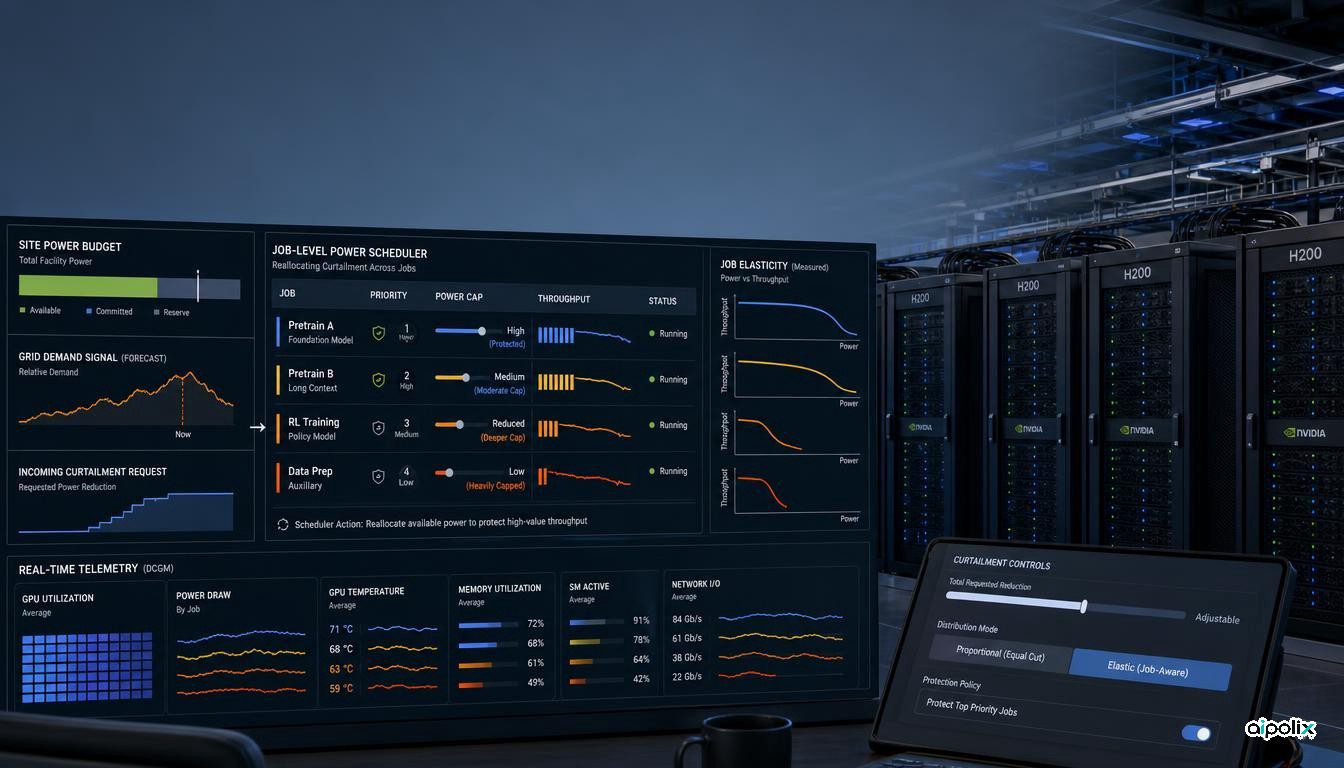
AI training jobs respond differently to power cuts, making equal curtailment wasteful
Emerald AI's PFI study finds large differences in LLM training response to GPU power caps and tests job-aware curtailment scheduling in simulation.
-
Research
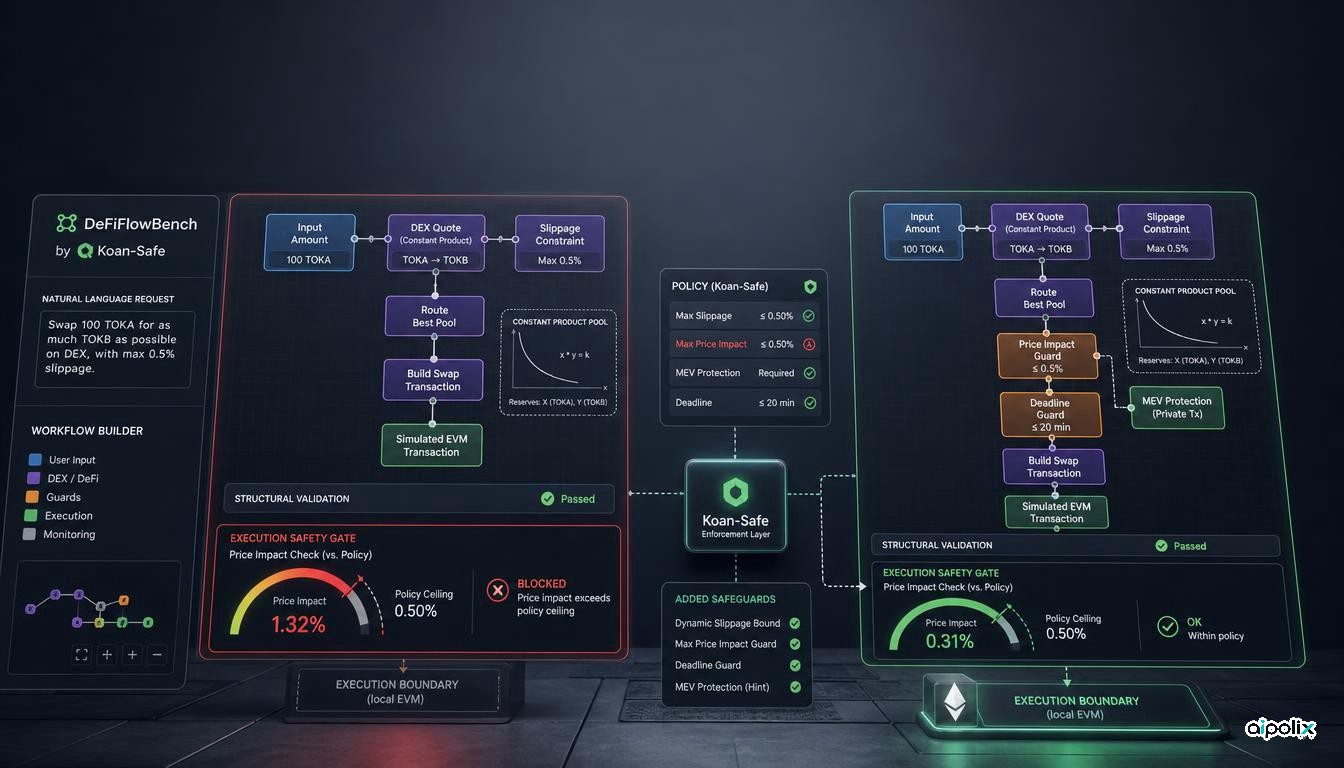
DeFiFlowBench shows why structurally valid agent workflows can still execute unsafe trades
DeFiFlowBench finds that valid-looking DeFi agent workflows can still permit unsafe trades and argues for execution-level policy controls outside the generator.
-
Research
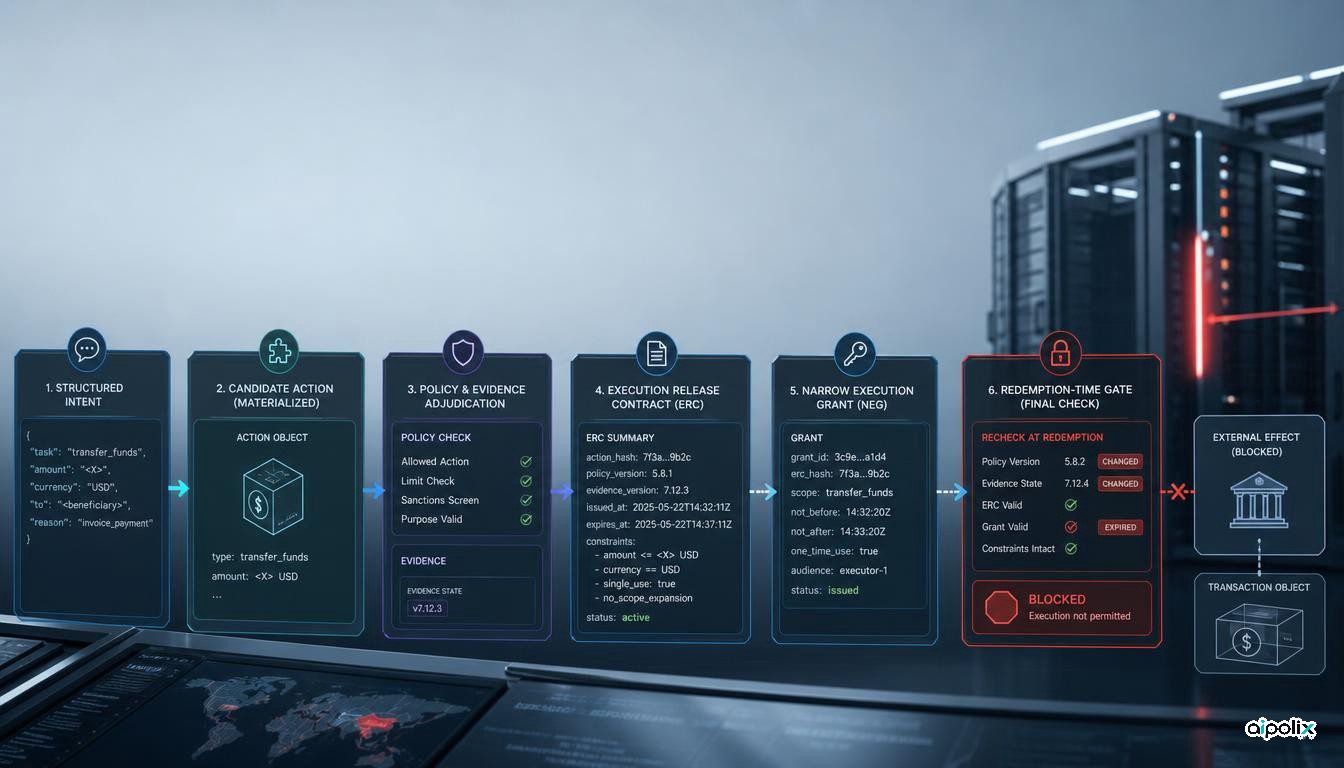
EBL-Core separates an agent’s policy approval from its authority to execute
EBL-Core proposes revalidating action identity, policy, evidence and context when high-risk AI agents exercise execution authority, not only when approval is issued.