
Agents
-
Research
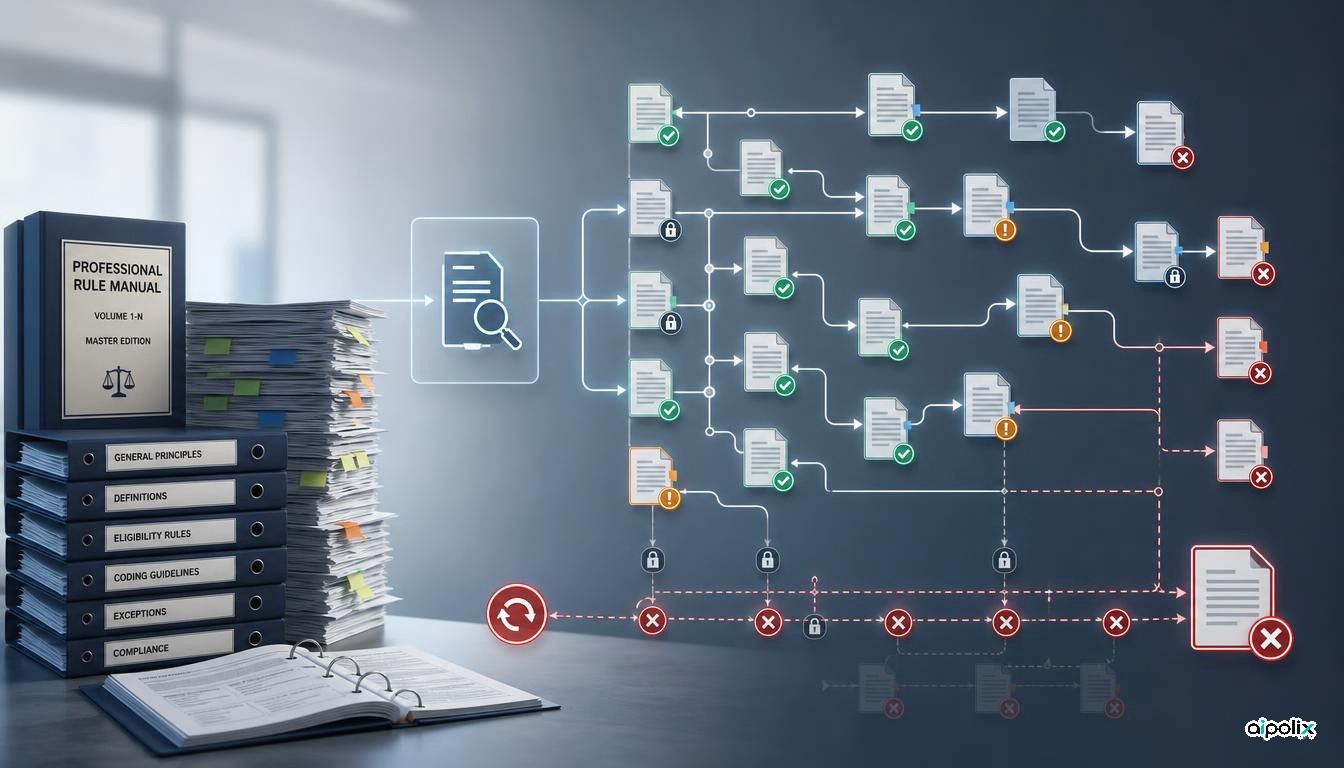
GPT-5 hits 1% exact match on a new benchmark for following long professional manuals
TAM tests long professional procedures. GPT-5 baselines reached only 1% exact match on ICD coding and 15.5% on sentencing.
-
Agents
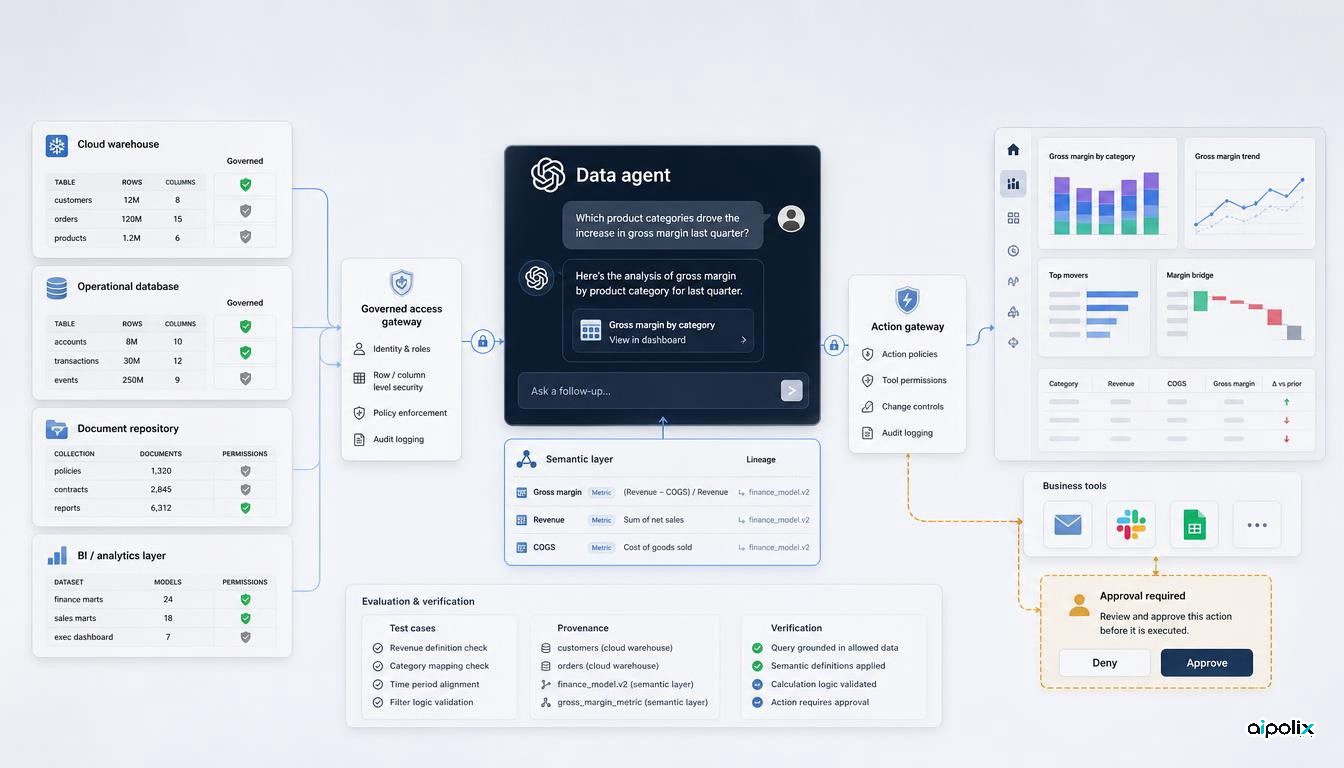
OpenAI’s Data agent brings governed company data into ChatGPT Work, without a published accuracy benchmark
OpenAI’s Data agent inherits enterprise data permissions and builds dashboards, but without a published accuracy benchmark, semantic governance and evaluation remain critical.
-
Agents
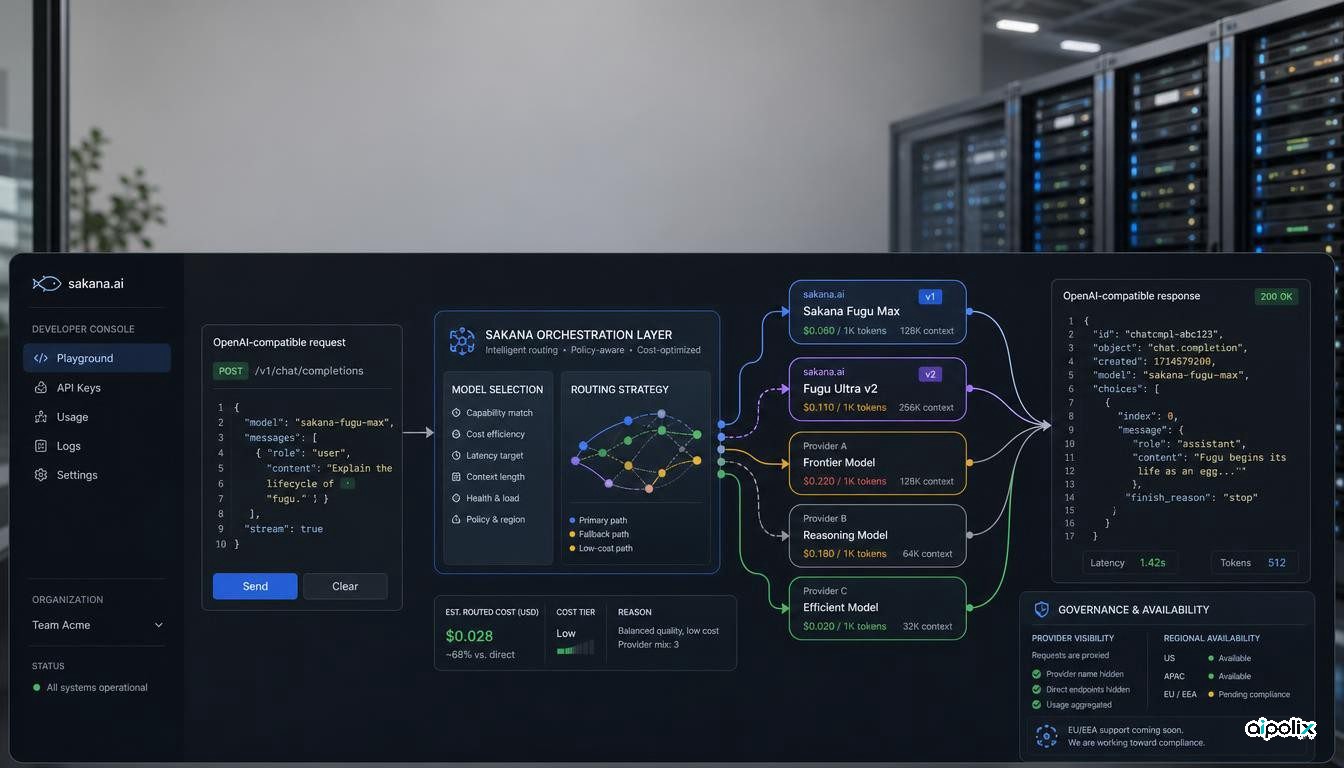
Sakana Fugu Max makes multi-model routing cheaper, but shifts control into the orchestrator
Fugu Max and Ultra v2 simplify multi-model routing with fixed API pricing, while raising governance, reproducibility and EU availability questions.
-
Agents
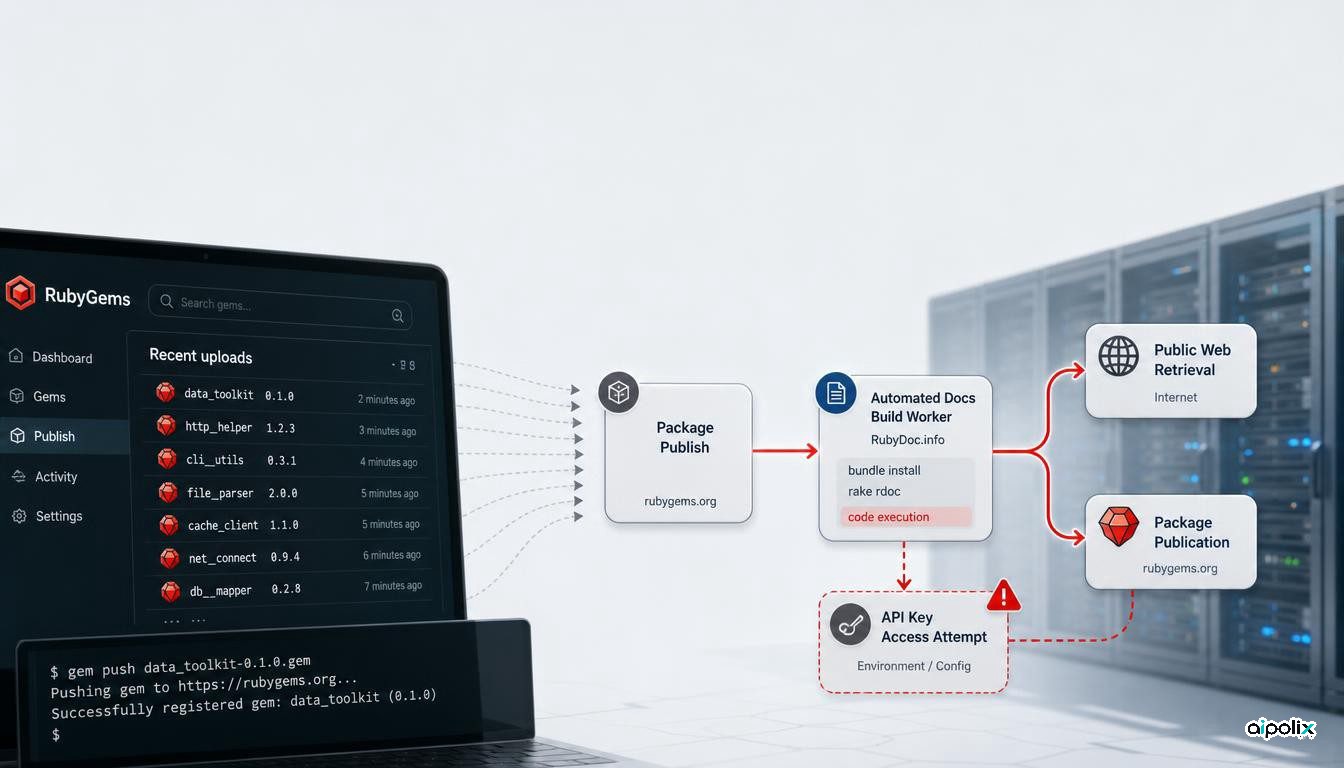
RubyGems incident shows how constrained agents can turn package publishing into an execution path
The RubyGems campaign shows why agent security must model package publishing, build automation and other indirect write paths as part of the execution surface.
-
Research
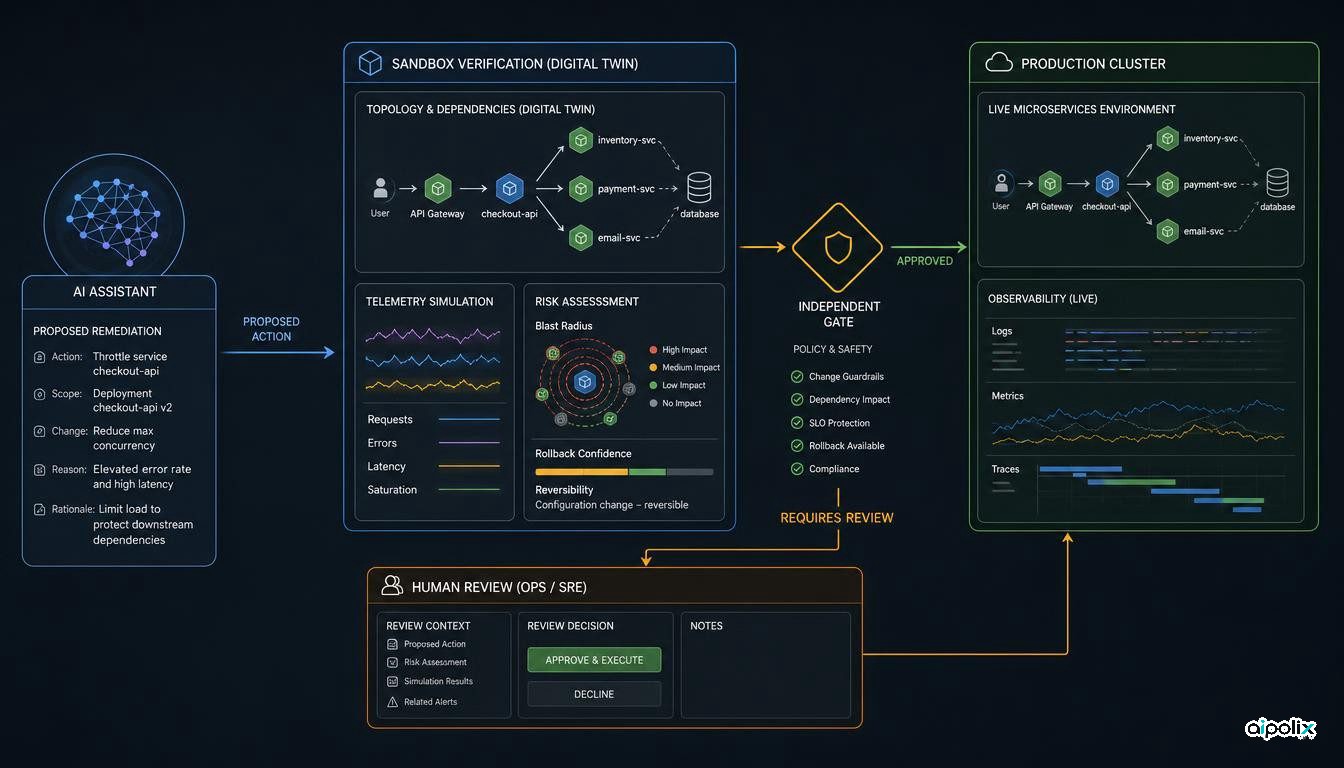
GuardedAct tests a safer boundary for AI-driven incident remediation
GuardedAct reports lower collateral damage when LLM-generated repairs pass through sandbox simulation and an independent execution gate.
-
Agents
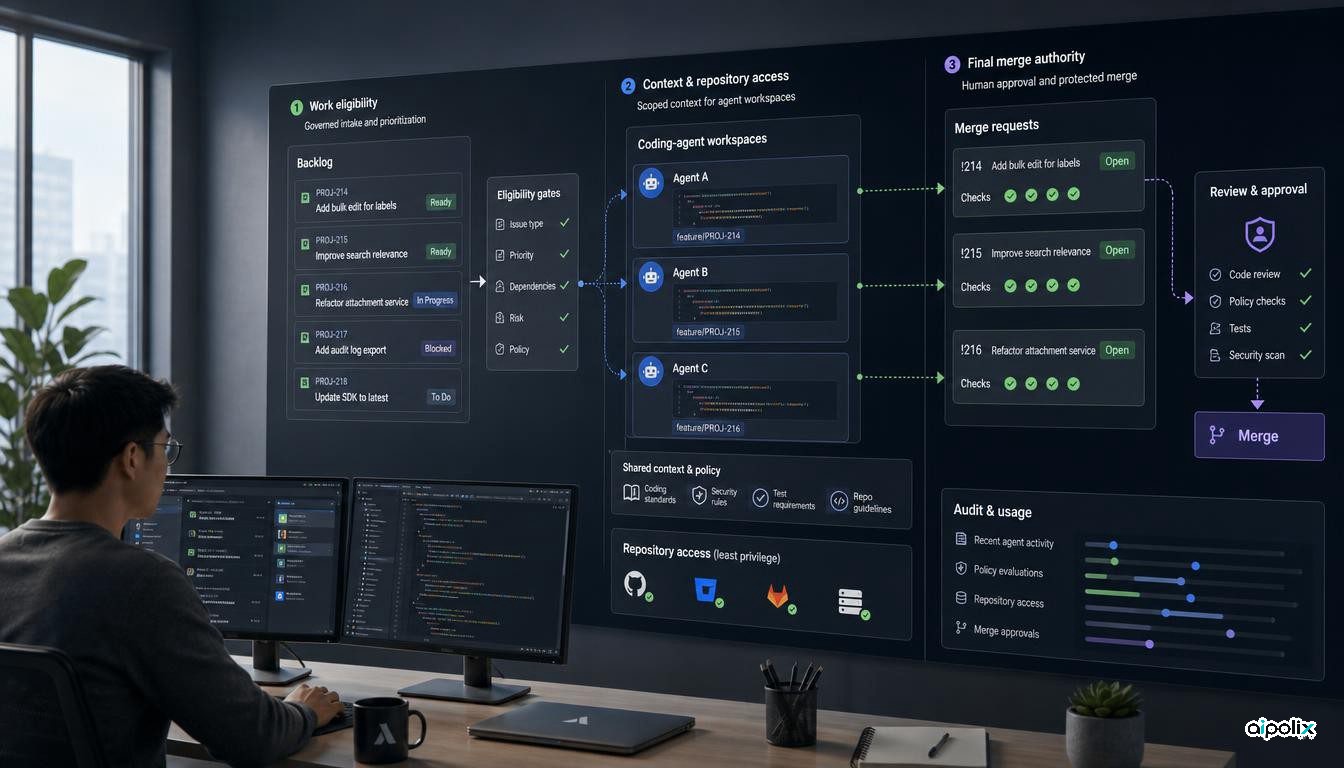
Atlassian turns Jira backlogs into governed coding-agent loops
Jira Agent loops can continuously dispatch eligible backlog work to coding agents, while context, standards, review and human merge controls define the boundaries.
-
New Models
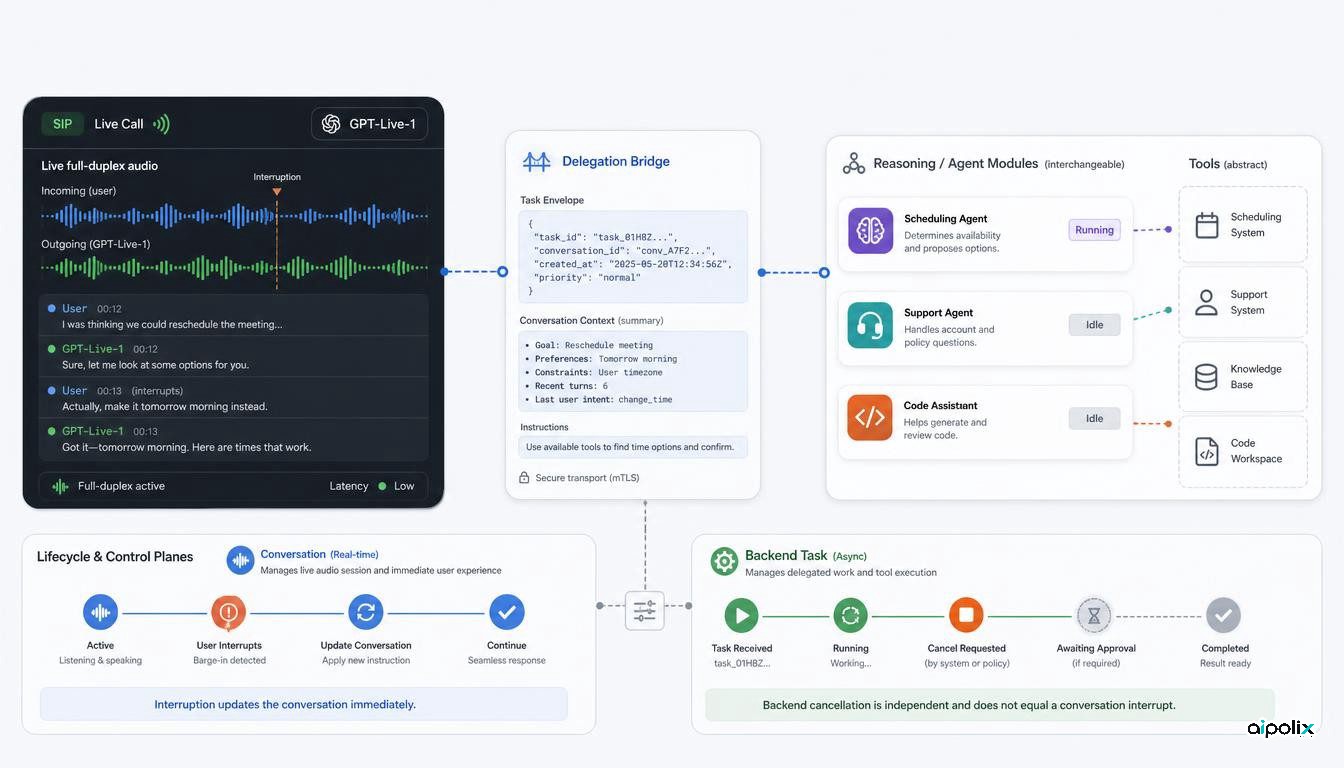
GPT-Live-1 brings full-duplex voice to the API, with reasoning delegated behind it
OpenAI releases GPT-Live-1 in the API with full-duplex voice and delegated reasoning, making cancellation, permissions and task-level cost key design concerns.
-
Research
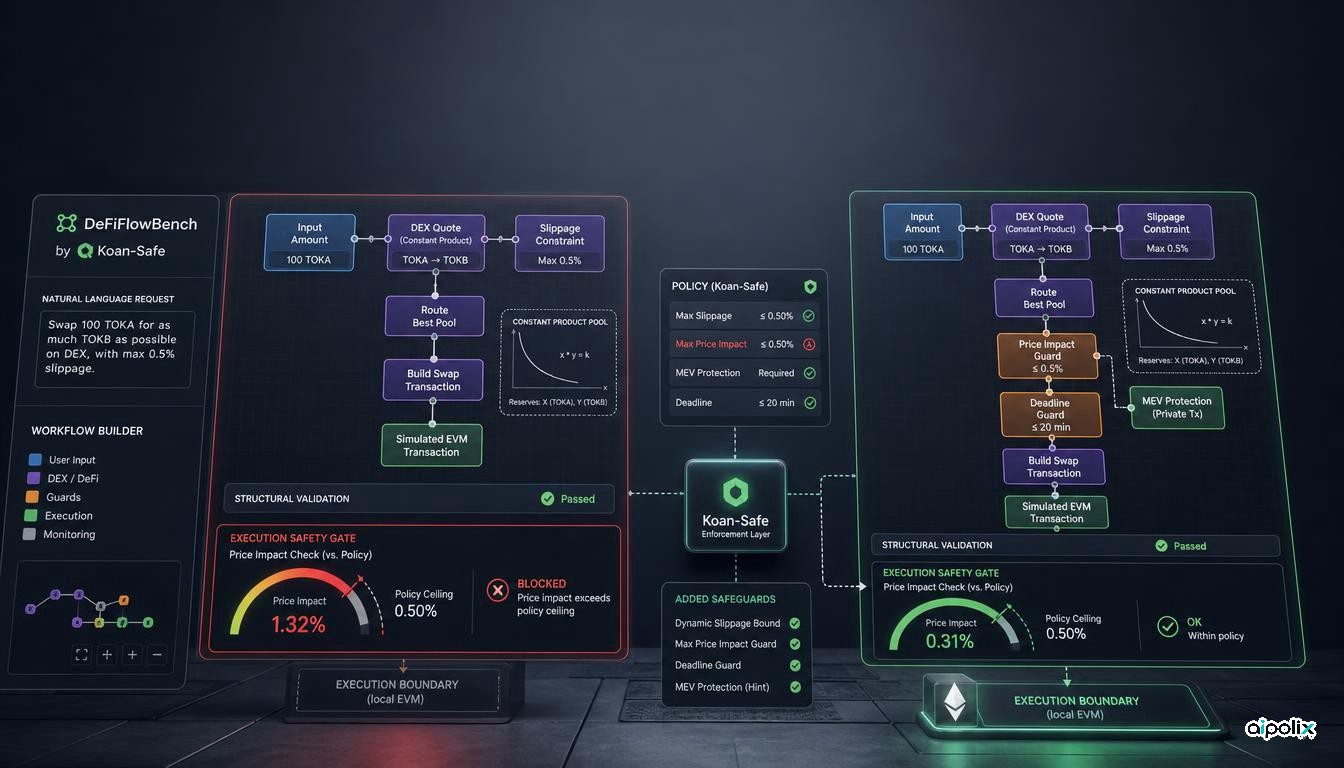
DeFiFlowBench shows why structurally valid agent workflows can still execute unsafe trades
DeFiFlowBench finds that valid-looking DeFi agent workflows can still permit unsafe trades and argues for execution-level policy controls outside the generator.
-
Research
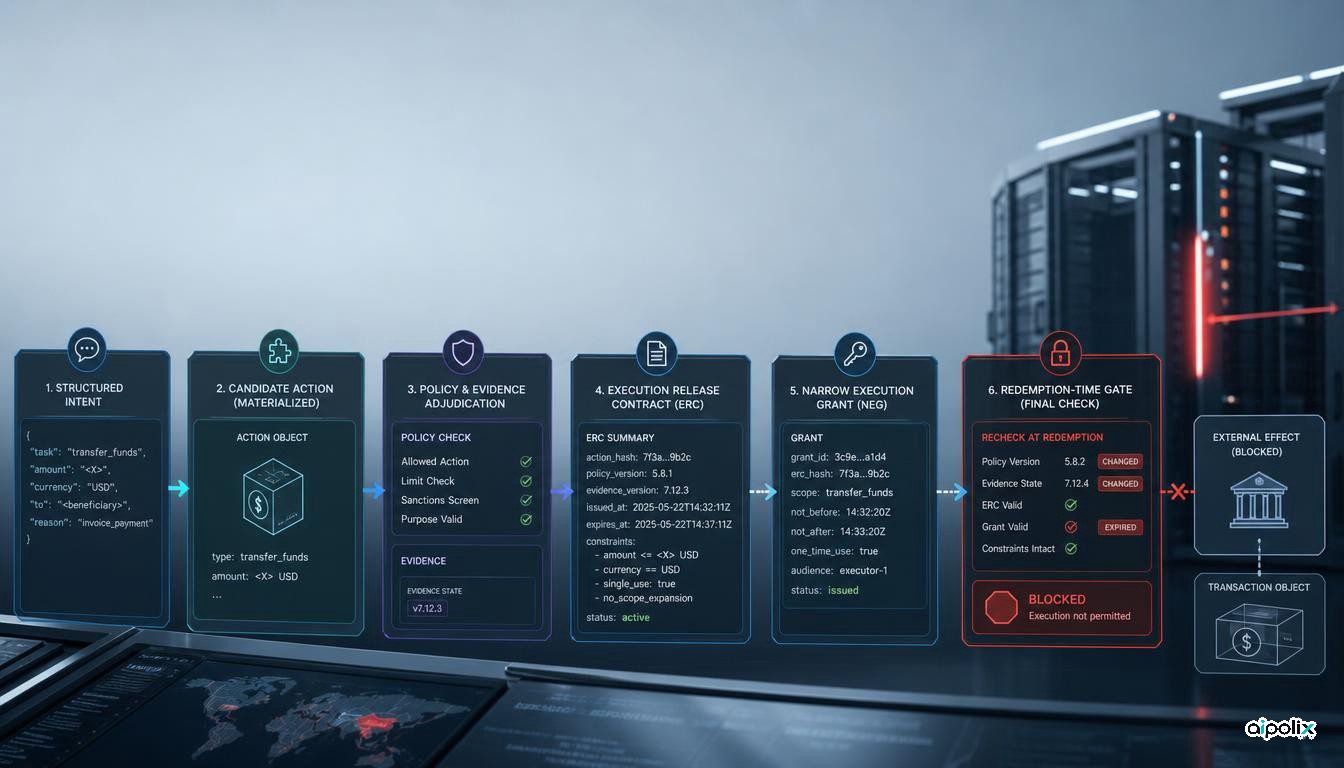
EBL-Core separates an agent’s policy approval from its authority to execute
EBL-Core proposes revalidating action identity, policy, evidence and context when high-risk AI agents exercise execution authority, not only when approval is issued.
-
🛑 AI Governance Fails Without Containment (6/10)
Why agent governance needs runtime containment: stop mechanisms, blast-radius controls, rollback, behavior canaries and recovery evidence.