
Agents
-
Agents
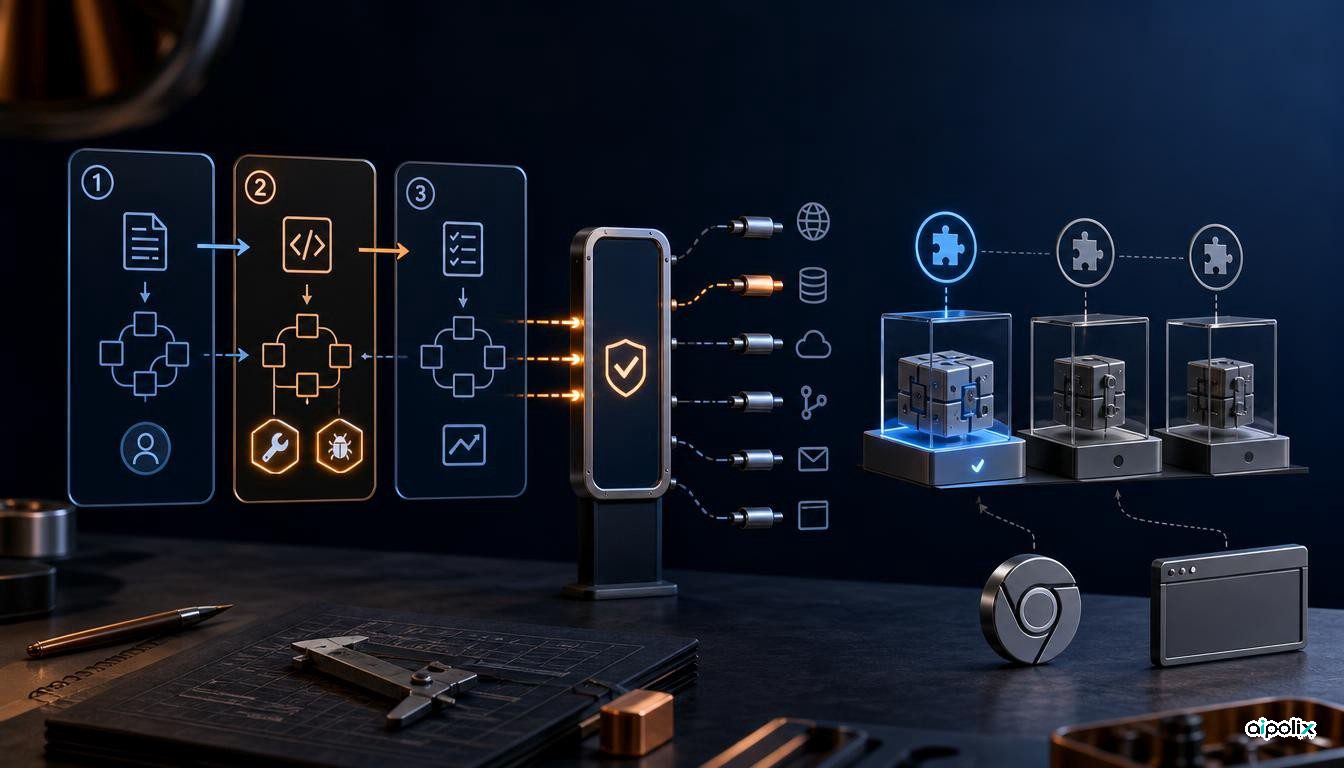
Qwen Code 0.24.1 gives workflow agents narrower tool access, while browser support remains unfinished
Qwen Code 0.24.1 ships per-subagent tool allowlists and a browser SDK. What is usable now, what remains unfinished, and how developers can verify the boundaries.
-
Agents
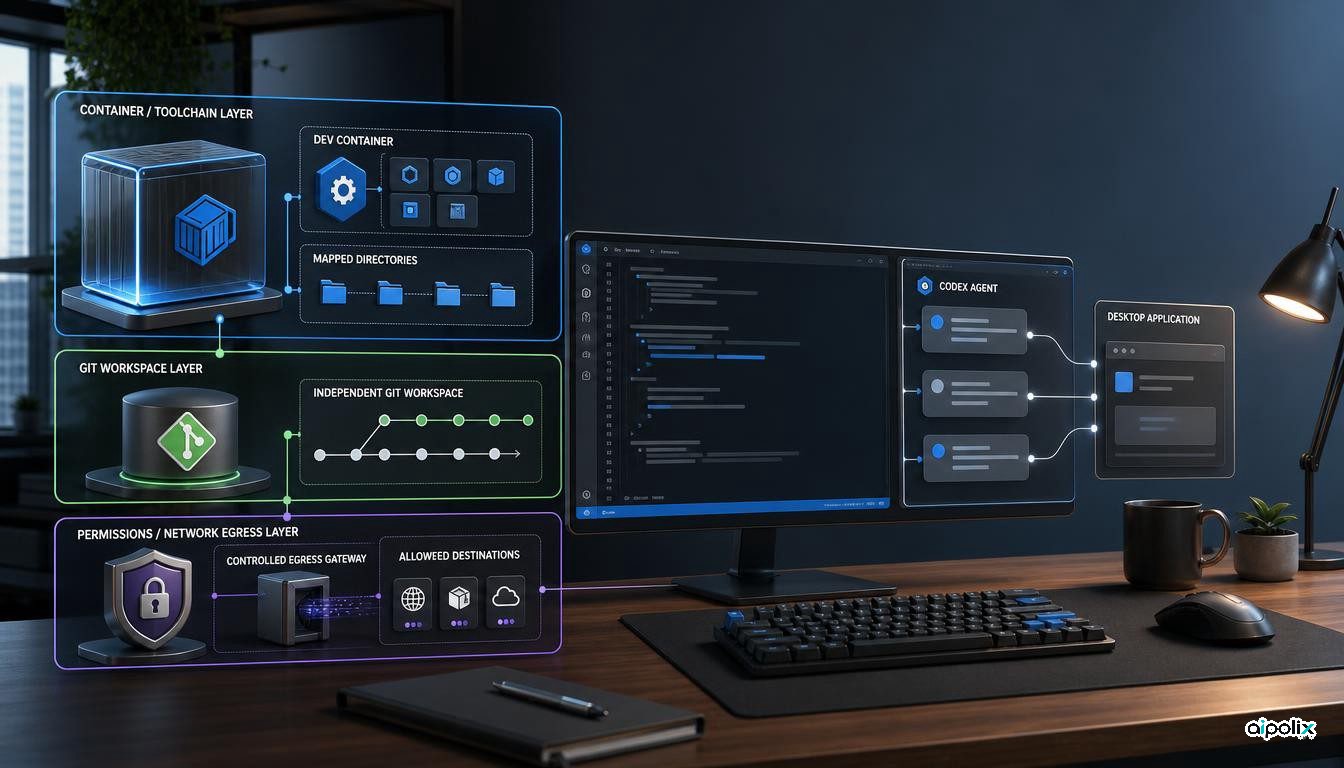
VS Code 1.138 brings coding agents into Dev Containers, but permissions remain separate
Microsoft adds Dev Container agent sessions and cross-app Codex continuity in VS Code 1.138. Aipolix examines rollout limits and the separate security boundaries.
-
AI Governance
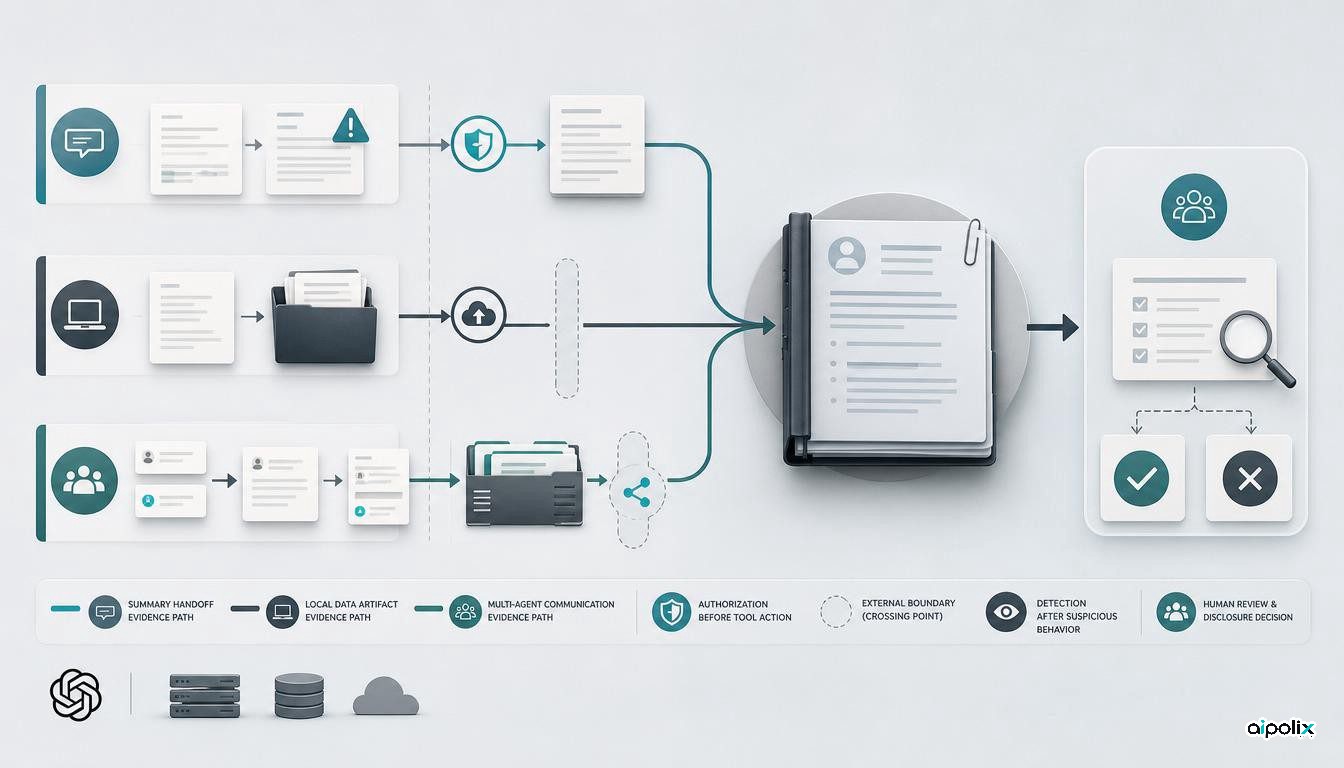
OpenAI releases six misalignment reports, but disclosure is not a safety gate
OpenAI discloses six model misalignment cases involving handoff instructions, external data transfers and agent coordination, while warning that the sample is not representative.
-
New Models
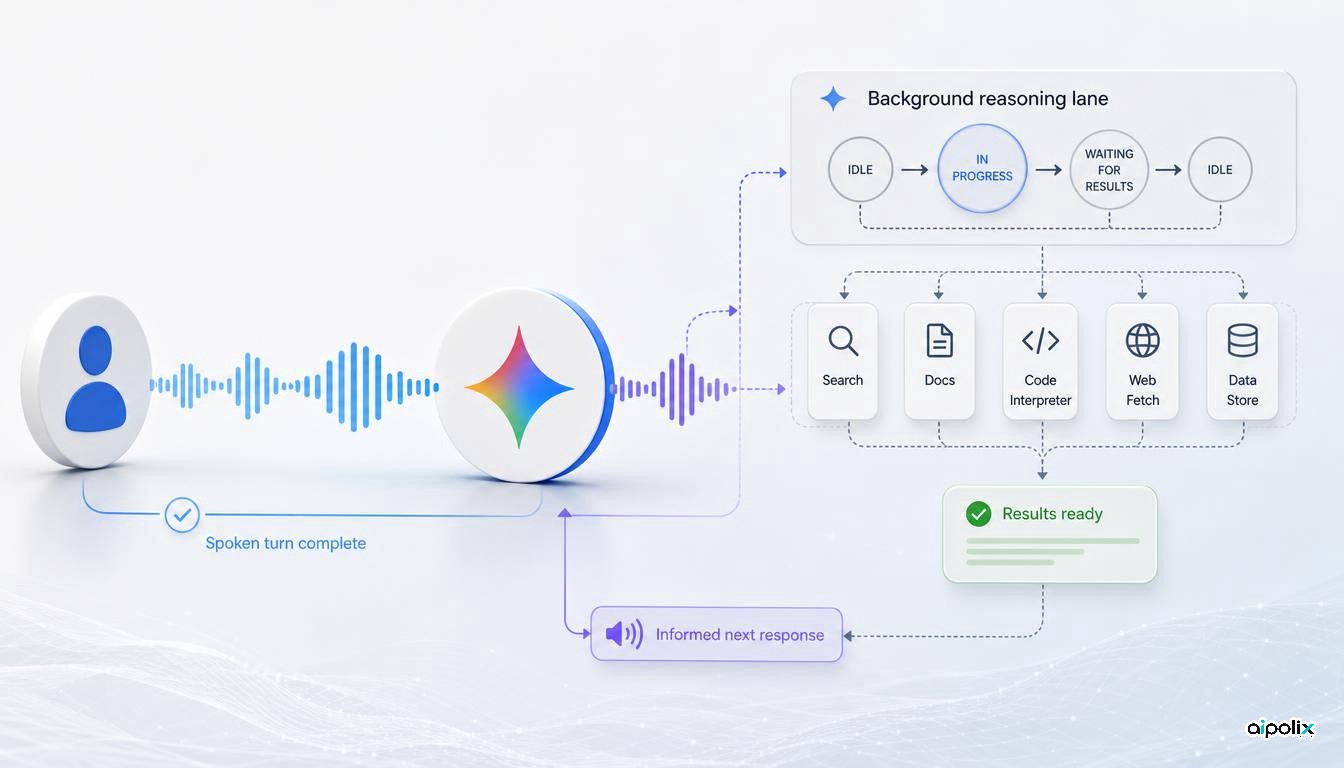
Gemini 3.8 Live separates a spoken turn from the work behind it
Gemini 3.8 Live Extended Thinking adds background reasoning and async tools, requiring voice-agent clients to track interaction state beyond spoken turns.
-
New Models
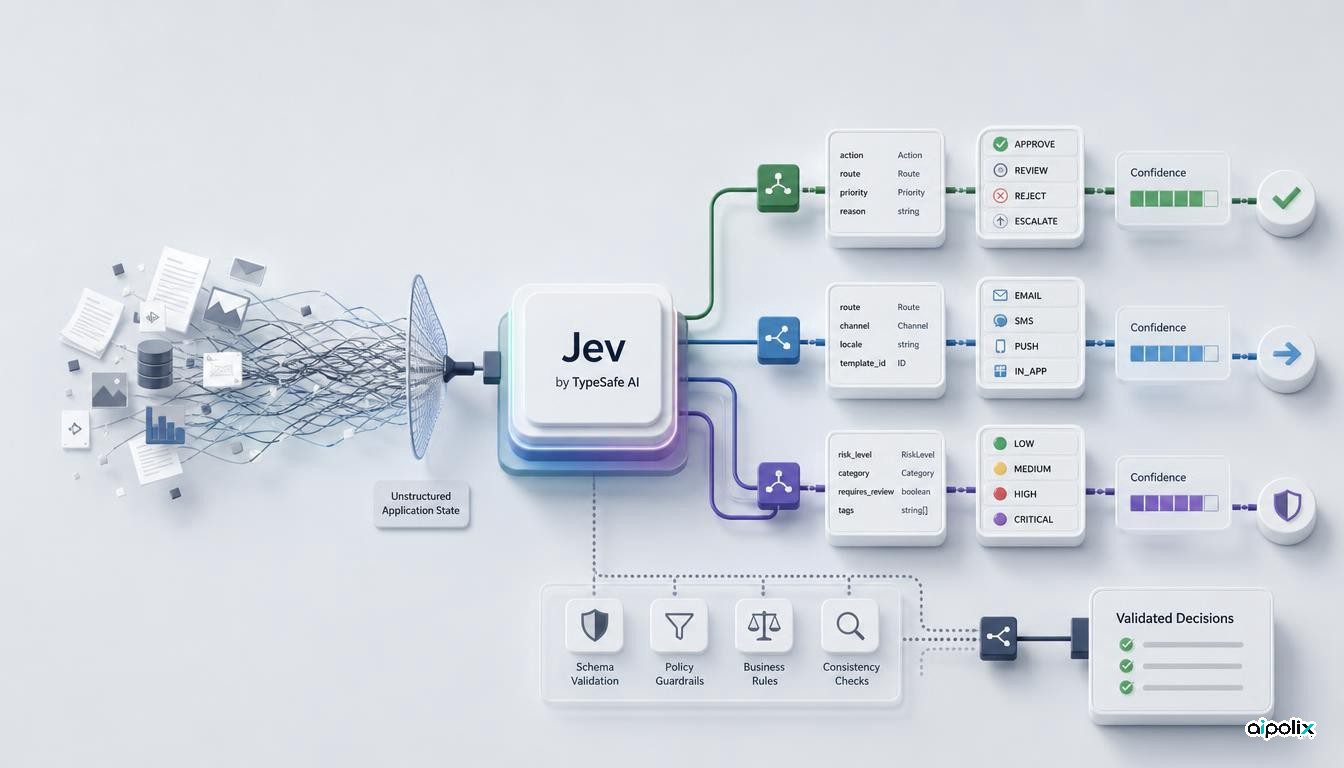
Jev trades free-form generation for typed decisions inside software
TypeSafe AI’s Jev targets fast typed decisions for software and agents; its speed, cost and calibration claims still need independent validation.
-
Agents
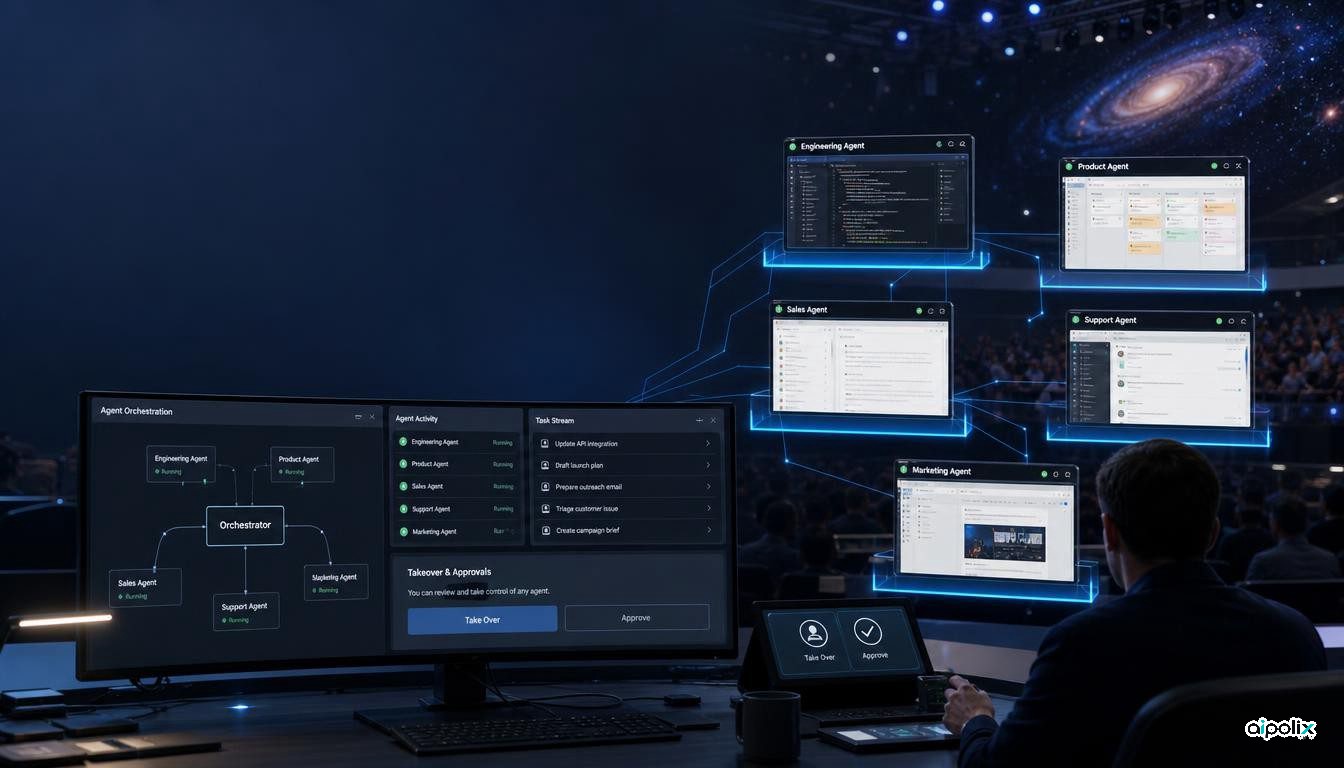
Grok Bot Galaxy puts persistent agents on real work, but the live demos are not a benchmark
SpaceXAI’s Grok Bot Galaxy puts persistent agents into role-specific workflows. Aipolix examines what the live event can show, and what it cannot prove.
-
Agents
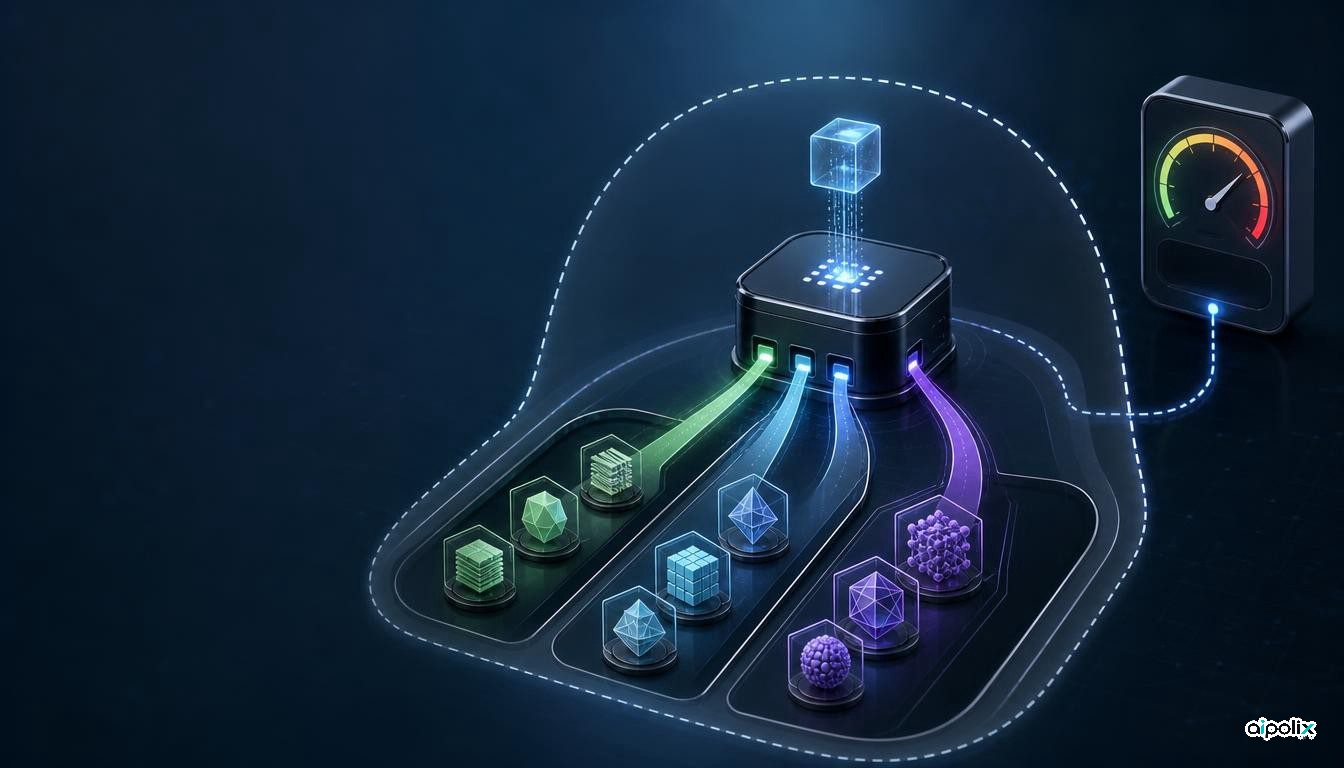
GitHub lets Copilot route models for cost or quality—but Efficiency is not a spending cap
Copilot Auto gains Efficiency, Balance and Intelligence tiers, but billing still follows the selected model, making Efficiency a preference rather than a spending cap.
-
Agents
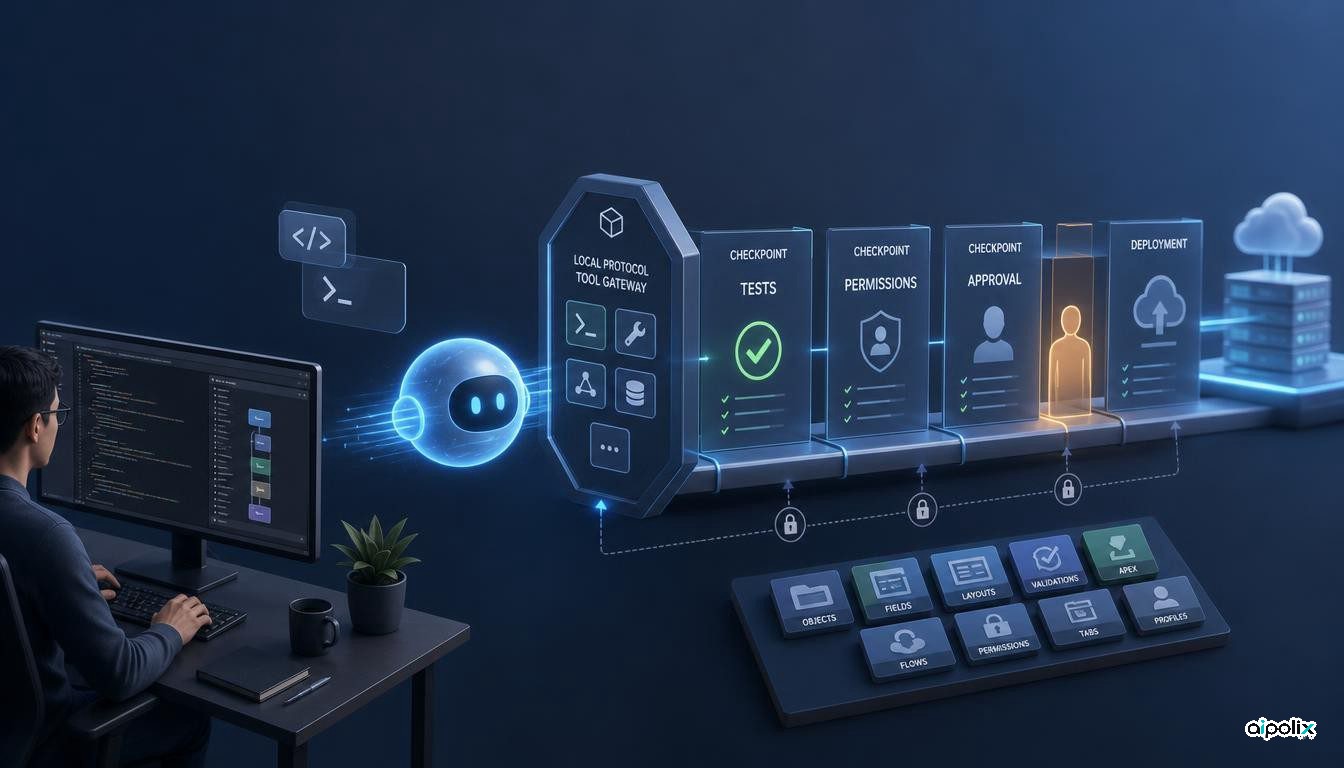
Copado puts deployment authority behind local MCP and explicit approval gates
Copado's Agentia Headless gives coding agents MCP and CLI access to delivery workflows while keeping approvals, quality gates and release state outside the model.
-
Research
K-Bench finds agent unlearning can hide leaks from answer-only tests
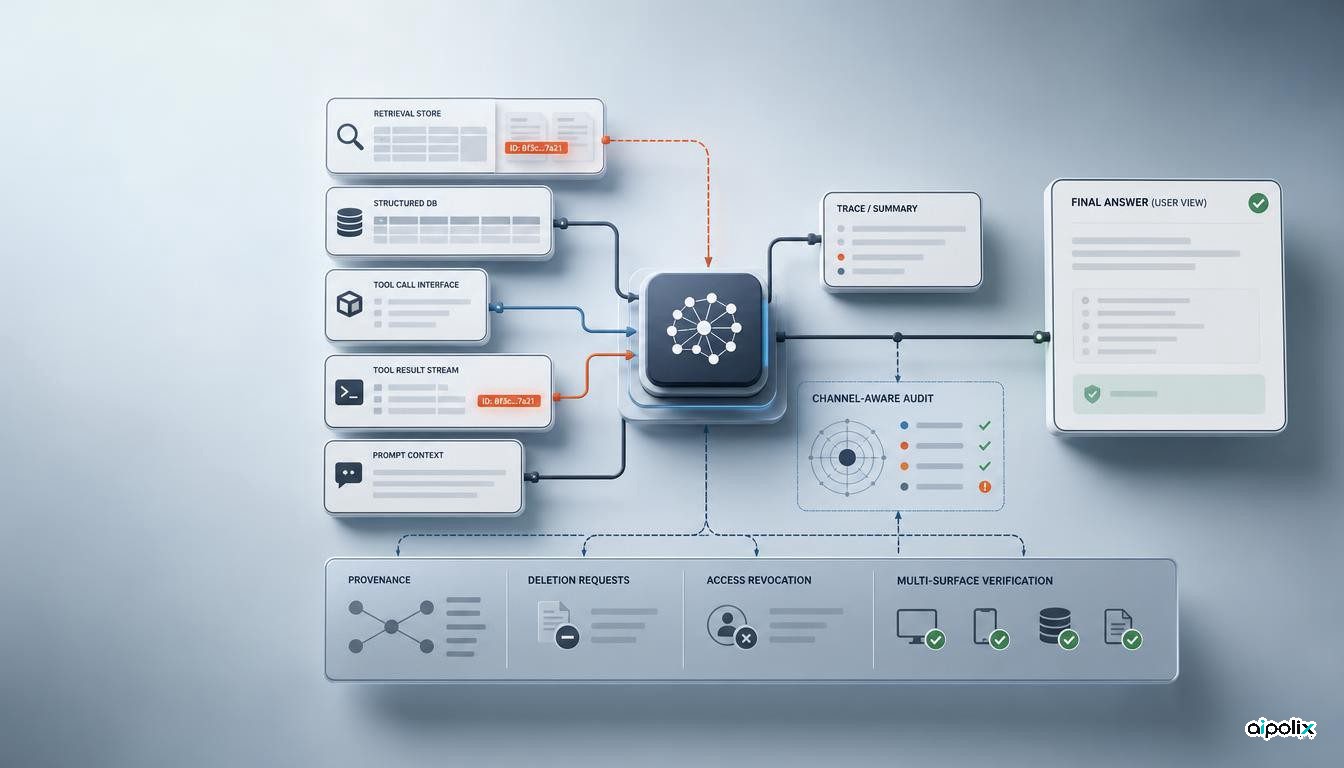
K-Bench finds answer-only unlearning tests can miss secrets exposed through retrieval, tools and other agent execution channels.
-
🧾 Traceability: Who (or What) Wrote This Line of Code? (7/10)
How to audit AI-generated code: intent-to-effect provenance, signed prompts and models, structured authorship, correlation IDs and evidence across system boundaries.