
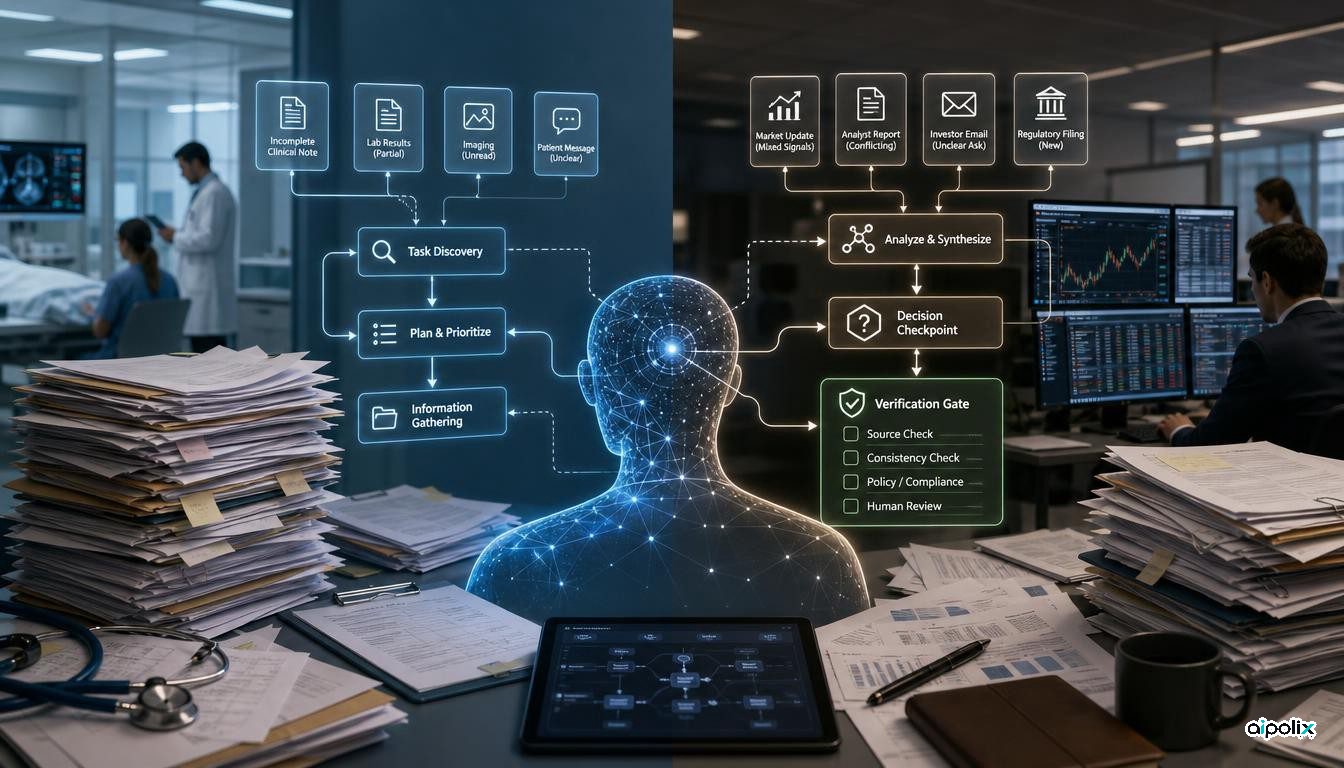
Surge AI has released DAYJOB: Healthcare and DAYJOB: Finance, two benchmarks designed to test a problem that many agent evaluations simplify away: real work often arrives without a complete specification. Instead of giving an agent a clean objective and a detailed list of steps, DAYJOB presents realistic professional requests and asks whether the system can determine what needs to be done, navigate the environment and finish the work.
The headline numbers are a useful warning against treating strong performance on tightly scoped agent benchmarks as proof of workplace readiness. Surge reports that the strongest evaluated model passes 24.7% of DAYJOB: Healthcare tasks and 23.9% of DAYJOB: Finance tasks. Those are benchmark results from the benchmark creator, not independently reproduced production failure rates, but the gap is large enough to make the evaluation design itself worth attention.
The benchmark moves ambiguity into the task
Many agent tests begin after a human has already done an important part of the job: defining the goal precisely. A coding benchmark may identify the issue to fix. A browser benchmark may specify the information to retrieve. A workflow test may enumerate the required inputs. That makes execution easier to measure, but it removes requirements discovery from the evaluation.
DAYJOB deliberately puts some of that ambiguity back. Its healthcare tasks span clinical, operational, payer, pharmacy and compliance workflows. Its finance tasks cover corporate finance, banking, credit, investing and real assets. Surge describes the common requirement as turning messy context into sound professional decisions and finished work.
Aipolix’s interpretation is that this changes what “agent reliability” means. The agent is no longer judged only on whether it can call tools or reason through a known plan. It must infer the plan, identify missing information, distinguish relevant from irrelevant context and decide what a satisfactory deliverable looks like. A system can be competent at every individual tool call and still fail because it solved the wrong problem.
Low pass rates point to an orchestration problem, not one missing skill
Surge groups the capabilities exposed by its environments into tool use, planning, adaptability, groundedness and common sense. That combination matters because long-horizon professional work is rarely defeated by one isolated capability. Failures can compound: a weak initial interpretation leads to the wrong plan, which causes the wrong data to be gathered, which makes later reasoning look coherent while producing an unusable result.
The healthcare leaderboard currently places Claude Opus 5.5 at 24.7%, with GPT-6 Astra at 11.6% and Claude Fable 5.1 at 9.6%. In finance, Claude Opus 5.5 is reported at 23.9%, GPT-6 Astra at 21.5% and Claude Fable 5.1 at 19.8%. These figures should be read as results on DAYJOB’s task set, not universal rankings of the models.
For engineering teams, the more important signal is the absolute level. Even the strongest result leaves most tasks unsuccessful under the benchmark’s grading. That makes human escalation, intermediate verification and explicit acceptance criteria difficult to treat as optional production features.
Requirements discovery should become a release gate
A practical consequence is that organizations may need to test agents before the execution phase. A deployment evaluation should ask whether the agent correctly identifies the requested outcome, hidden constraints, required evidence and conditions under which it should stop and ask for clarification.
This suggests a layered test design. First measure task interpretation: can the agent restate the objective and identify missing information? Then measure planning and tool selection. Finally evaluate the finished artifact against professional criteria. If those stages are collapsed into one pass/fail score, teams may know that an agent failed without learning whether the failure came from misunderstanding, execution or judgment.
The same structure can support safer production systems. Before an agent performs a consequential action, a separate checkpoint can compare its inferred task against the user’s authority and the available evidence. In regulated workflows, that checkpoint may be more valuable than adding another reasoning pass after the agent has already committed to the wrong interpretation.
What DAYJOB does not prove
DAYJOB covers selected healthcare and finance workflows. It does not establish a single failure rate for all knowledge work, and its leaderboard should not be converted into claims about how often a model would fail inside a specific company. Real deployments have different tools, data quality, permissions, training, review processes and task distributions.
The benchmark also cannot by itself tell organizations whether a lower-scoring model with stronger controls is worse for their environment than a higher-scoring model with broader authority. Production reliability depends on the model, harness, data, permissions and verification system together.
The useful contribution is therefore methodological. DAYJOB makes task discovery part of the thing being measured. As agents move from assistants that answer well-formed requests toward systems expected to own outcomes, that missing layer becomes increasingly important. The question is no longer only whether an agent can execute a plan. It is whether the agent can determine the right plan before execution begins.