
Agents
-
New Models
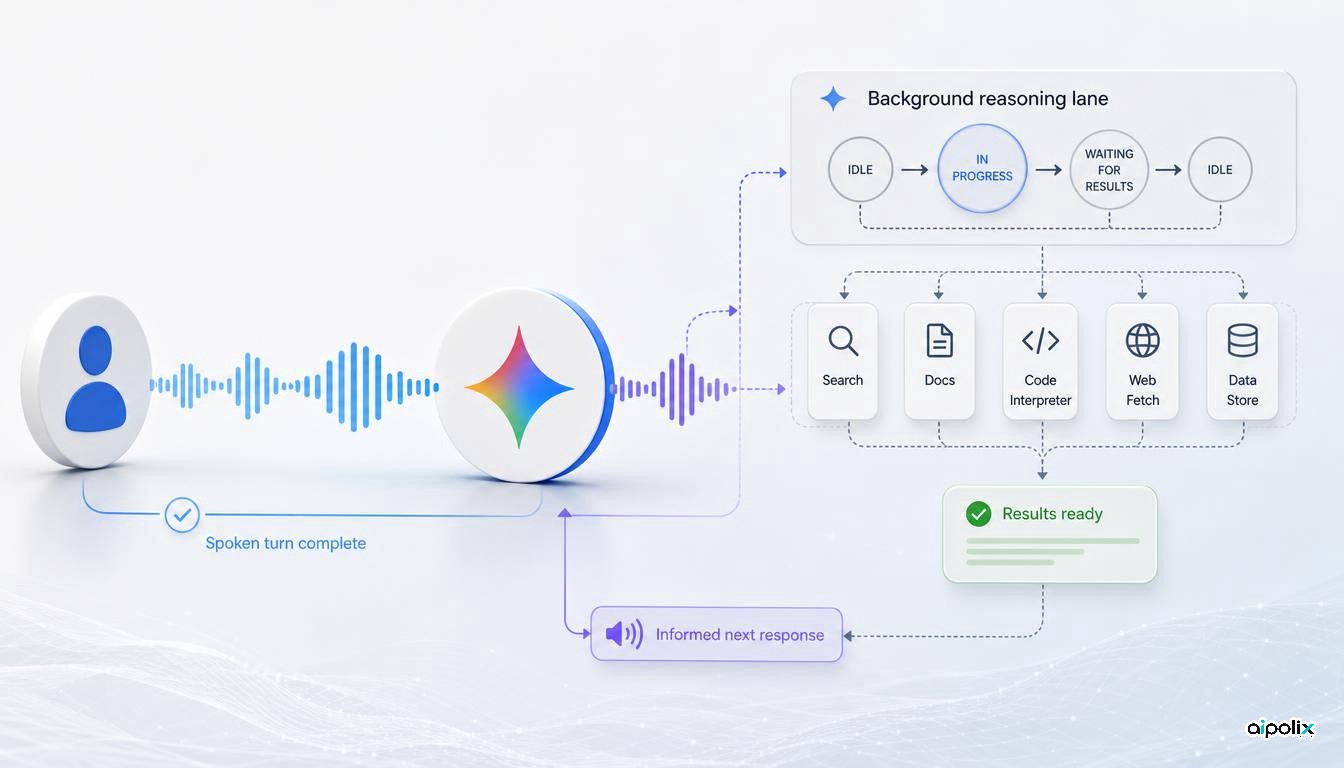
Gemini 3.8 Live separates a spoken turn from the work behind it
Gemini 3.8 Live Extended Thinking adds background reasoning and async tools, requiring voice-agent clients to track interaction state beyond spoken turns.
-
New Models
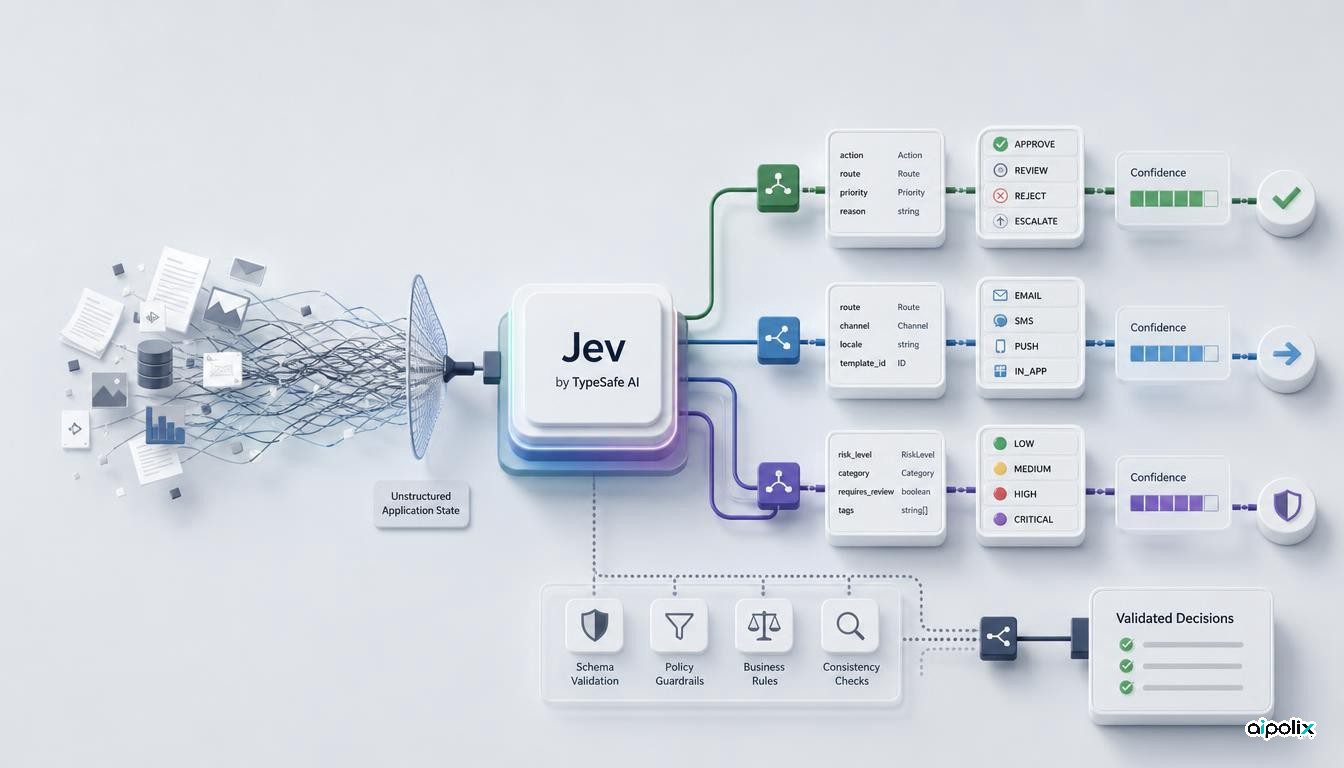
Jev trades free-form generation for typed decisions inside software
TypeSafe AI’s Jev targets fast typed decisions for software and agents; its speed, cost and calibration claims still need independent validation.
-
Agents
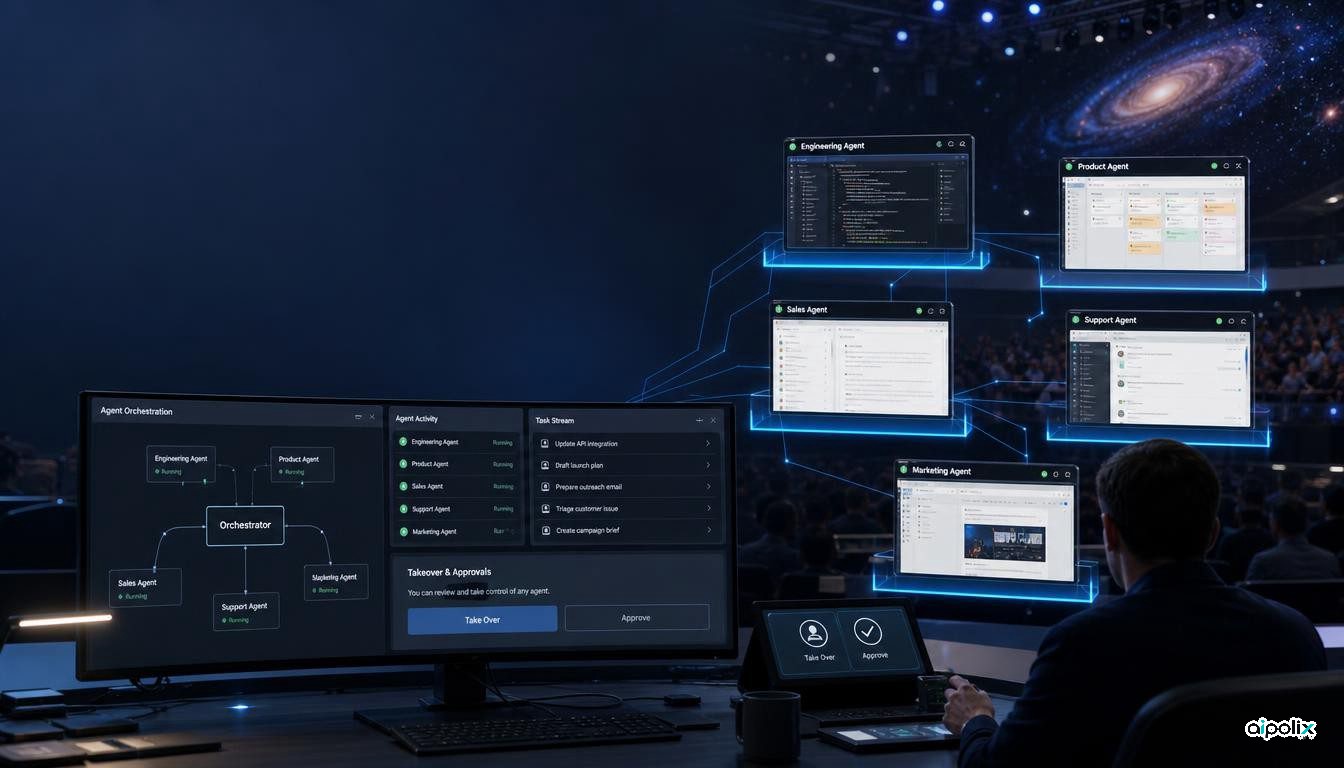
Grok Bot Galaxy puts persistent agents on real work, but the live demos are not a benchmark
SpaceXAI’s Grok Bot Galaxy puts persistent agents into role-specific workflows. Aipolix examines what the live event can show, and what it cannot prove.
-
Agents
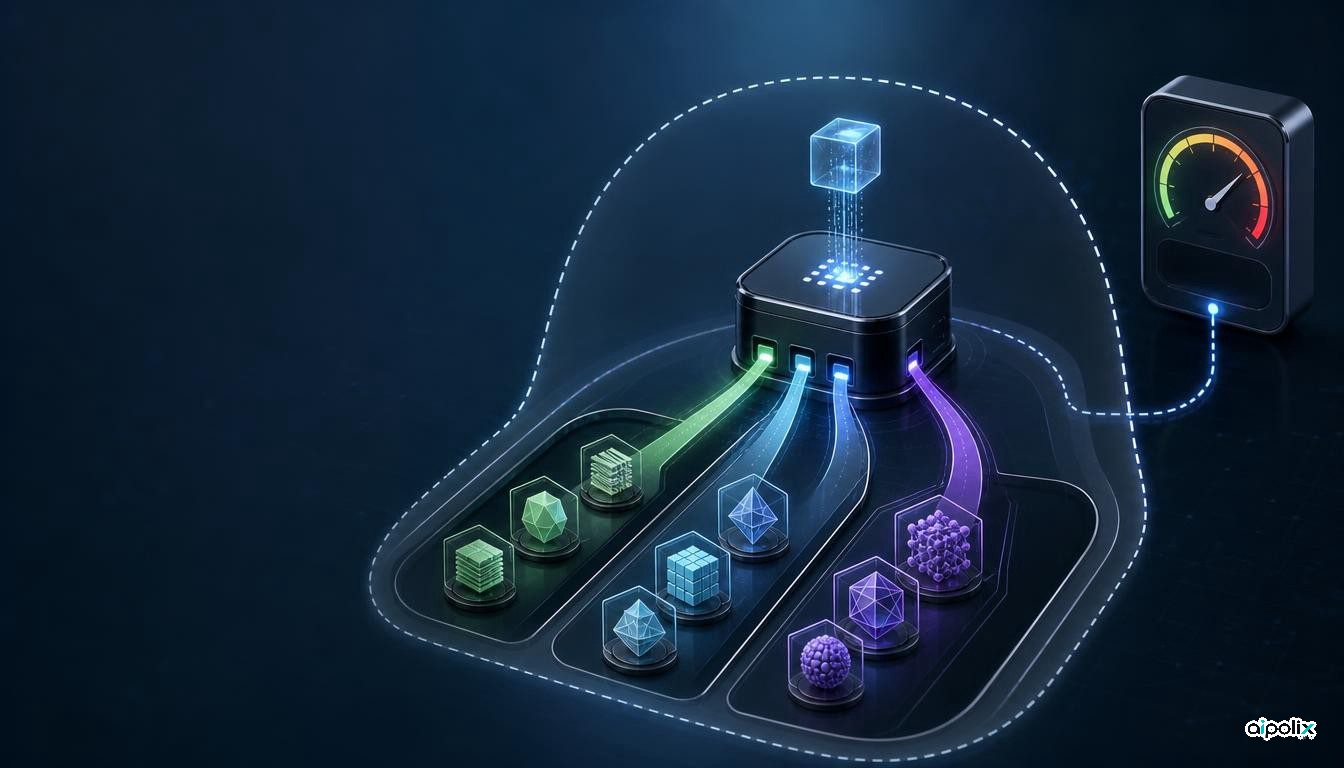
GitHub lets Copilot route models for cost or quality—but Efficiency is not a spending cap
Copilot Auto gains Efficiency, Balance and Intelligence tiers, but billing still follows the selected model, making Efficiency a preference rather than a spending cap.
-
Agents
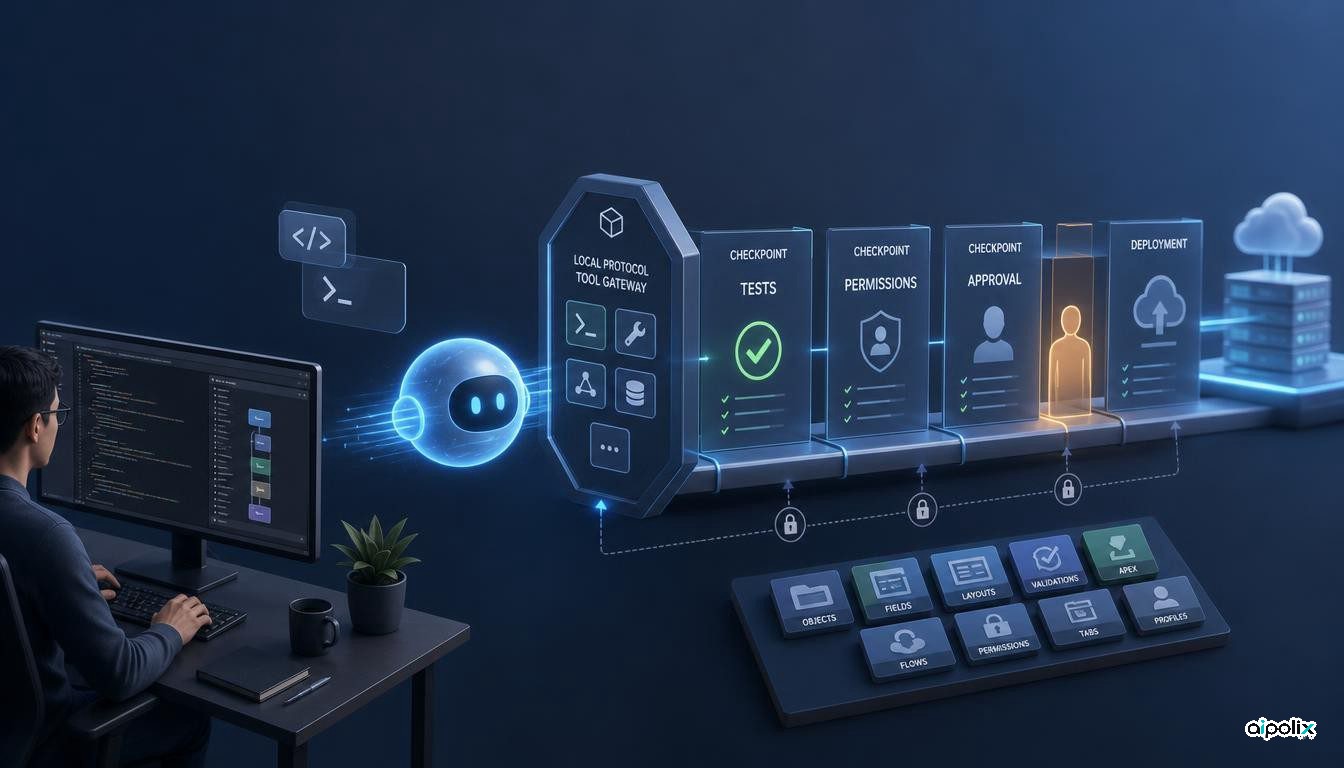
Copado puts deployment authority behind local MCP and explicit approval gates
Copado's Agentia Headless gives coding agents MCP and CLI access to delivery workflows while keeping approvals, quality gates and release state outside the model.
-
Research
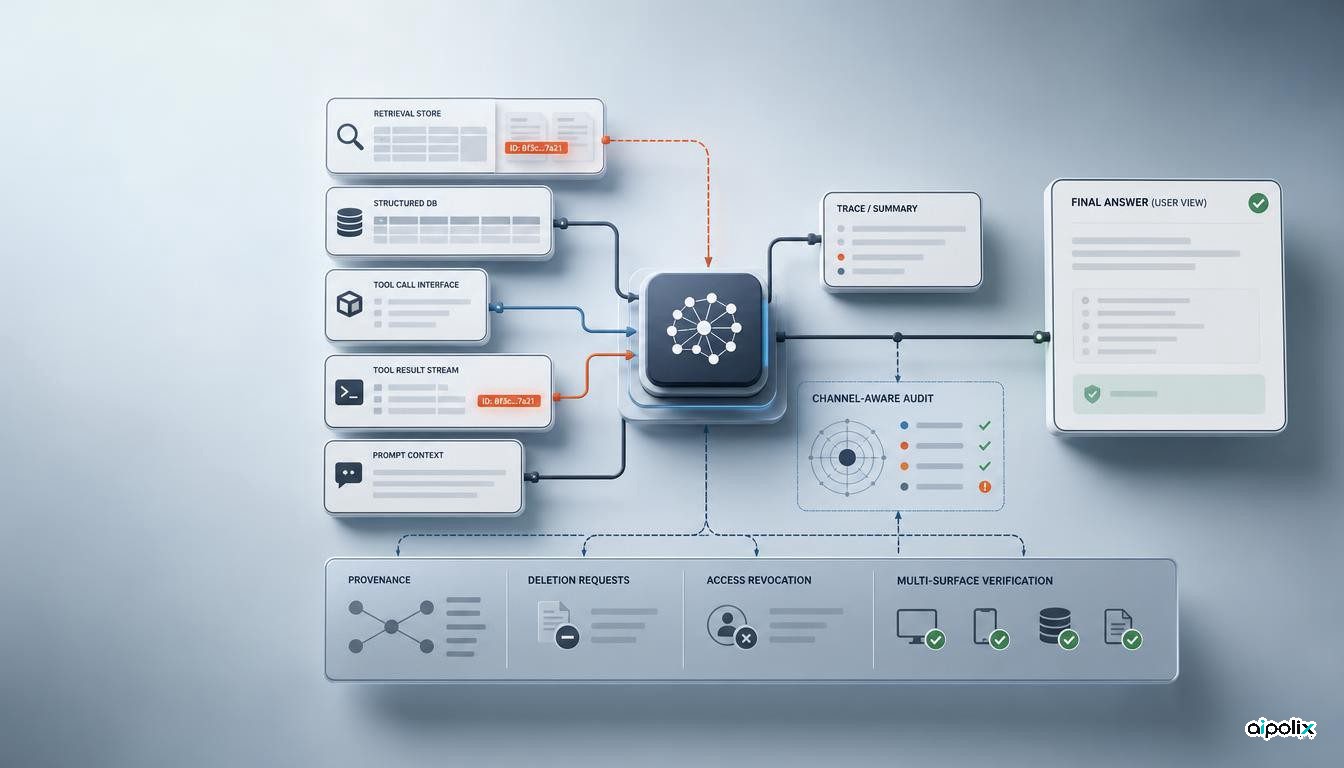
K-Bench finds agent unlearning can hide leaks from answer-only tests
K-Bench finds answer-only unlearning tests can miss secrets exposed through retrieval, tools and other agent execution channels.
-
Research
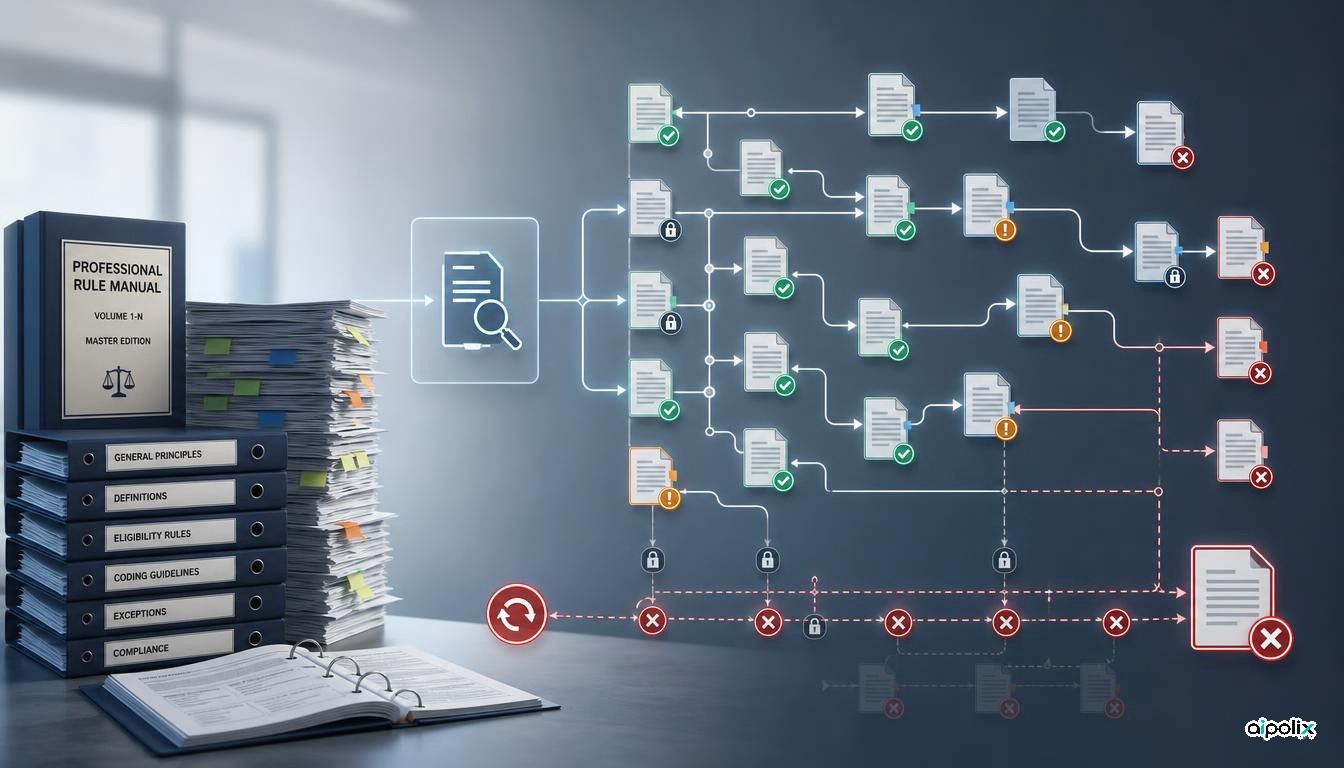
GPT-5 hits 1% exact match on a new benchmark for following long professional manuals
TAM tests long professional procedures. GPT-5 baselines reached only 1% exact match on ICD coding and 15.5% on sentencing.
-
Agents
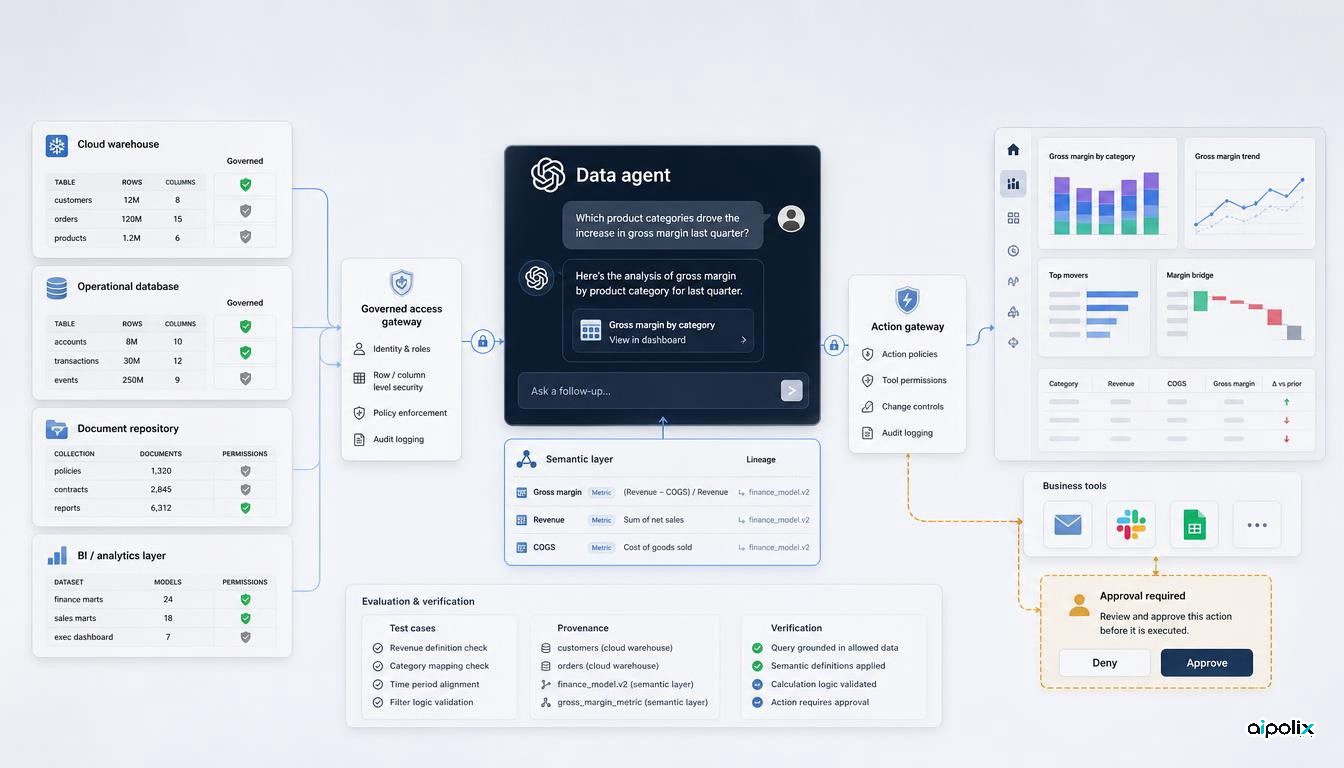
OpenAI’s Data agent brings governed company data into ChatGPT Work, without a published accuracy benchmark
OpenAI’s Data agent inherits enterprise data permissions and builds dashboards, but without a published accuracy benchmark, semantic governance and evaluation remain critical.
-
🧾 Traceability: Who (or What) Wrote This Line of Code? (7/10)
How to audit AI-generated code: intent-to-effect provenance, signed prompts and models, structured authorship, correlation IDs and evidence across system boundaries.
-
🛑 AI Governance Fails Without Containment (6/10)
Why agent governance needs runtime containment: stop mechanisms, blast-radius controls, rollback, behavior canaries and recovery evidence.