For Developers
-
Research
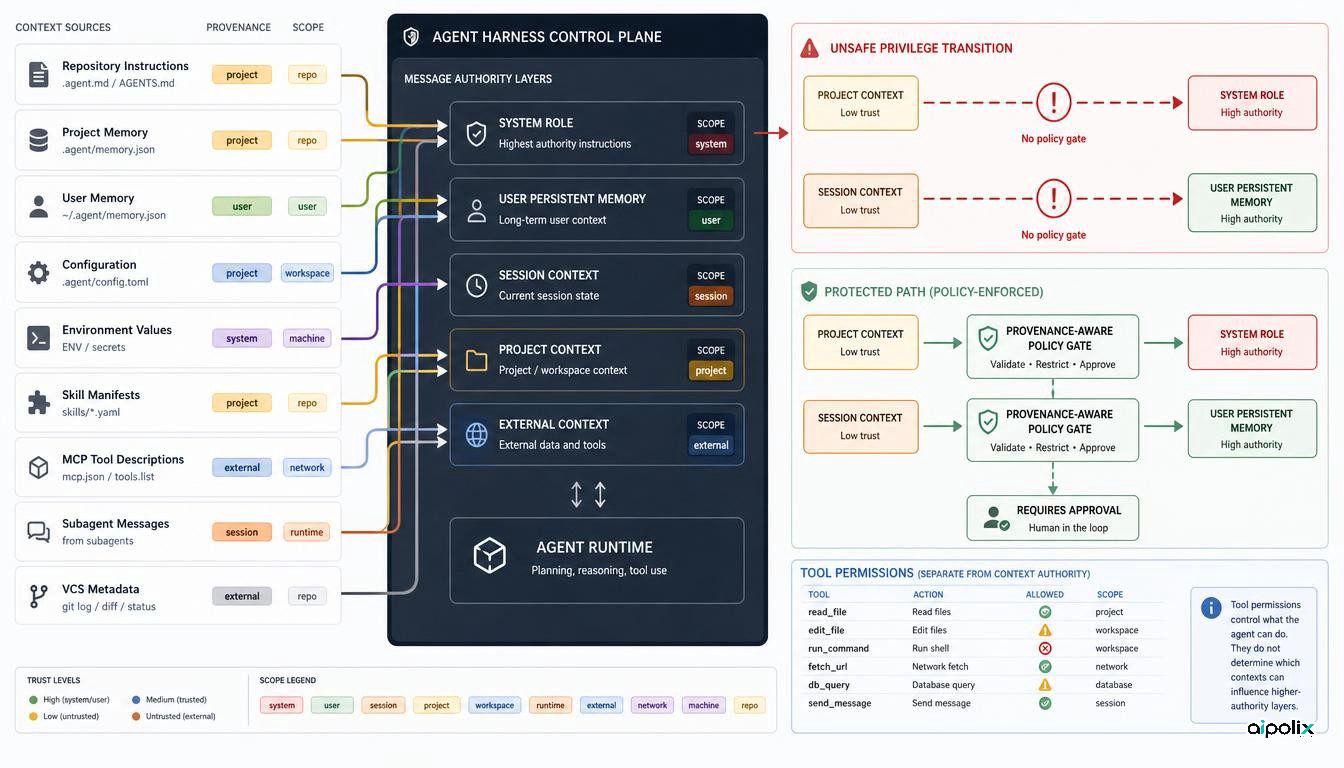
Context privilege escalation turns agent memory into a security boundary
A study across 12 agent harnesses shows how context can gain authority across roles and scopes, making provenance-aware non-escalation controls a runtime requirement.
-
Research
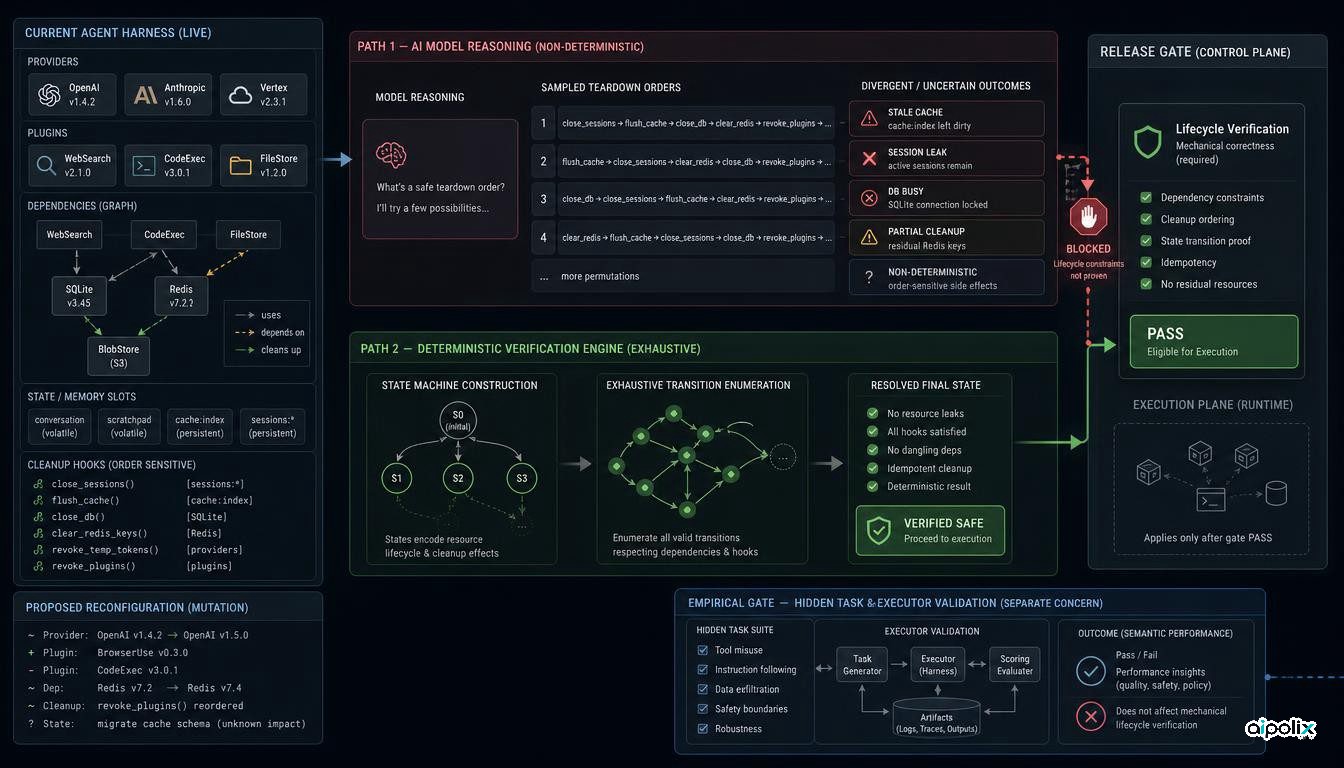
CordisBench shows where agent harnesses should replace reasoning with verification
CordisBench finds that models struggle with growing harness lifecycle interactions even when software can compute the tested state consequences exactly.
-
Agents
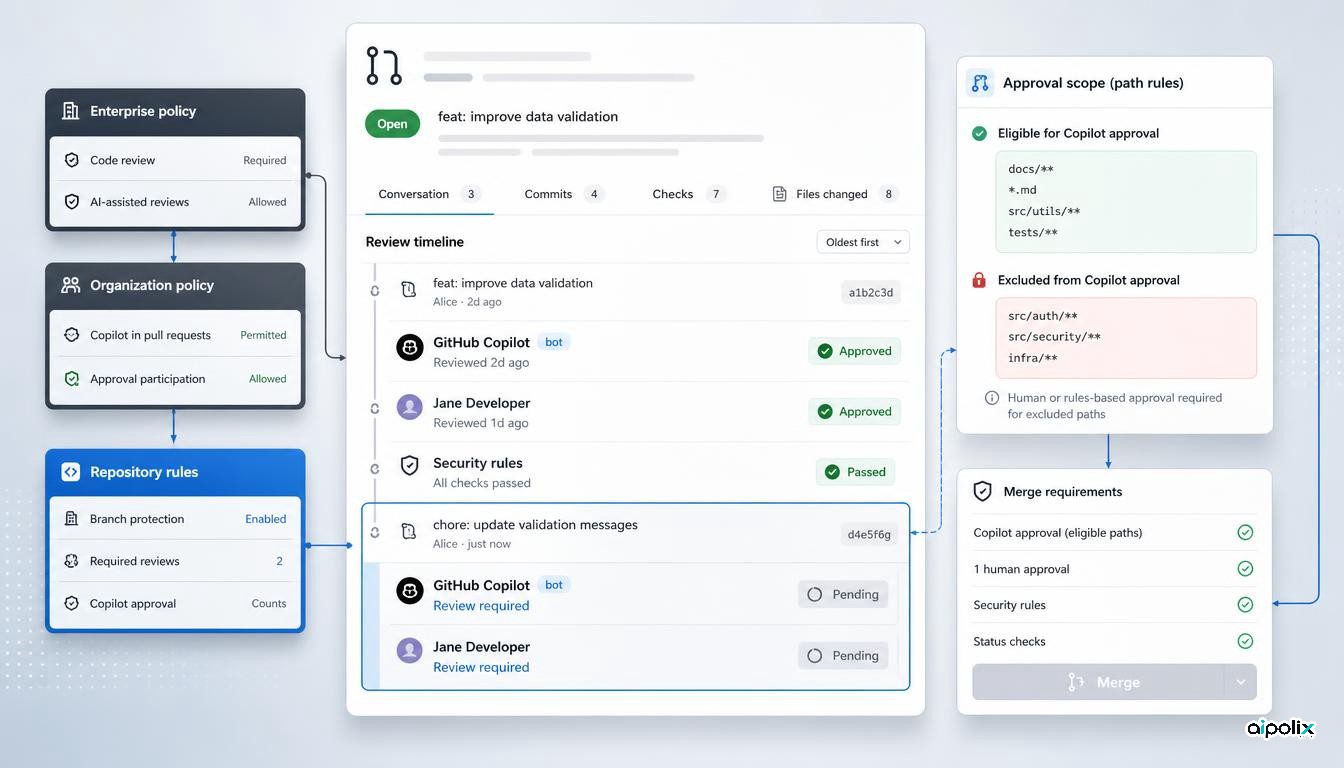
GitHub lets Copilot approvals count toward merge requirements
Copilot code review can now count as a required pull-request approval, with enterprise, repository and path controls around where AI approval applies.
-
Agents
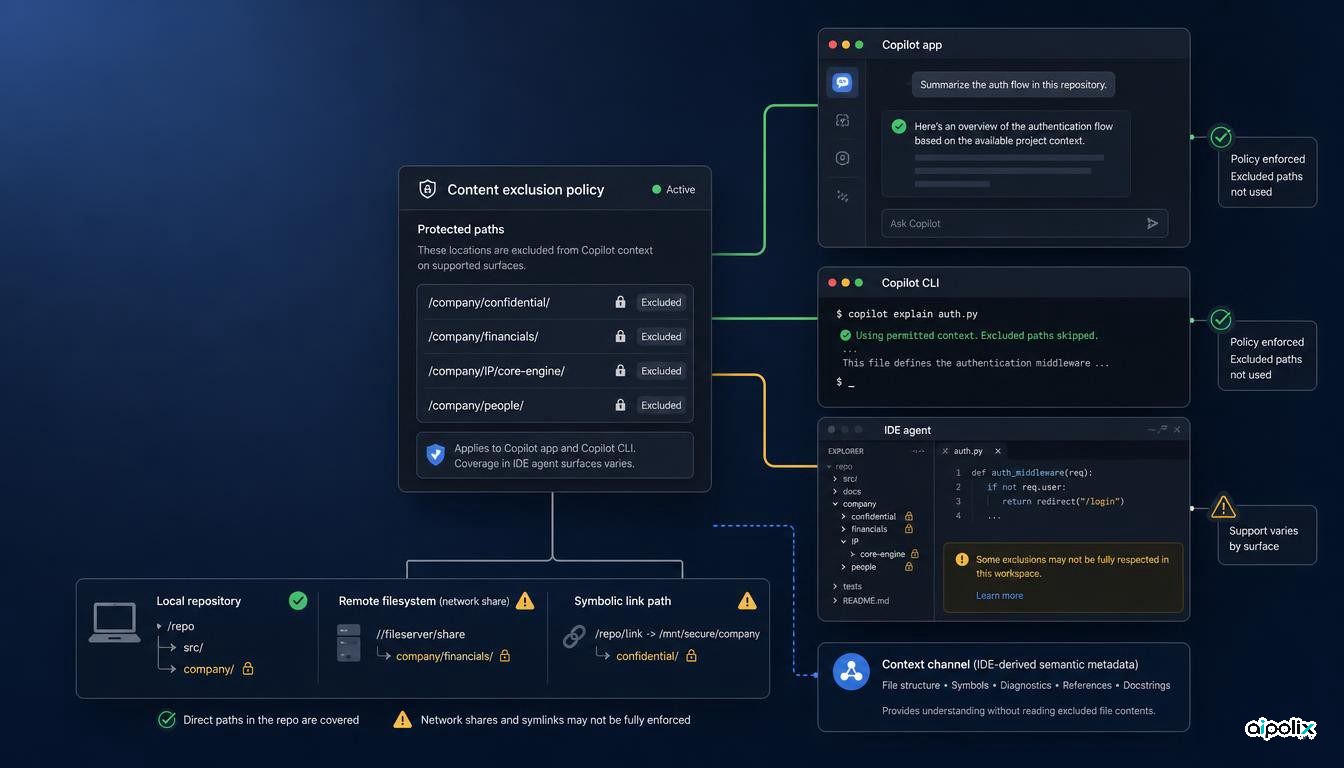
GitHub extends Copilot content exclusions to app and CLI, but gaps remain
Copilot app and CLI now respect content exclusions, while GitHub still documents gaps in IDE agent modes, symlinks and remote filesystems.
-
Research
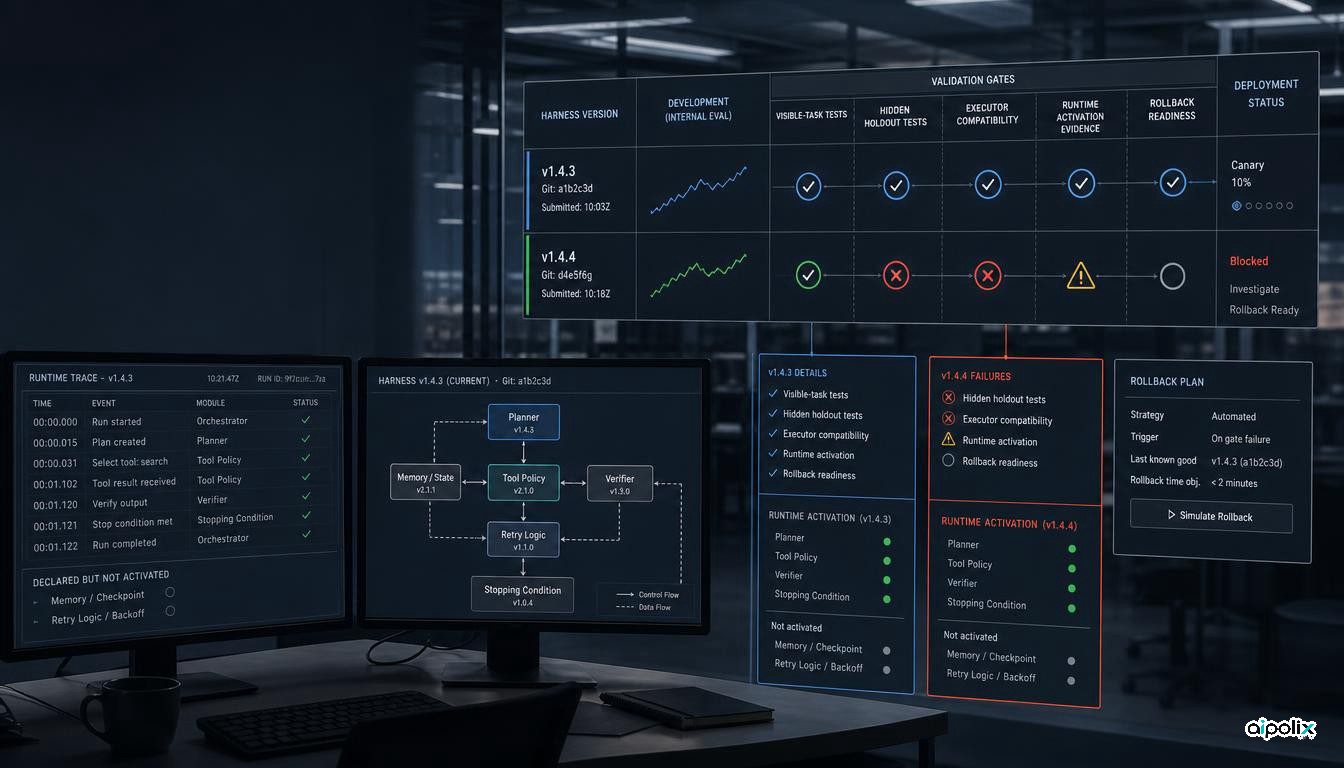
HarnessDev shows why self-improving agents need release gates
HarnessDev shows why evolving AI agent harnesses need hidden-task validation, executor checks, runtime evidence and rollback before promotion.
-
Open Source
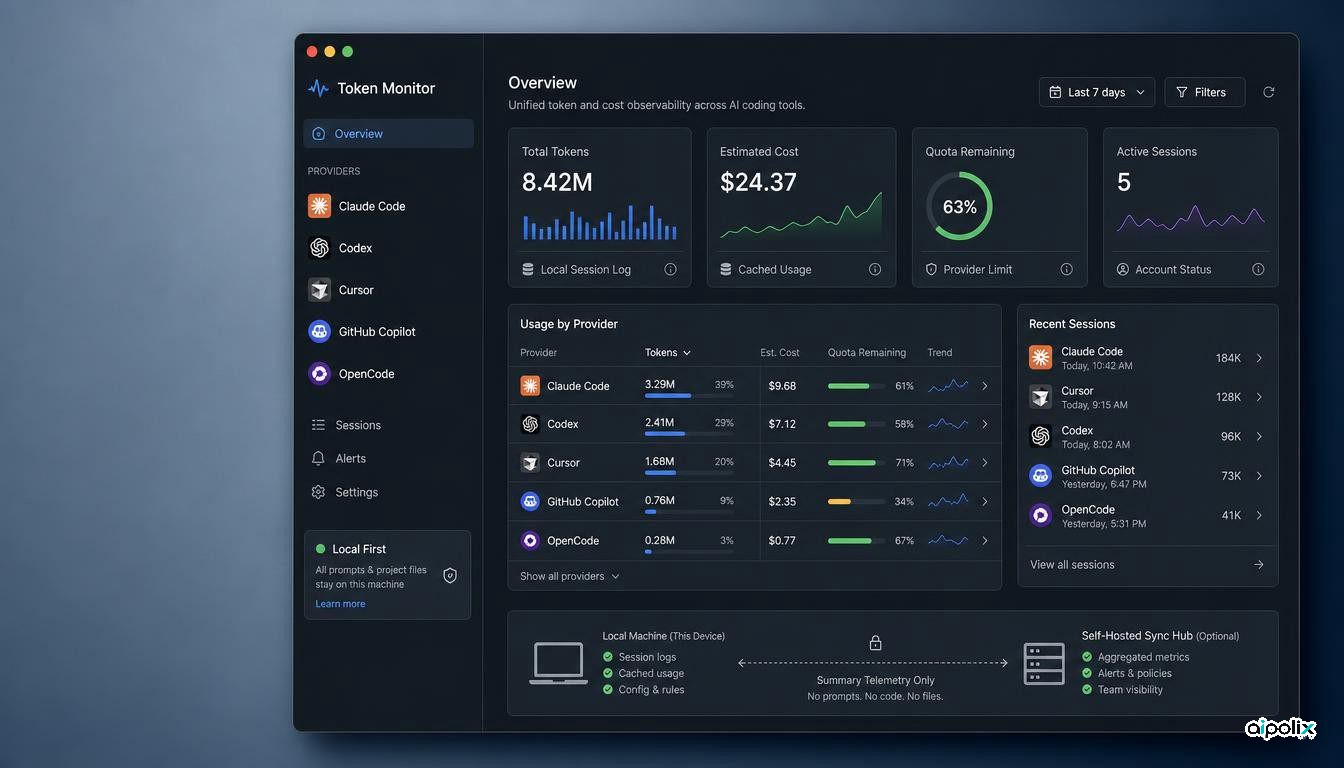
Token Monitor turns fragmented AI coding usage into one observability layer
Token Monitor unifies AI coding usage, cost and quota signals across tools, but its heterogeneous telemetry should not be treated as a billing source of truth.
-
Research
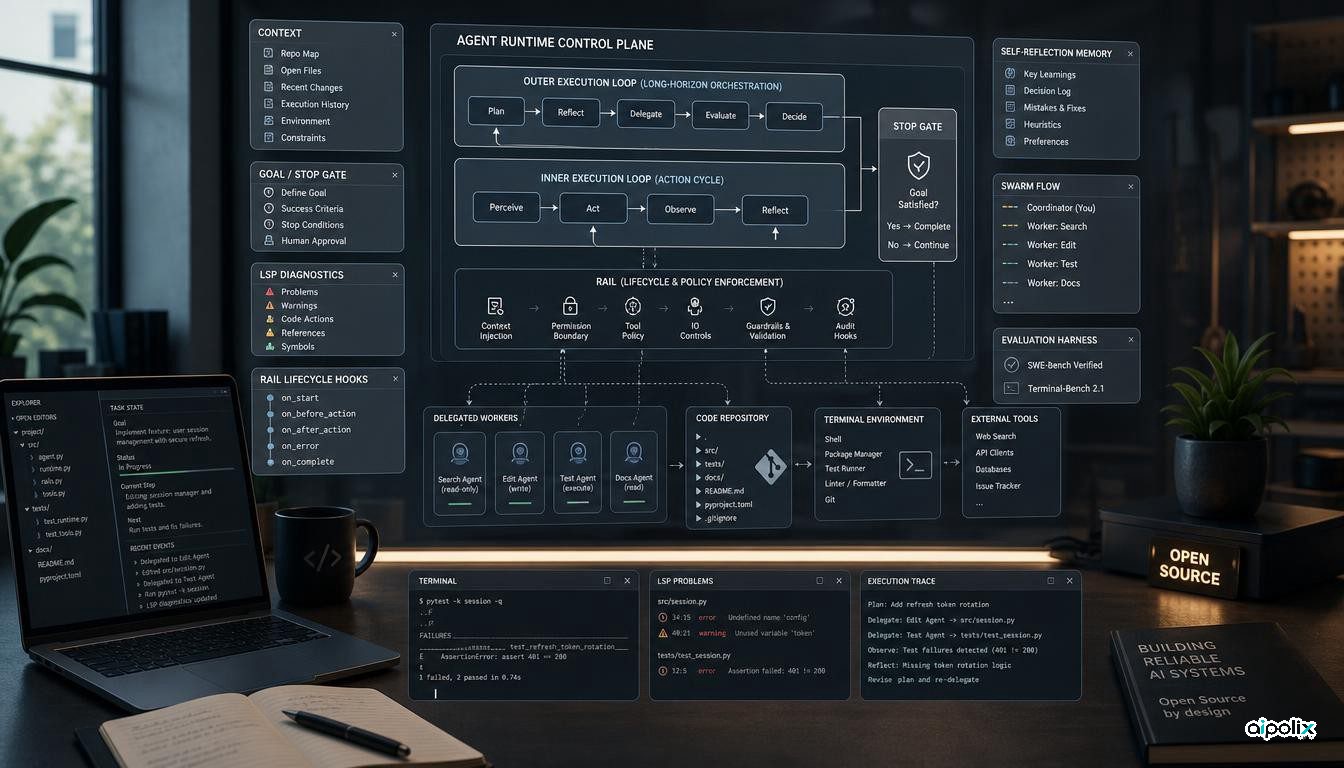
openJiuwen turns the coding-agent harness into a measurable systems layer
openJiuwen proposes a composable, runtime-adaptive coding-agent harness and shows why model-matched benchmark audits matter for agent engineering.
-
Agents
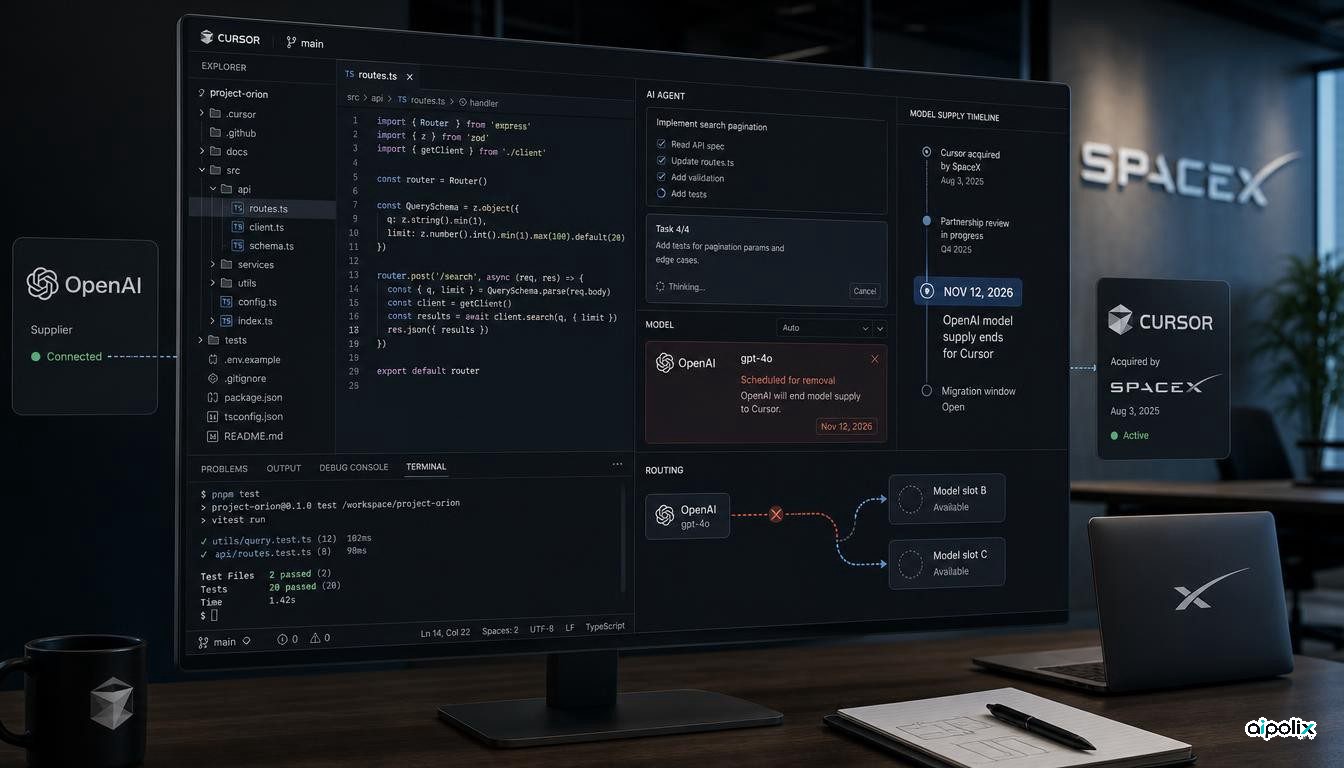
OpenAI sets a November cutoff for its models inside Cursor
OpenAI plans to end model supply to Cursor after SpaceX's acquisition, creating a November 12 migration deadline for developer workflows.
-
Agents
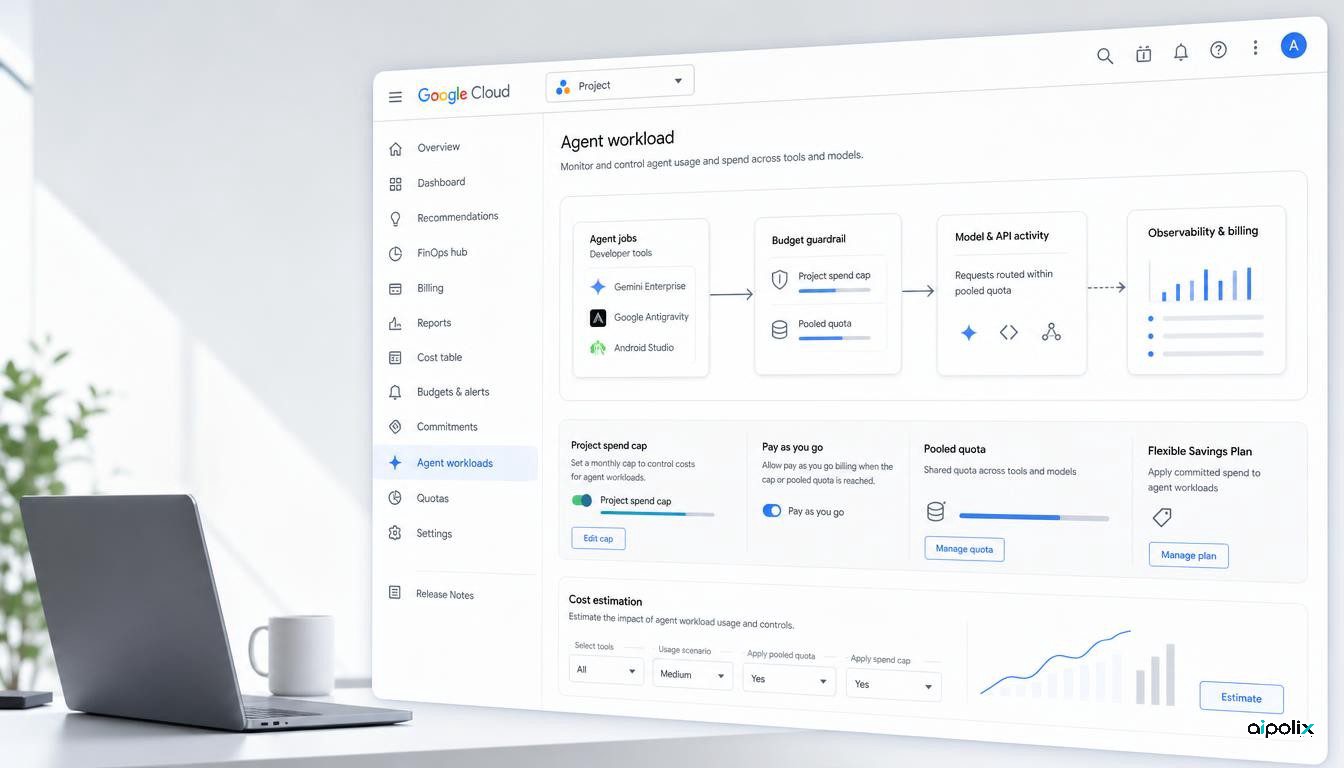
Google turns agent spending limits into runtime controls
Google Cloud adds pooled quotas, pay-as-you-go billing and project spend caps for Gemini Enterprise, Antigravity and other agent workloads.
-
Open Source
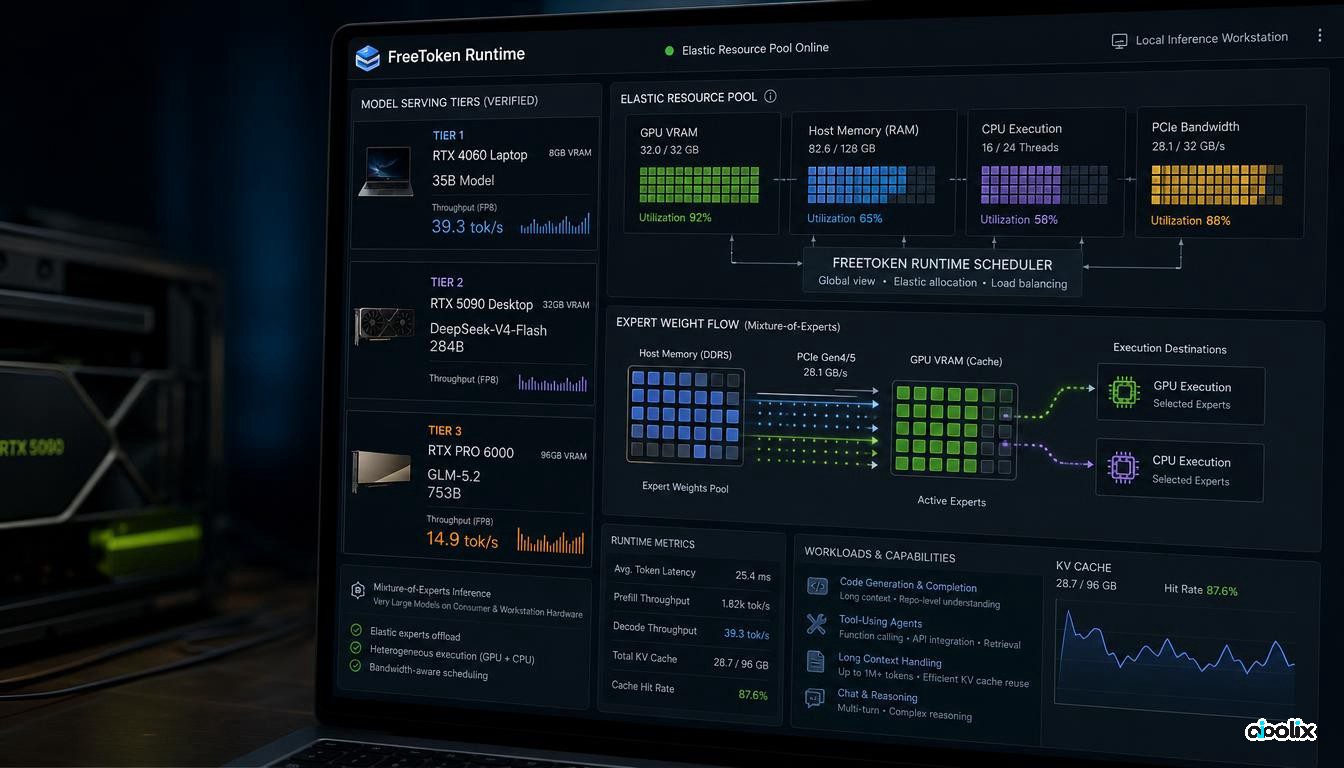
FreeToken runs frontier-scale MoE models on consumer GPUs
FreeToken uses bandwidth-adaptive CPU-GPU execution and semantic caching to serve 35B to 753B MoE models on consumer and workstation hardware.