
A new expert audit of six widely used physics benchmarks argues that a meaningful share of the errors attributed to frontier language models are actually defects in the evaluation system. After physicists reviewed questions, reference answers and grader decisions, the measured scores of several leading models rose sharply.
The result is not evidence that frontier models have “solved physics.” The study covers closed-ended, text-only problems with verifiable final answers, and its corrected scores are often calculated on repaired or reduced subsets. What it does show is more operationally important for anyone using benchmarks to select or govern models: when model capability approaches the quality ceiling of the test, benchmark maintenance becomes part of the evaluation itself.
The audit changed the measured capability
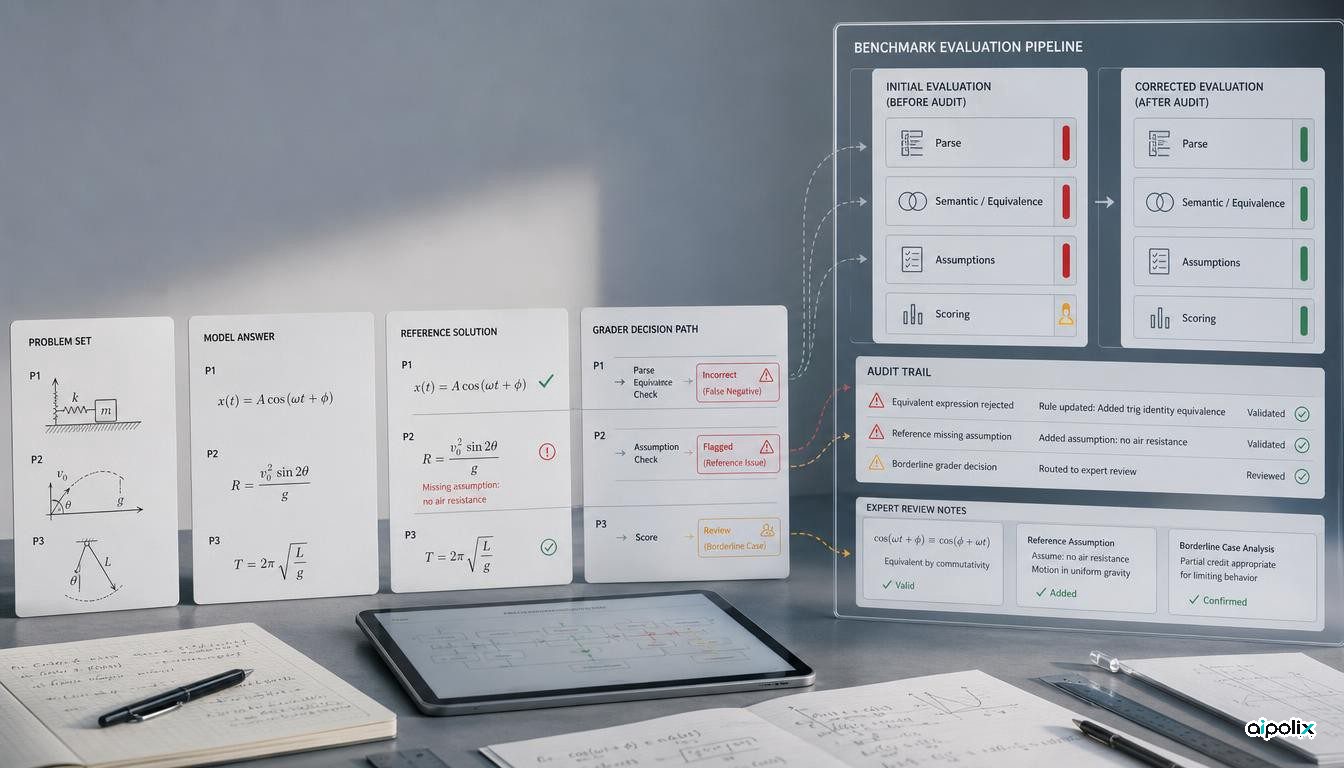
The paper, posted as arXiv:2609.13009, evaluates GPT-5.6-Sol, Claude Fable 5 and Gemini 3.1 Pro across six physics benchmarks. Expert reviewers, primarily physicists affiliated with Yale University, classified apparent failures as genuine model errors, grader errors or benchmark errors such as incorrect reference solutions, missing assumptions and ambiguous questions.
The changes were large. On HLE-Physics, GPT-5.6-Sol High rose from 47.28% to 78.66% mean@4 after validation and repair. On CMT-Benchmark, it rose from 61.00% to 87.24%. For CritPt, Artificial Analysis reports GPT-5.6 Sol Max at 32.3% on the original benchmark; the paper reports 87.50% mean@4 and 94.44% pass@4 on the 54 retained challenges after expert review.
The most dramatic result appears in the three benchmarks drawn from public problem sources. Across their pooled audit sets, the authors attribute 148 of 152 inspected apparent failures, or 97.37%, to benchmark or grader problems rather than model errors.
Those numbers need careful interpretation. Corrected scores are not always computed on exactly the same question set as the original scores, and CritPt's pre-audit result uses mean@5 while the corrected result uses mean@4 on a smaller retained set. The paper is therefore strongest as an audit of evaluation reliability, not as a clean before-and-after model leaderboard.
Better models make bad graders more visible
The paper identifies a structural problem that becomes worse as models improve. A brittle evaluator can reject a correct answer because it uses an equivalent mathematical form, a different convention or a representation the rule-based grader does not recognize. When models are weak, such false negatives are relatively rare because correct answers are rare. As correct answers become more common, evaluator defects account for a larger fraction of the remaining measured error.
The study gives a concrete example from PHYBench where a mathematically equivalent answer receives zero credit because an expression-edit-distance rule does not recognize the equivalence. The authors also find faulty reference solutions and questions that omit assumptions required to determine a unique answer.
Artificial Analysis currently includes CritPt and Humanity's Last Exam in its broader Intelligence Index and documents the grading pipelines it uses. That makes this result relevant beyond academic benchmark design. Composite scores can inherit failure modes from the component tests, even when the aggregation itself is transparent.
Evaluation debt can distort model-selection decisions
The practical consequence is not that organizations should stop using benchmarks. It is that high-stakes evaluation pipelines need an escalation path for apparent failures.
When a benchmark is used for model procurement, routing, release gating or capability claims, the last few percentage points increasingly deserve forensic review. A fixed answer key plus an automated grader may be cheap and reproducible, but near the benchmark's capability ceiling it can measure the evaluator as much as the model.
A more defensible pipeline would separate at least three questions: Was the task well posed? Was the reference answer correct? Did the grader correctly recognize an equivalent valid response? For difficult domains, a sampled expert audit can then estimate how much of the residual error belongs to each layer.
This is an evaluation-governance issue as much as a benchmarking issue. If a company changes model routing, access or spending based on a composite score, unmeasured grader error becomes a hidden control-plane input. The paper suggests that benchmark quality should therefore carry its own uncertainty and maintenance record rather than being treated as static ground truth.
The study does not prove research-level autonomy
The authors explicitly limit their claim to closed-ended physics questions with verifiable final answers. The study does not test whether a model can formulate a novel research problem, choose productive experiments, sustain an open-ended investigation or recognize when the scientific framing itself is wrong.
There is also a selection effect in the audit. For several benchmarks, experts concentrate on cases where all GPT-5.6-Sol attempts had initially been marked incorrect. Corrected evaluations then exclude or repair defective questions. That is appropriate for diagnosing the benchmark, but it means the corrected numbers should not be read as a drop-in replacement for every previously reported leaderboard score.
The paper is an arXiv preprint, not evidence of independently verified peer review. Aipolix also found no separate official code or dataset release attached to the paper during this run, which limits reproducibility beyond the detailed methods and examples in the manuscript.
The benchmark now needs a benchmark
The strongest takeaway is methodological. Frontier-model evaluation is entering a regime where the test infrastructure itself needs continuous validation.
For teams running internal evals, the practical response is to log grader disagreements, preserve model outputs, sample failures for expert review and version reference answers alongside the benchmark. When scores approach saturation, adding harder and better-validated tasks may be more informative than squeezing another decimal point out of a noisy test.
That changes the meaning of “benchmark performance.” A score is not only a property of a model. It is the output of a system consisting of tasks, reference material, sampling settings, tools and a grader. This paper shows that defects in those surrounding components can be large enough to reverse the story the number appears to tell.