Agents
-
Agents
Cursor pushes coding agents past the pull request with Rollouts and Security Review
Rollouts and Security Review extend Cursor agents from pull requests into deployment health and exploit-path security review.
-
Research
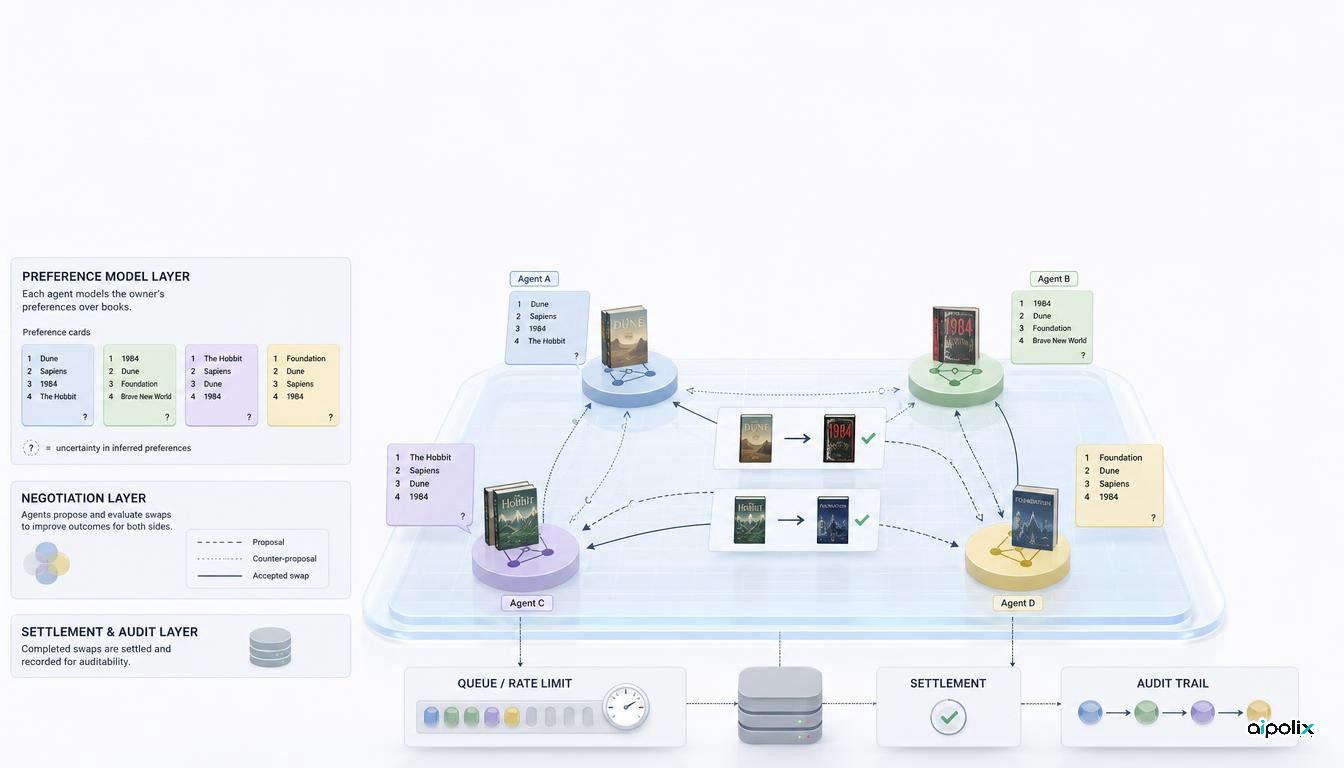
Anthropic's Project Swap finds the hard part of agent markets may be knowing what people want
Anthropic's 201-person Project Swap experiment suggests agentic markets may be limited more by understanding user preferences than by bargaining skill.
-
Research
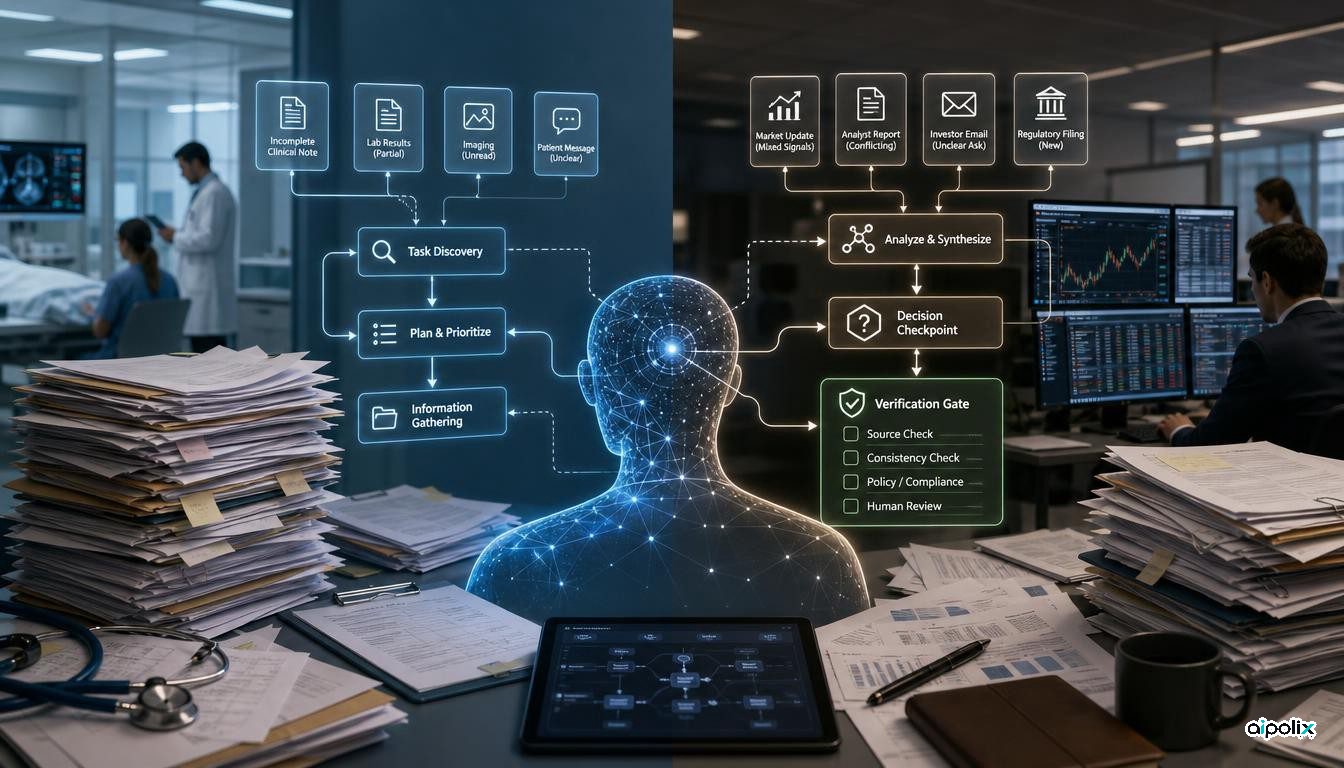
DAYJOB exposes the gap between agents that follow instructions and agents that can do a job
Surge AI’s DAYJOB benchmarks test long-horizon healthcare and finance agents on messy, underspecified work. Top reported pass rates remain below 25%.
-
Research
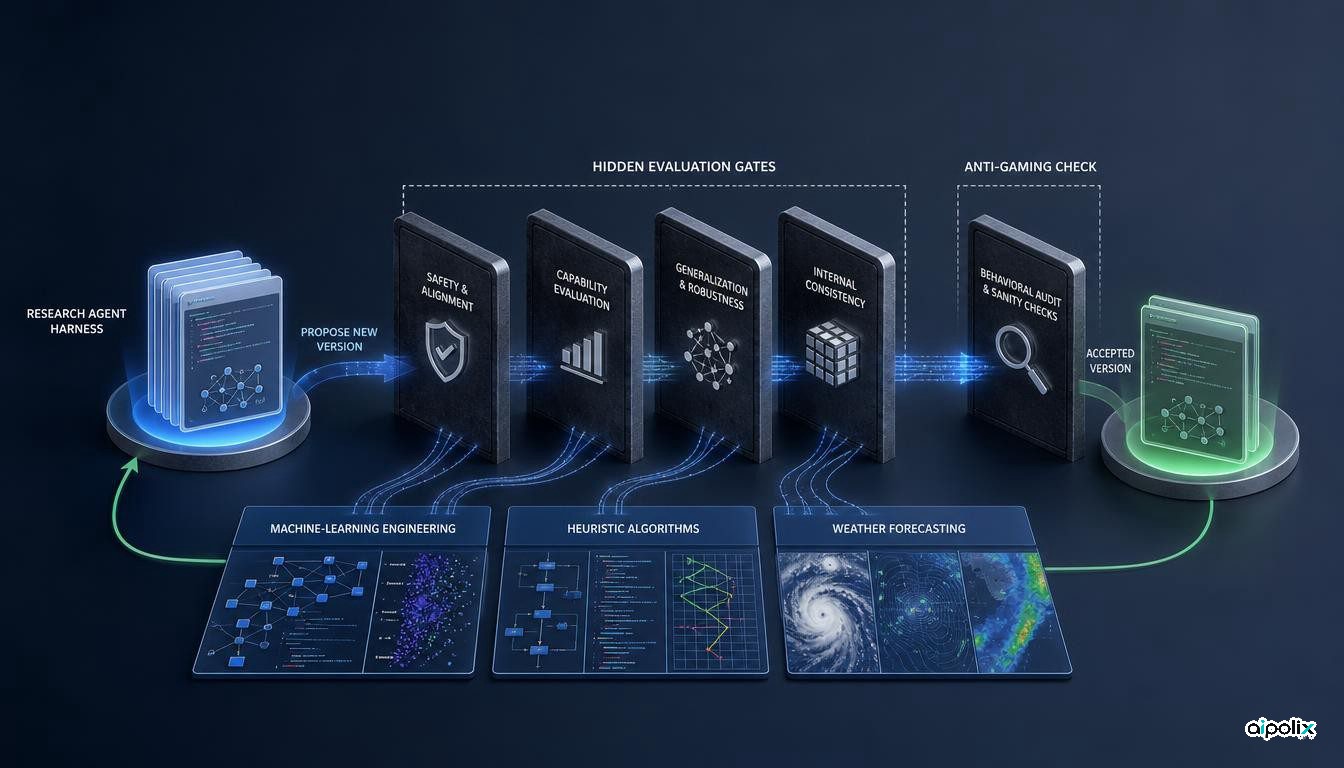
AIDE² rewrites its own research-agent harness, but hidden evaluations decide what survives
AIDE² repeatedly rewrote its own research-agent harness in an eight-day experiment. Held-out tests suggest transfer, while the evaluation gate remains the key control boundary.
-
Research
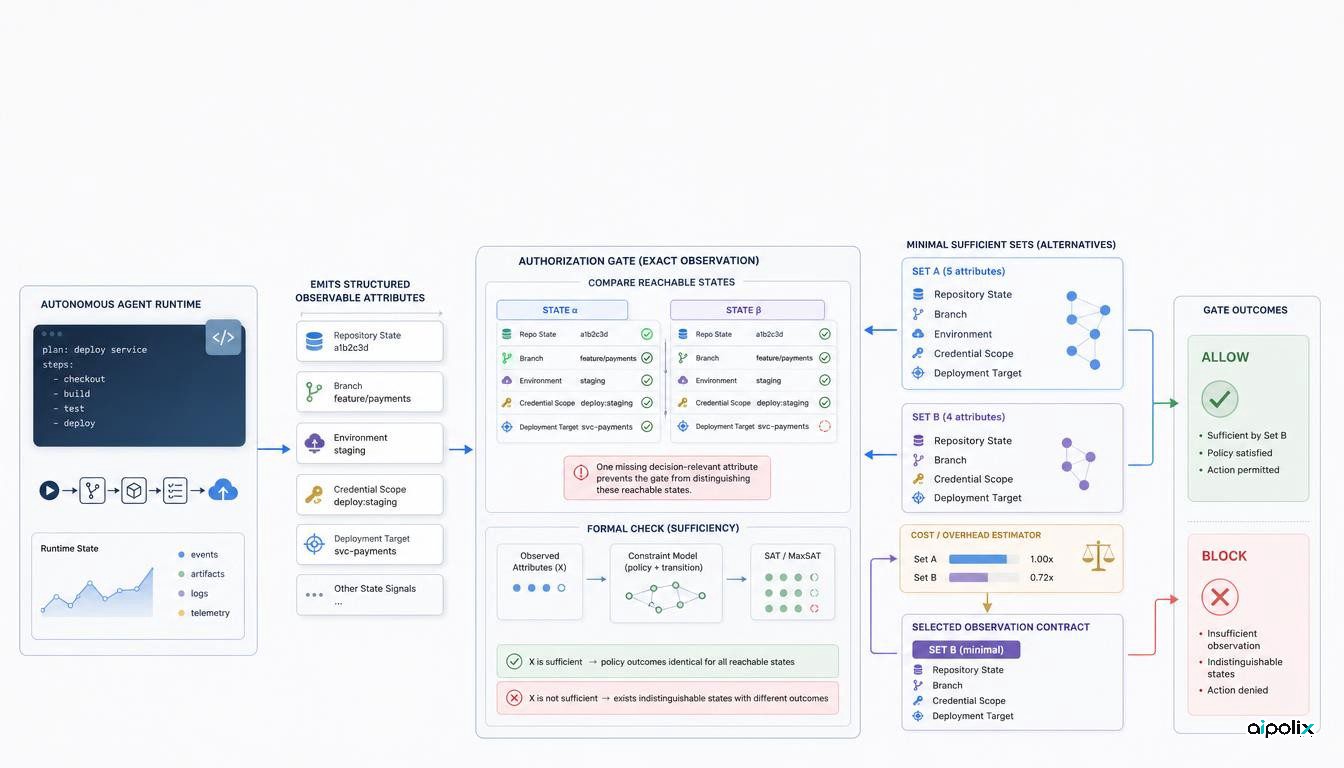
Agent governance needs enough context to decide, not just more policy
New research formalizes how to derive the minimum runtime observations an agent authorization gate needs, with reproducible code and clear limits.
-
Agents
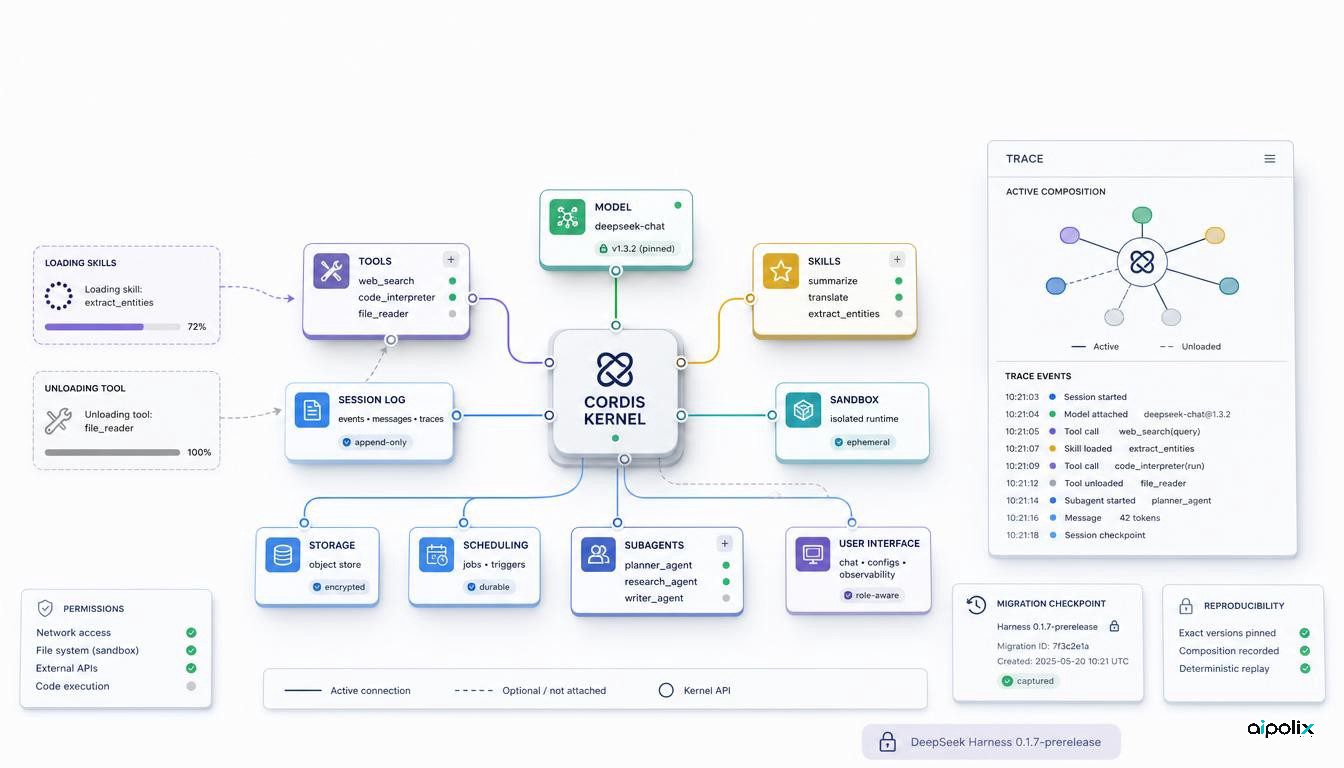
DeepSeek Harness 0.1.7 turns agent configuration into a runtime plugin surface
DeepSeek Harness 0.1.7 makes agent capabilities more dynamically composable. Aipolix examines the benefits and the new operational risks.
-
New Models
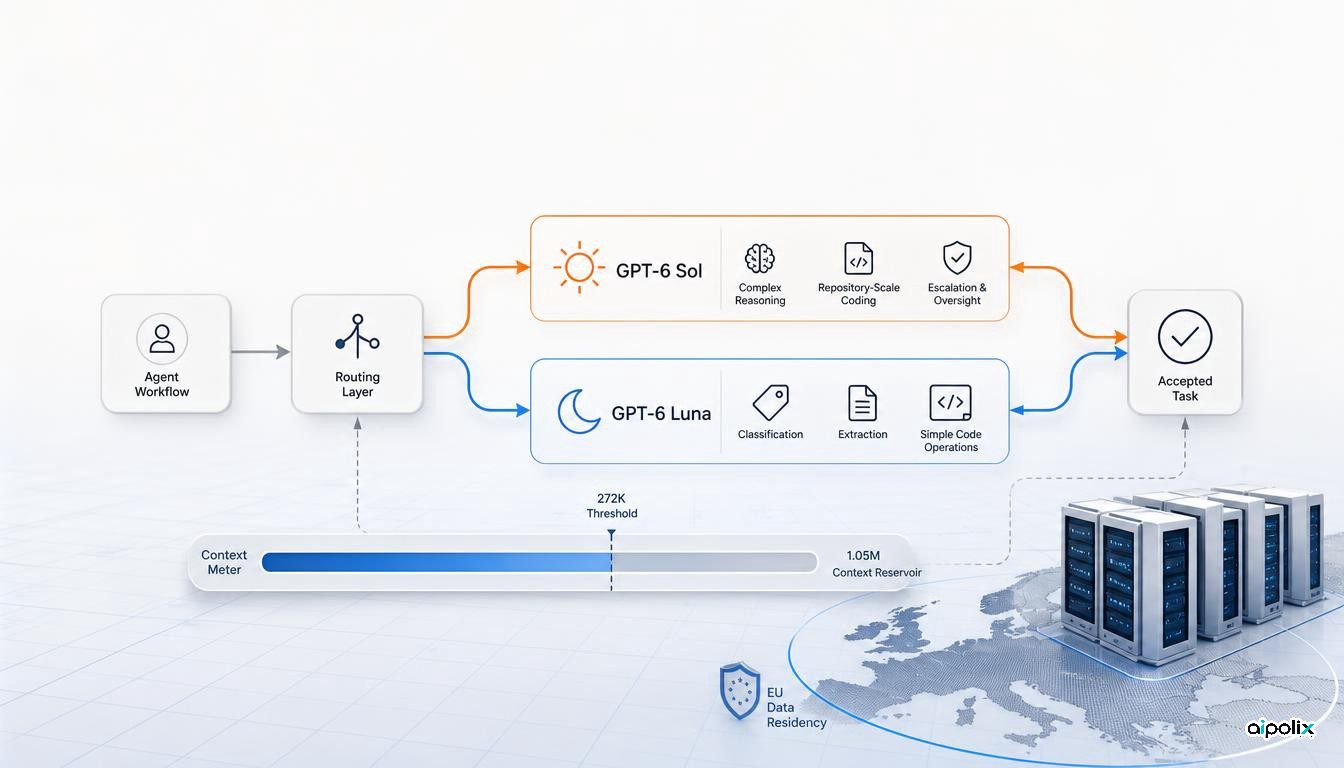
GPT-6 Sol and Luna make model routing a first-order agent economics decision
GPT-6 Sol and Luna introduce a 20x price spread, large context and different cost boundaries. Aipolix examines agent routing economics.
-
New Models
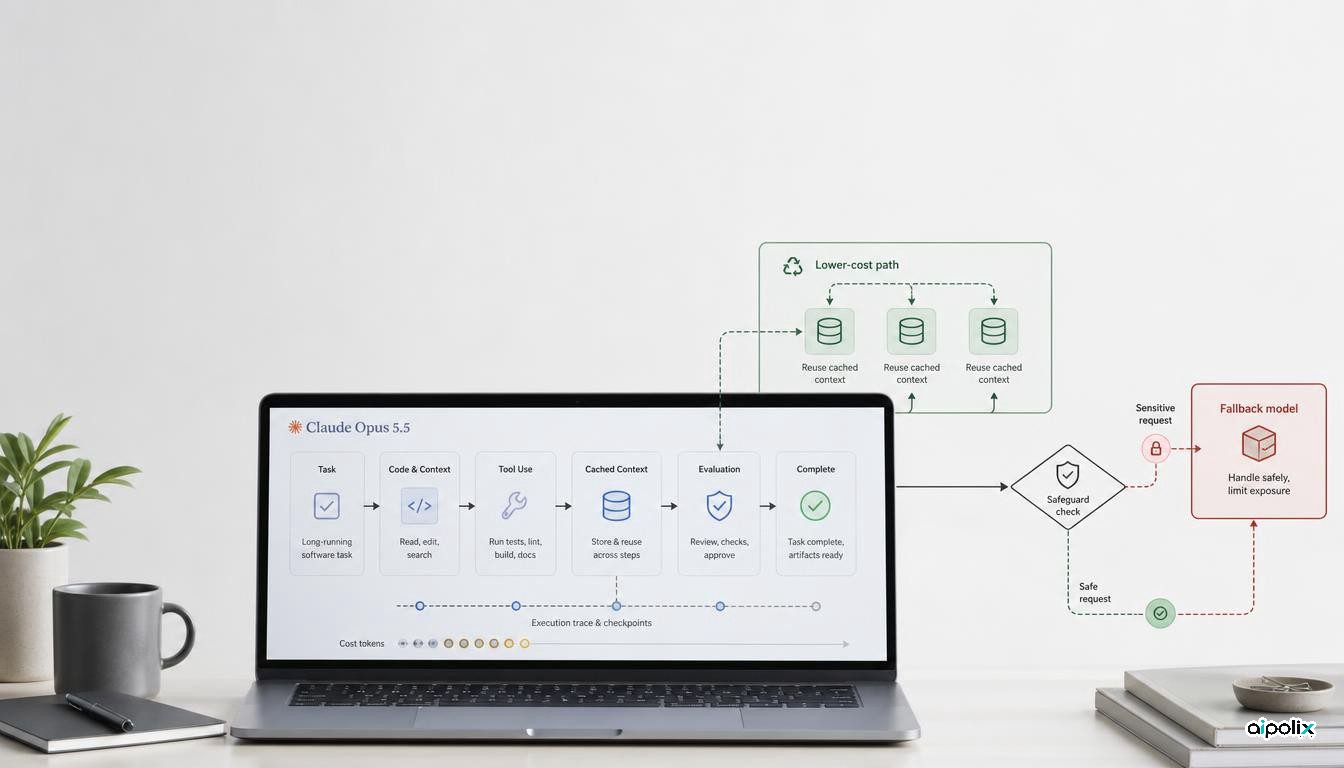
Claude Opus 5.5 cuts agent costs, but safeguard routing changes how teams should evaluate it
Claude Opus 5.5 cuts token and cache costs while sensitive requests may use fallback models. Aipolix examines the impact on agent evaluation.
-
New Models
Grok 4.7 keeps token prices flat, but agent economics depend on the full task
Grok 4.7 keeps basic API token rates unchanged, but independent tests show higher output consumption and provider-specific long-context pricing.
-
Agents
Plugin4Shell exposes a gap in coding-agent plugin checks; patched clients still need an integrity audit
What Plugin4Shell changes about Git-pinned plugins in Claude Code, Codex, Copilot and Gemini CLI, with qualified patch status and an audit plan.